AI
Sentence Transformers v6.1 Makes Input Order Part of Your Index
Sentence Transformers keeps familiar calls, but v6.1 changes structured-message ordering. A pinned audit separates index compatibility, Qwen prompts and reranker scores.
Can I upgrade multimodal search without rebuilding its index?
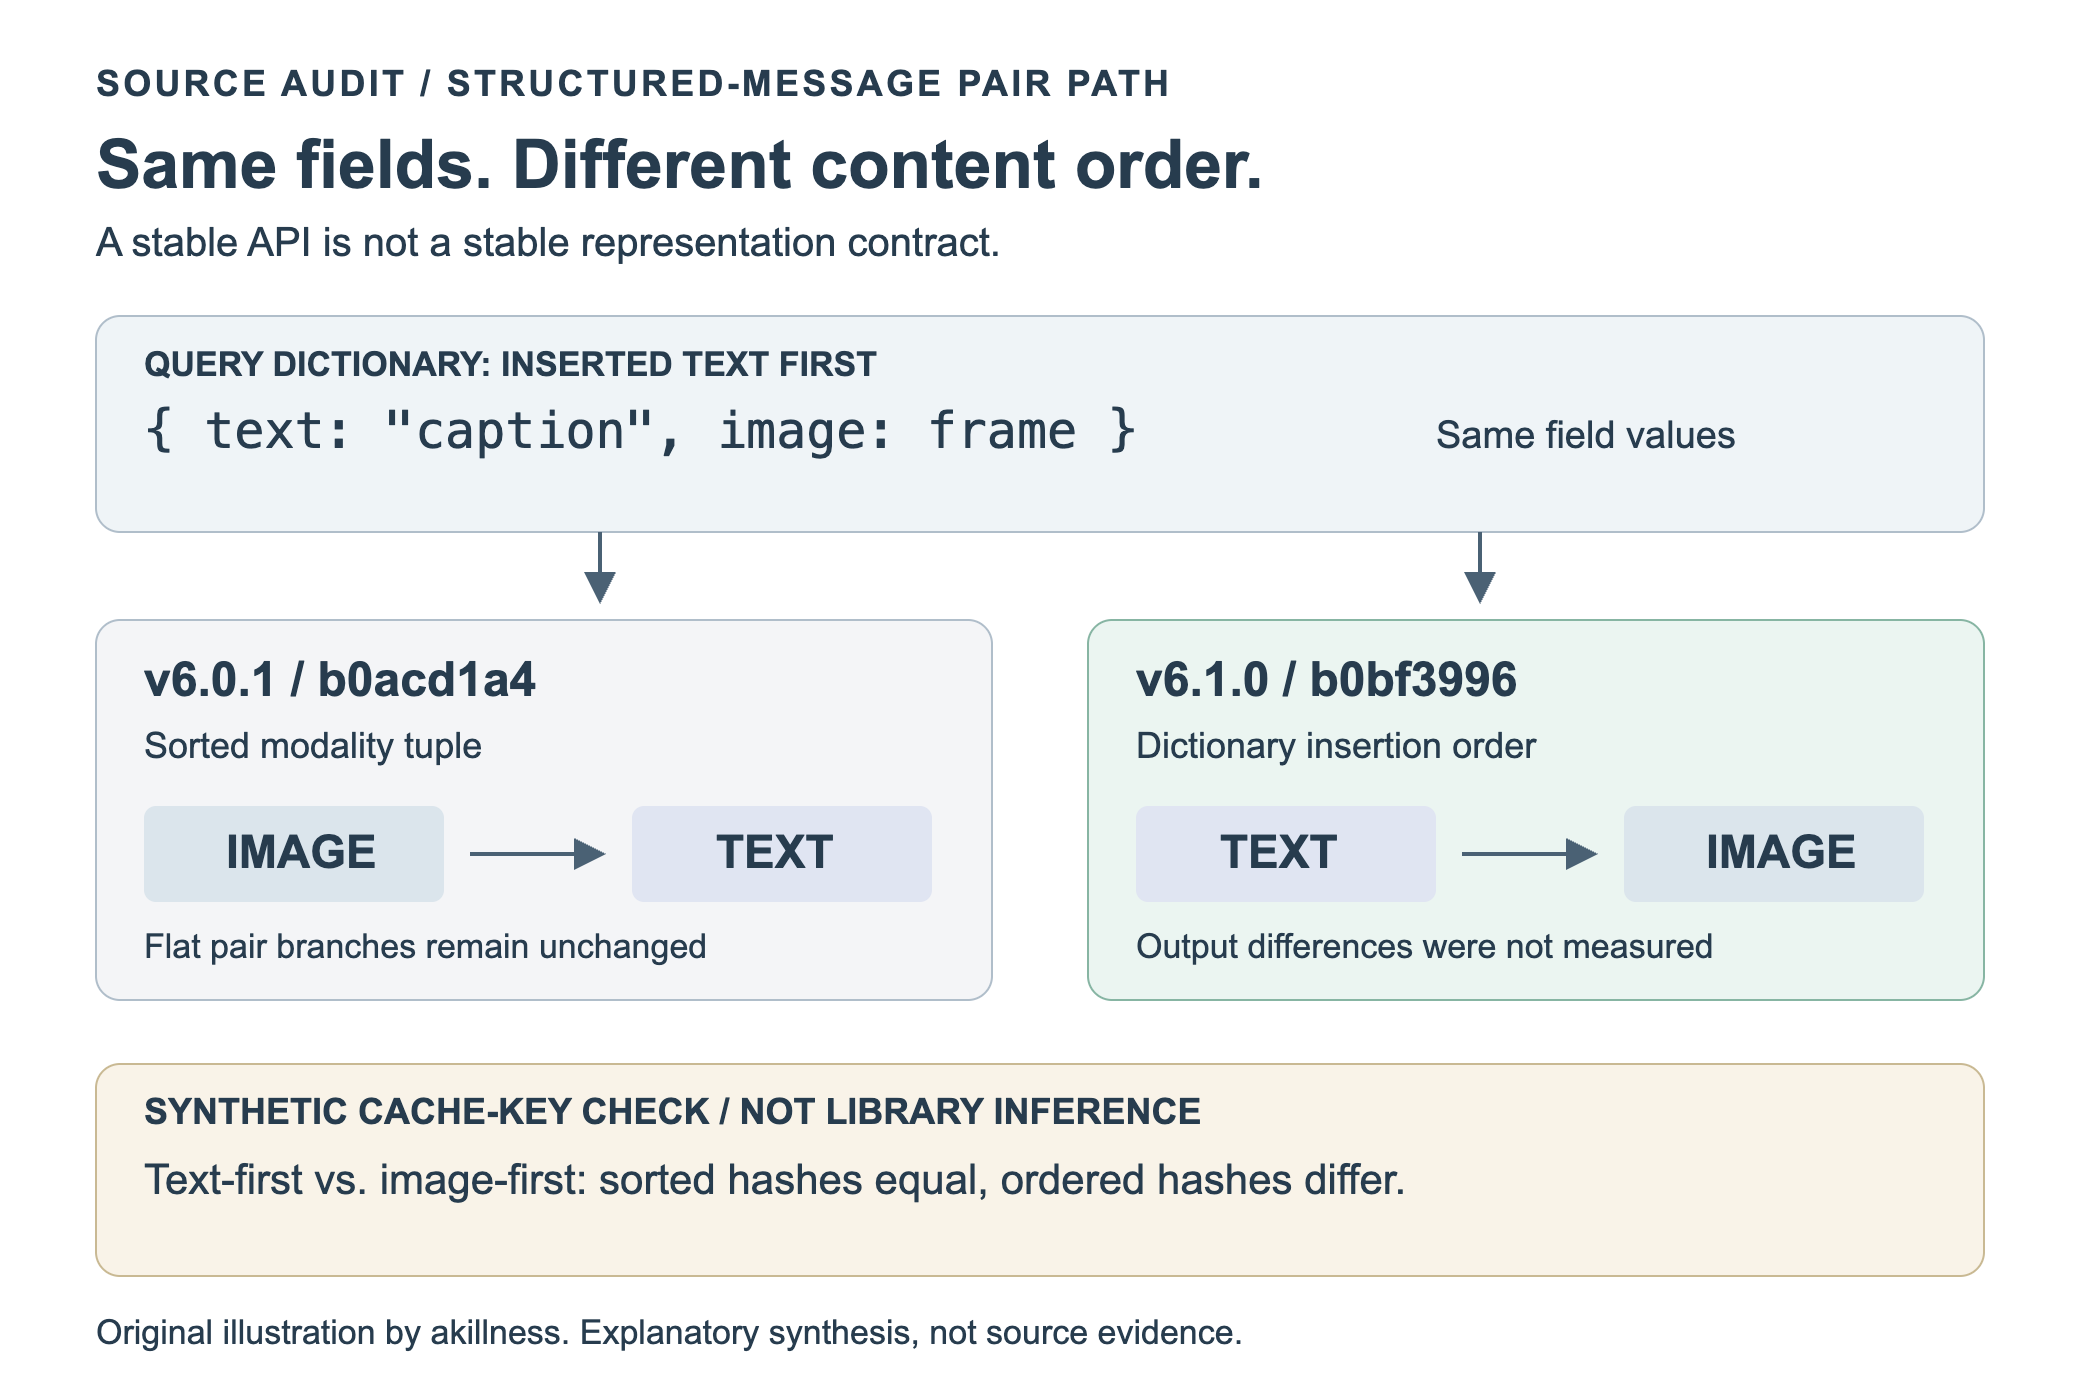
Not merely because encode() and rank() still accept the same-looking inputs. The September v6.1.0 release changed how multimodal dictionaries become structured messages, the format declared by the inspected Qwen checkpoints. A caption-and-image object in that path can therefore produce a different content sequence after an upgrade, even when the model name, field values and embedding dimension stay unchanged.
The source-level finding is narrower than a performance claim: input serialization changed. I did not measure an embedding delta or a retrieval regression. But the change exposes an application-level trap worth checking: a cache key that sorts dictionary fields can regard two inputs as identical while the formatter preserves their different orders.
This is the part missing from my April note’s “familiar API” framing. A convenient interface reduces glue code. It does not define a stable index contract. For screenshot search, that contract also includes preprocessing, prompts, vector representation and score interpretation.
The structured pair formatter changes the input
The v6.1.0 release notes, published September 18, explicitly warn that multimodal dictionary content now follows each input’s key order and that this can change embeddings or scores. I compared the formatter at v6.0.1 commit b0acd1a4 and v6.1.0 commit b0bf3996 rather than infer behavior from the version number.
In the older structured-message CrossEncoder pair path, infer_modality() produces a sorted tuple of modality names. pair_to_messages() iterates that tuple to construct the content for each member of the pair. For a query dictionary inserted as {"text": "caption", "image": image}, the alphabetical order is image, then text.
In v6.1.0’s structured-message conversion, pair_to_messages() passes each multimodal dictionary through to to_message(), which walks its .items(). That same query now contributes text, then image. The query role still precedes the document role; it is the order within the query’s content that changes.
Both versions’ message_format == "flat" pair branches pass content through; the comparison above is specifically the structured-message branch. Do not generalize it to every embedding call.
For ordinary batches, v6.0.1 grouped same-modality dictionaries using the first sample’s key order. In v6.1.0, if those dictionaries have different key orders, parse_inputs() converts each sample separately to messages only when supported modalities are unrestricted or include message. Otherwise, grouped inputs still use the first sample’s key order. batch_to_message() alone does not independently preserve different per-sample dictionary orders.
| Inspected boundary | Earlier behavior | v6.1.0 behavior | Migration implication |
|---|---|---|---|
| Structured-message dictionary inside a pair | Iterate sorted modality names | Preserve that dictionary’s insertion order; flat pair branch is unchanged | Compare actual content sequences, not just fields |
| Same-modality batch with different dictionary key orders | Group using first sample’s key order | Convert per sample only if modalities are unrestricted or include message; otherwise retain first-input grouping | Test the model’s supported-message condition as well as heterogeneous batches |
| Model weights | Not changed by this formatter comparison | Not changed by this formatter comparison | A weight revision alone cannot identify preprocessing |
| Embeddings and ranking quality | Not measured here | Not measured here | Source evidence identifies a risk, not its magnitude |
A sorted cache key can hide a changed content sequence
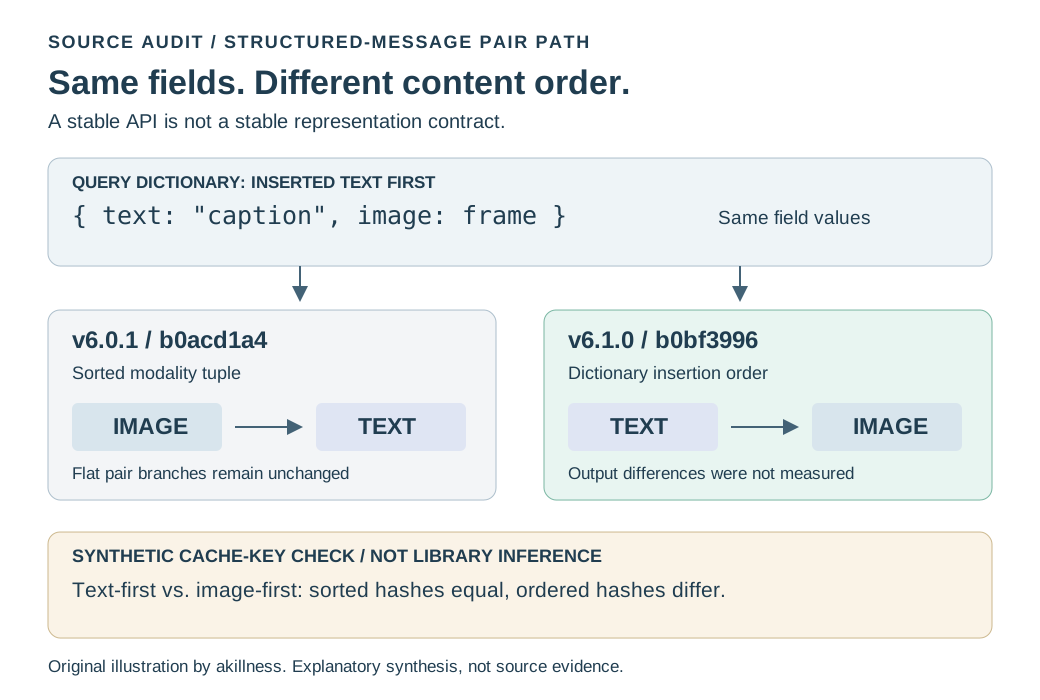
Suppose one producer emits the caption before the screenshot, while another emits the screenshot before the caption. A key-sorted fingerprint collapses both dictionaries into the same normalized representation. That can be useful when object-field order is intentionally irrelevant. It is not sufficient when the next stage uses that order to assemble model content.
I ran a small Node.js fixture on October 14, 2026, at 14:30 KST, using Node v26.5.0 on macOS arm64. It checked only application serialization:
Save this self-contained check as input-order-fixture.mjs, then run node input-order-fixture.mjs:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
import assert from "node:assert/strict";
import { createHash } from "node:crypto";

const textFirst = { text: "caption", image: "frame.png" };
const imageFirst = { image: "frame.png", text: "caption" };
const sortedFields = input =>
  JSON.stringify(Object.entries(input).sort(([a], [b]) => a.localeCompare(b)));
const orderedParts = input =>
  Object.entries(input).map(([type, value]) => ({ type, value }));
const sha256 = text => createHash("sha256").update(text).digest("hex");

assert.equal(sortedFields(textFirst), sortedFields(imageFirst));
assert.notDeepEqual(orderedParts(textFirst), orderedParts(imageFirst));
assert.equal(sha256(sortedFields(textFirst)), sha256(sortedFields(imageFirst)));
assert.notEqual(
  sha256(JSON.stringify(orderedParts(textFirst))),
  sha256(JSON.stringify(orderedParts(imageFirst)))
);
console.log("4 synthetic serialization assertions passed");
All four recorded assertions passed: the normalized field representations were equal; the ordered part arrays differed; their normalized SHA-256 hashes were equal; and the hashes of the ordered arrays differed. The public snippet contains the same four assertions as the saved internal fixture.
This was not a run of Sentence Transformers, its Python formatter or a Qwen model. The fixture proves a failure mode in the illustrated cache-key design. The connection to model input order comes from the separately inspected formatter source. It does not prove that two resulting vectors differ, that a particular cache is defective, or that all indexes need rebuilding.
My inference is practical: identify an index by the effective input contract, not just the checkpoint name. Record the library version, model revision, prompt, processor configuration and ordered content representation. If preprocessing changes, compare affected samples and evaluate the migration before mixing newly encoded queries with an old corpus. Re-encode affected documents when that assessment establishes that their representation changed; do not treat a version bump alone as a universal reindex instruction.
Qwen’s helper names do not create specialized prompts
The current official Qwen3-VL-Embedding-2B snapshot 9f2f7e71 declares text, image, video and structured message modalities. It does not declare audio. Installing Sentence Transformers’ audio extras does not turn that checkpoint into an audio encoder.
Its Sentence Transformers config defines only a default prompt: Represent the user's input. It has no specialized query or document prompt strings.
At the pinned v6.1.0 source, encode_query() chooses a query prompt if one exists and passes task="query". encode_document() searches document, passage, then corpus prompts and passes task="document". For this Qwen config, neither helper finds a specialized prompt, so BaseModel._resolve_prompt() uses the configured default when no explicit prompt override is passed. A task label is not itself a new instruction; the helpers document task routing for models with a Router module.
This is not a criticism of using the helpers. They remain useful interface choices. The mistake is assuming their names establish different natural-language instructions for every model. If a retrieval task needs a custom instruction, make that choice explicit, record it with the index and evaluate it rather than silently attributing a generic default to task-specific training behavior.
Likewise, BaseModel.modalities and supports() report declared model compatibility. They do not download a URL, inspect its contents, verify a processor run or establish retrieval quality. A checkpoint supporting images can still receive an ambiguously typed string.
A reranker score is not a confidence percentage
The pinned Qwen3-VL-Reranker-2B snapshot 4bd860ac uses a LogitScore module with yes/no token IDs and configures Identity activation. The inspected module computes the yes-token logit minus the no-token logit. Default prediction therefore returns an order score, not an already calibrated probability of relevance.
The model card shows an explicit sigmoid option. Mapping a raw score into the range zero to one is not, by itself, evidence of calibration against the application’s relevance labels. A screenshot ranked first can still fail to contain the chart, UI state or bug evidence the user actually needs.
The April note blurred this distinction with “rerankers decide” and “high-precision results.” A reranker orders candidates. An application still has to decide whether the evidence is sufficient, and that decision requires its own labelled evaluation and failure policy. The related RAG versus Jev audit examines the separate boundary between ranking and answerability; this article’s narrower issue is preserving the multimodal input and score contract before making that downstream decision.
What changed since the April 11 note?
Three concrete changes matter more than another model list.
First, the current pinned Qwen embedding and reranker model cards show loading by model ID without the old refs/pr/23 and refs/pr/11 workarounds. Those references were integration pull-request examples, not permanent prerequisites. For a reproducible deployment, pin the inspected model commit and a compatible library environment, not a floating PR branch copied from an old tutorial. I inspected configuration and documentation; I did not verify a fresh model load.
Second, the August 18 multi-vector guide describes v6.0’s MultiVectorEncoder. Instead of one vector per input, late-interaction models retain token-level vectors and score with MaxSim. That is a different output and indexing contract, not a drop-in replacement for a single-vector cosine index. The addition broadens the toolkit; it does not mean Qwen’s dense embedding model automatically became a multi-vector encoder or that one representation is best for this workload.
Third, v6.1.0 changes multimodal input assembly, including frame-list handling. The formatter treats a bare list as video frames only when every item is inferred as an image. Extensionless frame URLs can miss that inference. The explicit form {"video": {"array": frame_urls, "video_metadata": None}} identifies one video and keeps the collection together. None does not supply the original timestamps, and the wrapper does not prove the remote frames are accessible or valid.
The official release API reported v6.1.0 as the latest release when checked on October 14. That is a dated observation, not a reason to upgrade without comparing contracts.
Keep representation tests separate from retrieval tests
For a game-QA screenshot corpus, I would start with a small migration set containing caption-and-image dictionaries in both insertion orders, mixed batches, local image paths and extensionless media URLs. Those are proposed cases derived from the inspected formatter, not evidence from a shipped game system.
Inspect the assembled content and selected prompts first. Then run real encoding and retrieval checks in the target environment, retaining the model revisions and processor settings. Keep quality, latency, memory and calibration results separate. None of those measurements was performed in this audit.
For ranking evaluation, include visually similar but semantically wrong screenshots: the right dashboard layout with the wrong metric, or the right inventory panel without the reported overlap. Preserve document identity when mapping a reranked shortlist back to the corpus. Do not interpret a successful model load, a recognized modality or a large relevance score as proof that the answer is supported.
The CRAG benchmark rebuild gives a complementary reason to keep unsupported answers separate from correct ones. Here, the first checkpoint is earlier: make sure the index and query were produced under a contract you can name and reproduce.
Key Takeaways
- Version preprocessing with the index. v6.1.0 preserves dictionary order in structured-message pairs; mixed-order batch conversion also depends on declared message support. The flat pair branch is unchanged.
- Do not use an unordered fingerprint for an ordered model input. The synthetic check demonstrates this cache-key mismatch, not a model-output regression.
- Read model config, not helper names. The inspected Qwen embedding snapshot has one generic default prompt and does not declare audio support.
- Treat raw reranker outputs as scores. Identity activation and yes/no logit differences do not establish calibrated application confidence.
- Evaluate only the claims you actually measure. This audit establishes source-level contracts and one synthetic serialization result, not inference performance or a required universal reindex.
New Questions
- How many corpus items change effective content order when an existing deployment moves from v6.0.1 to v6.1.0?
- Does a task-specific instruction improve screenshot retrieval under a labelled evaluation, compared with the checkpoint’s generic default?
- Would dense embeddings or late-interaction retrieval better recover small UI details at the workload’s measured index-size and latency budget?
References
All sources were read on 2026-10-14. Library and model claims are pinned below; live documentation and release metadata are dated observations.
Release and version-pinned library source
- Sentence Transformers v6.1.0 release, published September 18, 2026; latest-release API, observed October 14. The release’s ordering warning is not a measured output delta in this audit.
- v6.0.1 formatter, commit b0acd1a4:
infer_modality,pair_to_messages, and groupedparse_inputs. - v6.1.0 formatter, commit b0bf3996:
pair_to_messages,to_message, batch conversion,_is_video_framesand_unwrap_video. - v6.1.0 BaseModel prompt resolution and modality checks:
_resolve_promptat lines 344–369 andmodalities/supportsat lines 380–420. - v6.1.0 query/document helpers and LogitScore implementation. These are static code inspections, not executed inference.
Model configuration and current official usage
- Qwen3-VL-Embedding-2B, commit
9f2f7e710d6d81056aa5c0a4f04764fec6bb7bda: prompt config, modality config, and model card. - Qwen3-VL-Reranker-2B, commit
4bd860ac4f15ad1897a214615cccc700f8f71818: activation and prompt config, yes/no token config, and model card.
Original guide and later survey
- Multimodal Sentence Transformers guide, published April 9; pinned Markdown.
- Multi-vector encoder guide, published August 18; pinned Markdown. Used for the representation survey, not as a local efficiency benchmark.
Editorial method: claims in this article point to primary documentation, pinned source code, runnable checks, or dated measurements, with AI-assisted research under the site's evidence-gated policy. How this site verifies claims and discloses AI assistance · Report a correction.
Working on something like this?
I take a small number of paid, scoped reviews: AI agent/RAG architecture diagnosis, Unity CI & build-automation audits, and multimodal QA design review. Each one ends in a written findings document.
Work with me