AI
Feynman Research Recovery Is Not Evidence Assurance
A pinned source audit of Feynman v0.5.47 separates signed-in alpha tools, abstract-only fallbacks, prompt context, and conditional telemetry error capture.
What does Feynman’s current release actually establish?
The useful question is not whether a research agent can call more paper sources. It is what an engineer can safely conclude when a call fails, a fallback returns, or a telemetry event is constructed. I re-read the pinned Feynman repository at commit c8d84cd1939a018a930272f48d16f79da8ec249b and found a narrower result than the restored April headline: recovery is visible at several tool boundaries, but recovery is not evidence assurance.
The pinned package.json declares version 0.5.47 and engines.node as >=22.22.0. Those are package declarations, not an installation or runtime result; I did not install Feynman or run its providers. The release notes describe three nearby changes: v0.5.45 paper lookups recover instead of failing, v0.5.46 resolves recent arXiv papers by DOI, and v0.5.47 updates pi-web-access. The notes call the first two releases 2026-10-13, while GitHub’s release API reports publication on October 14 for v0.5.45 and v0.5.46, and October 15 for v0.5.47. Release-note headings and publication timestamps are different metadata surfaces.
That distinction sets the reading rule for the rest of this audit: a label, a fallback object, or a prompt requirement is evidence about that surface. It is not automatically evidence that a final research artifact is complete, compliant, or preserved.
| Inspected surface | What the pinned source supports | What it does not establish |
|---|---|---|
package.json | Declared 0.5.47 package version and Node >=22.22.0 floor | Installed compatibility or successful runtime |
current-date.ts | A local date and freshness instruction are constructed before agent start | Fresh retrieval, correct citations, or model compliance |
alpha.ts | Account-gated direct tools and labeled fallback branches | Full text, an answered question, or guaranteed fallback success |
telemetry.ts | Conditional error fields and a bounded errorText transform | Network delivery, retention, general redaction, or downstream use |
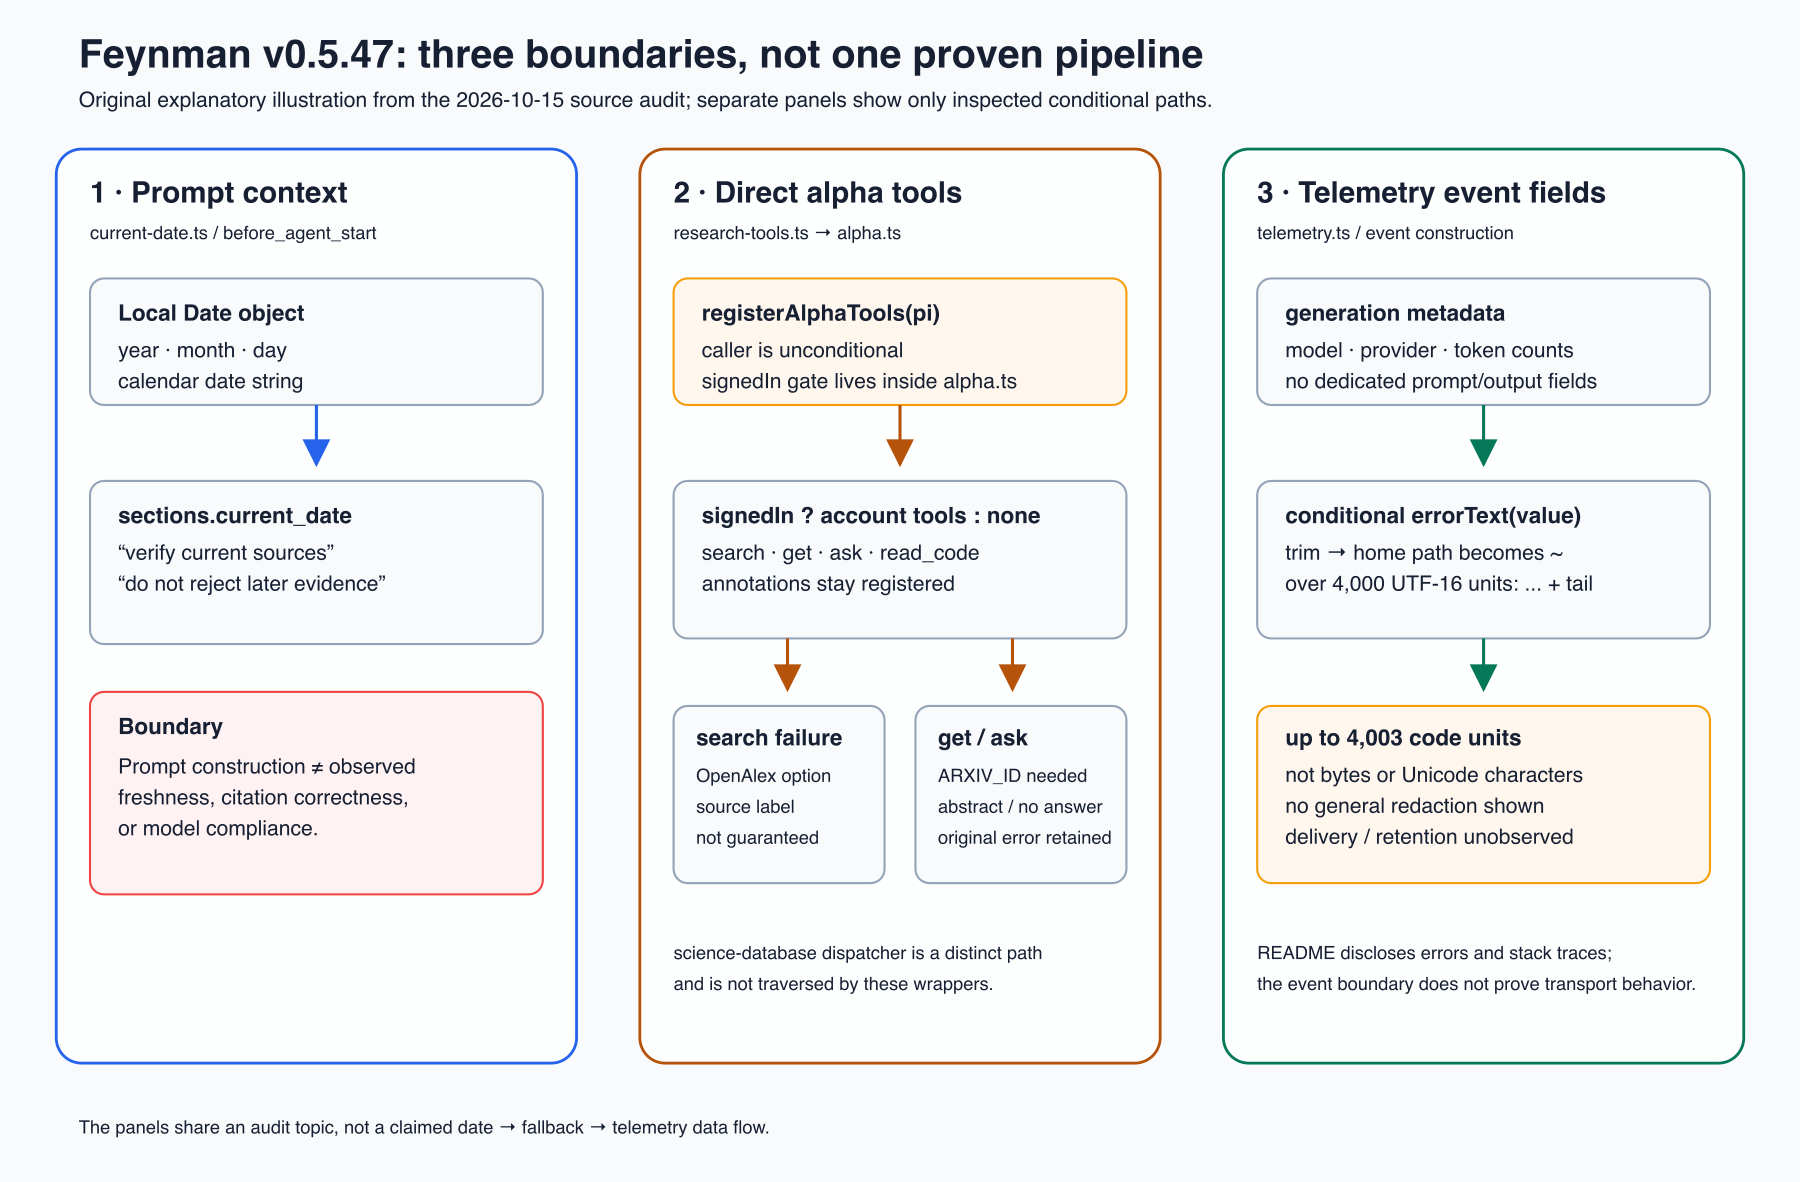
Open the transparent SVG source of this original diagram.
Where does freshness enter—and what remains unobserved?
current-date.ts builds a string from a supplied Date: “The current date is YYYY-MM-DD,” followed by instructions to verify current sources and not reject evidence merely because it is later than the model’s training data. registerCurrentDateResearchContext installs that text in event.systemPromptOptions.sections.current_date inside a before_agent_start handler.
This is prompt construction. It is not an observation that a source was fetched recently, that a citation matches the source, or that a model followed the instruction. The local-calendar value can help a workflow frame a question, but it does not become a freshness receipt. A final report still needs its own source URLs, pins, dates, and claim checks.
The README makes a related provenance promise: source-heavy workflows write provenance files, and prompts, model output, paper content, and tool arguments are excluded from the stated telemetry payload. The same README explicitly discloses errors and stack traces. The right reading is not “provenance is automatic” or “no research text can ever appear.” It is that a workflow requirement and a telemetry policy need to be checked against the actual output and event construction separately.
Which alpha tools need sign-in, and when is recovery only a smaller answer?
The registration boundary is easy to misstate. The research-tools.ts caller invokes registerAlphaTools(pi) unconditionally. Inside alpha.ts, registerAlphaTools computes registerAccountTool from signedIn; account-dependent direct wrappers are registered only when that condition is true. The guarded set includes alpha_search, alpha_get_paper, alpha_ask_paper, and alpha_read_code. The local annotation tools are registered outside that guard. This is a registration-time condition, not proof of fresh authorization on every invocation, successful sign-in, or provider availability.
The direct wrappers share a withPaperFallback helper. When an alphaXiv call throws, the helper can try an explicitly named fallback and returns a fallbackNote that says the result came from that other source. That label is useful provenance at the tool-return boundary. It is not a claim that the replacement has the same scope as the failed operation.
For alpha_search, the fallback option is OpenAlex semantic search. The source makes that option available after an alpha failure, but no live run here shows that it returned results, how complete those results were, or whether a model used them correctly.
alpha_get_paper and alpha_ask_paper are narrower. Their fallback is offered only when ARXIV_ID can extract an identifier from the input. The get path asks arXiv for metadata and an abstract, explicitly “no full text or sections.” The ask path says the question was not answered and points the reader to the abstract or to reading the full text with fetch_content. If no ID is extractable, or if the fallback itself fails, withPaperFallback throws a new error that retains the original alphaXiv message and appends recovery guidance naming feynman_science_database_search or an arXiv fetch.
That means a recovered object can be useful while still being materially smaller than the requested evidence. Metadata is not full text. An abstract is not a selected methodology or results section. A recovery hint is not a completed answer. The direct alpha wrappers also do not traverse the separate science-database dispatcher recovery path; that dispatcher is a distinct surface. This analysis must not be generalized to alpha_read_code, which has no equivalent fallback in the inspected wrapper.
Why is a fallback result not the same as evidence assurance?
The source gives an engineer a practical audit rule. Keep at least four columns in a research record: requested operation, returned source, returned scope, and final-artifact check. A successful fallback can fill the second and third columns without filling the fourth.
For example, a search result labeled “OpenAlex semantic search” tells us that the wrapper substituted a named source if the alpha call failed. It does not prove the list was complete. An arXiv metadata response can preserve an identifier and abstract while leaving the paper’s methods, experiments, and limitations unread. A provenance-writing prompt can request a sidecar while leaving actual sidecar creation and contents uninspected. Those are not accusations about the project; they are the limits of the code and sources I inspected.
This is also why the original “thinks beyond search” superiority framing does not survive the rebuild. No controlled citation-accuracy or research-quality comparison was run, and no product execution was authorized. The defensible contribution is a decision boundary: do not promote a recovered tool call to sufficient evidence until the source scope and final artifact are checked directly.
For a measurement-oriented companion, read Harness engineering for agents. It helps define a controlled task environment, execution protocol, and scoring evidence before a result is treated as a comparison. For a complementary handoff perspective, Engineering discipline for AI coding agents distinguishes a declared worker-validator contract from proof that an enforced path actually ran. Neither related article is evidence about Feynman’s runtime; each is a next method for making the missing checks explicit.
What does telemetry capture at the error boundary?
The inspected message_end handler builds $ai_generation events with model, provider, token counts, cache counts, latency, HTTP status, stop reason, and a conditional $ai_error. It does not include dedicated $ai_input or $ai_output_choices fields. Separately, tool_execution_end adds error_message only when a tool result is marked as an error. These are client-side event-construction paths.
The errorText helper first accepts only a string, drops empty trimmed values, trims the rest, and replaces the configured home-directory spelling (including slash-normalized form) with ~. When the resulting JavaScript string is longer than 4,000 UTF-16 code units, it returns three dots followed by the final 4,000 code units. The maximum is therefore 4,003 UTF-16 code units, not 4,000 bytes and not a guarantee about Unicode characters. The helper shows no general redaction pass.
The README already tells users that errors and stack traces can be sent. The source audit does not show hidden undisclosed telemetry, guarantee that no content can occur inside an error string, or observe network delivery, server retention, provider processing, or downstream access. Missing dedicated prompt/output fields are therefore not a blanket privacy guarantee. They are an inspected schema boundary with a conditional error-text exception.
These observations are intentionally separate from date context and paper recovery. The inspected files do not establish a serial “date → fallback → telemetry” pipeline, and the article does not invent one.
What changed since the April note?
The April note presented Feynman as a v0.2.17 research-first CLI and carried broad claims about role separation, reproducibility, distribution, and future production value. This redevelopment does not treat those claims as current evidence. It preserves the original April 10 date and URL, but answers a different question from a pinned October 15 source inspection.
The current package declares 0.5.47, and the current release notes and API metadata provide a narrow release-window view: the .45 and .46 headings say October 13 while GitHub lists their publication on October 14; .47 is listed and published on October 15. That is a metadata chronology, not proof that every inspected mechanism was introduced after April. The current source also exposes the exact boundaries described above: local-calendar prompt context, signed-in registration inside alpha.ts, ID-conditioned direct-alpha fallbacks, and conditional error-text construction.
I am not claiming an installation requirement was validated, a fallback was executed, a provider was available, or an outcome improved. The change is methodological: replace a product-strength narrative with a source-bounded inspection rule that tells the reader what to verify next.
How should an engineer evaluate a recovered result?
Use this checklist before calling a research-agent response evidence-ready:
- Pin the implementation. Record the repository commit, package declaration, source URL, coordinate, and read date. Treat
0.5.47and Node>=22.22.0as declarations until installation and runtime are separately tested. - Identify the path. Was the operation a direct alpha wrapper, an annotation tool, or the separate science-database dispatcher? Do not merge these routes because they share a topic.
- Record scope. Preserve whether the return is a source-labeled search list, arXiv metadata/abstract, an explicit no-answer note, or the original error plus recovery guidance.
- Inspect the artifact. Open the actual provenance file, extracted sections, citations, or code diff. A prompt asking for provenance is not the provenance artifact.
- Audit telemetry separately. Note whether an event is a tool error or a generation event, whether
errorTextwas applied, and which privacy questions remain unobserved. - Keep inference labeled. Recovery can improve inspectability at a tool boundary; it does not by itself establish reliability, citation accuracy, privacy, delivery, retention, or final-answer quality.
Key Takeaways
| Finding | Safe interpretation | Do not infer |
|---|---|---|
registerAlphaTools(pi) is unconditional, but account wrappers use signedIn inside alpha.ts | Registration and authorization are separate boundaries | Fresh per-call authorization or successful sign-in |
alpha_search can name an OpenAlex fallback | A source substitution can be disclosed at return time | Guaranteed successful or complete search results |
alpha_get_paper / alpha_ask_paper require an extractable ARXIV_ID for fallback | Recovery may be metadata/abstract-only or explicitly unanswered | Equivalent full text, sections, or a completed answer |
errorText trims, substitutes home paths, and tails over 4,000 UTF-16 code units | Conditional client-side error construction with up to 4,003 code units | Byte limits, general redaction, no-content, delivery, or retention guarantees |
| Date context, fallback labels, and workflow provenance prompts are separate surfaces | Each can be audited with its own source and artifact check | A proven serial pipeline or final-artifact provenance |
New Questions
- Which tests or runtime fixtures verify that each direct fallback returns the intended scope when alphaXiv fails?
- How does the science-database dispatcher differ in its completed-answer and full-text behavior under the same paper input?
- Which final provenance files are created for a recovered search, abstract-only get, or explicit no-answer ask, and can their contents be checked automatically?
- What transport, retention, and downstream-access controls apply to the conditional error fields after the client event is constructed?
- Does a future release add dedicated generation-content fields, or does the error-text boundary remain the only conditional text path?
References
Pinned package and release metadata (read 2026-10-15):
- Feynman
package.jsonat commitc8d84cd1939a018a930272f48d16f79da8ec249b— declared version and Node engine. - Feynman release notes at commit
c8d84cd1939a018a930272f48d16f79da8ec249b— release-note headings and stated changes. - Feynman README at commit
c8d84cd1939a018a930272f48d16f79da8ec249b— workflow, provenance, and telemetry statements. - v0.5.45 GitHub release API record, v0.5.46 record, and v0.5.47 record — publication timestamps.
Pinned implementation surfaces (read 2026-10-15):
current-date.tsat commitc8d84cd— local-calendar prompt context inbefore_agent_start.research-tools.tsat commitc8d84cd— unconditional direct-alpha registration caller.alpha.tsat commitc8d84cd— signed-in registration, fallback labels, ID-conditioned recovery, and original-error guidance.science-databases.tsat commitc8d84cd— distinct dispatcher surface.science-database-arxiv.tsat commitc8d84cdandscience-database-openalex.tsat commitc8d84cd— fallback source implementations.telemetry.tsat commitc8d84cd— event fields anderrorTexttransform.
Related methods (read 2026-10-15):
- Harness engineering for agents — controlled evidence design for model, task, tool, and environment comparisons.
- Engineering discipline for AI coding agents — declared handoffs versus enforced proof.
Editorial method: claims in this article point to primary documentation, pinned source code, runnable checks, or dated measurements, with AI-assisted research under the site's evidence-gated policy. How this site verifies claims and discloses AI assistance · Report a correction.
Working on something like this?
I take a small number of paid, scoped reviews: AI agent/RAG architecture diagnosis, Unity CI & build-automation audits, and multimodal QA design review. Each one ends in a written findings document.
Work with me