AI, Agents
Harness Engineering: What a Benchmark Score Actually Measures
A source-bound look at how model identity, prompts, tools, middleware, task sets, sandboxes, and scoring rules shape reported agent results.
Updated October 14, 2026. This article retains its original February 18, 2026 publication date; its research and analysis were rebuilt on the update date.
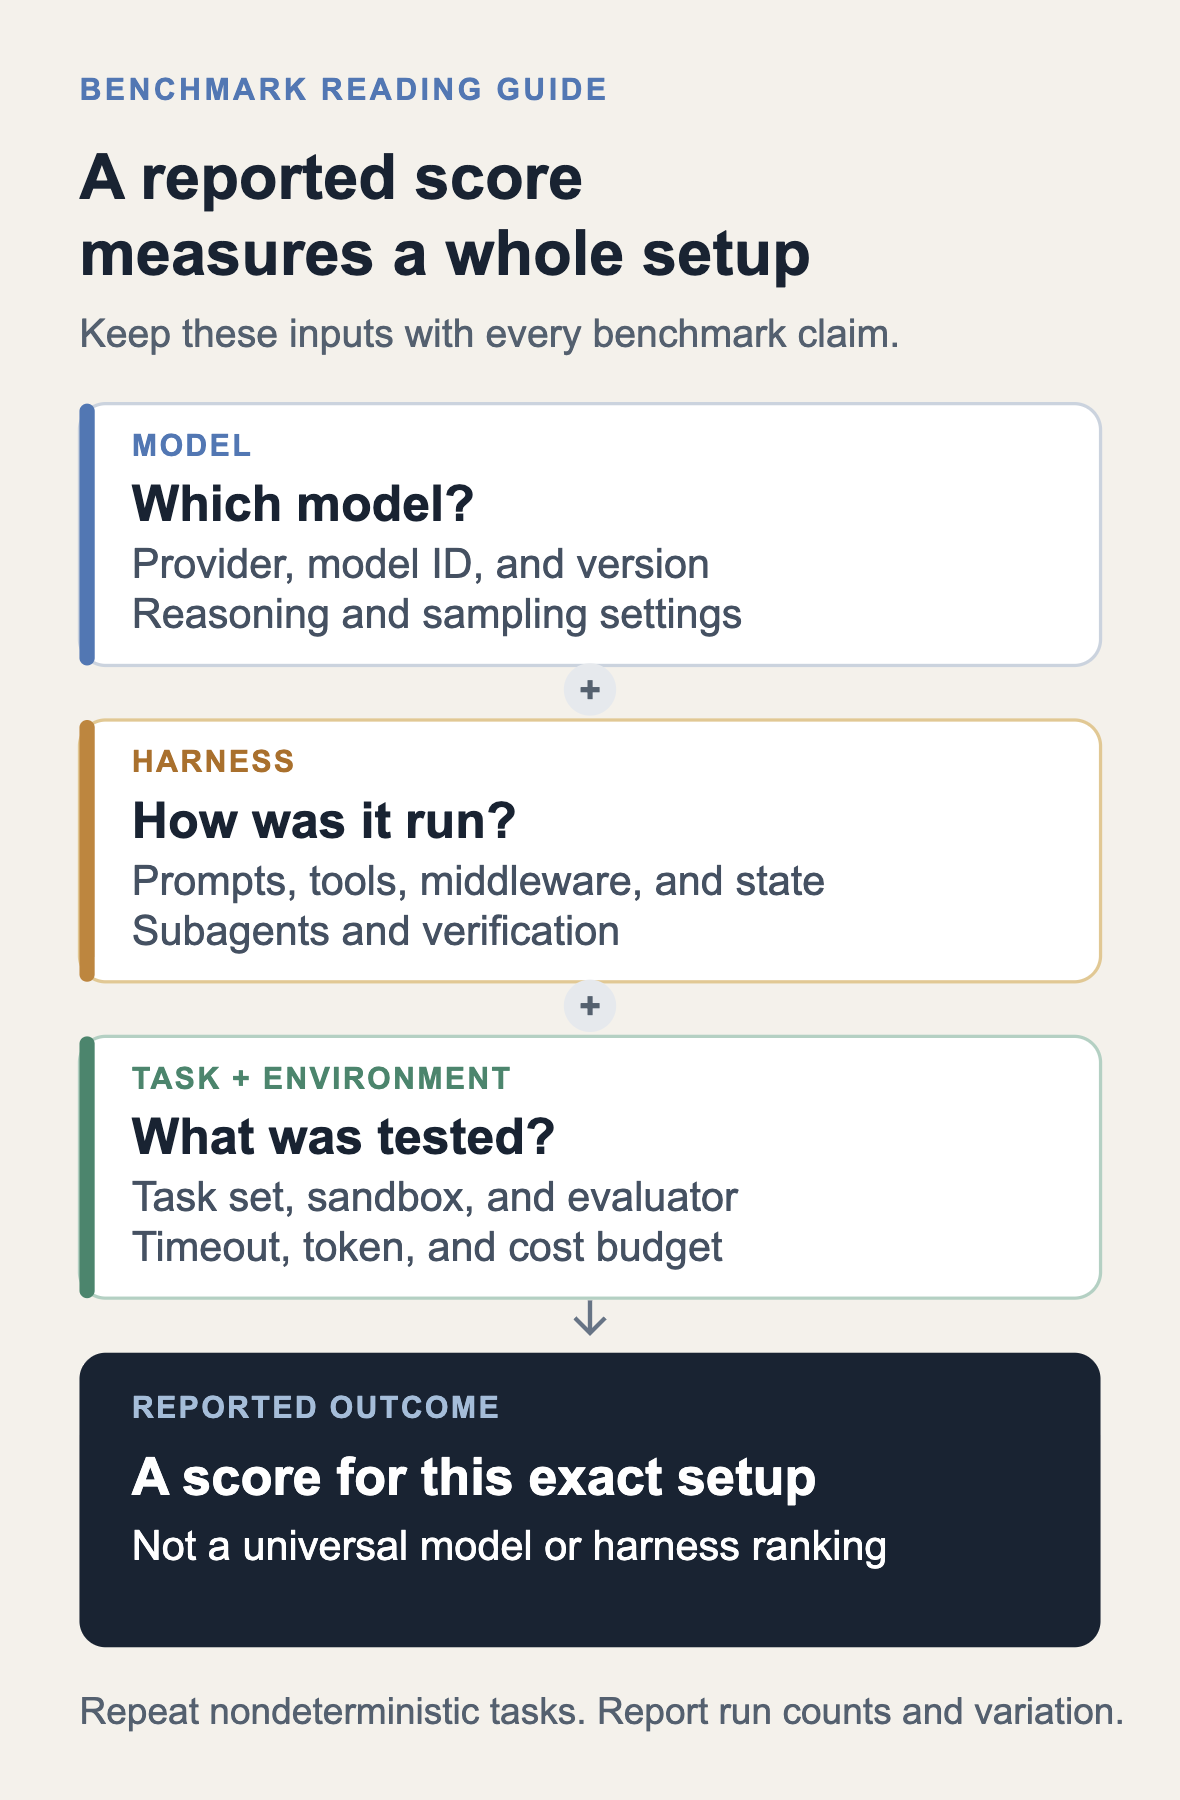
A benchmark score is not a property of a model in isolation. It is the outcome of a model running through a particular harness, against a particular task set, inside a particular environment with particular verification rules and budgets. Change one of those and the number may change. That does not make the result useless. It means the comparison has to say what was held fixed.
This is a narrower claim than saying that harness engineering beats model upgrades, or that a harness is the layer that makes every agent work. The public evidence supports something more actionable: in some published evaluations, changing the harness bundle moved results while the named model stayed fixed. Those results still belong to the exact experiment that produced them.
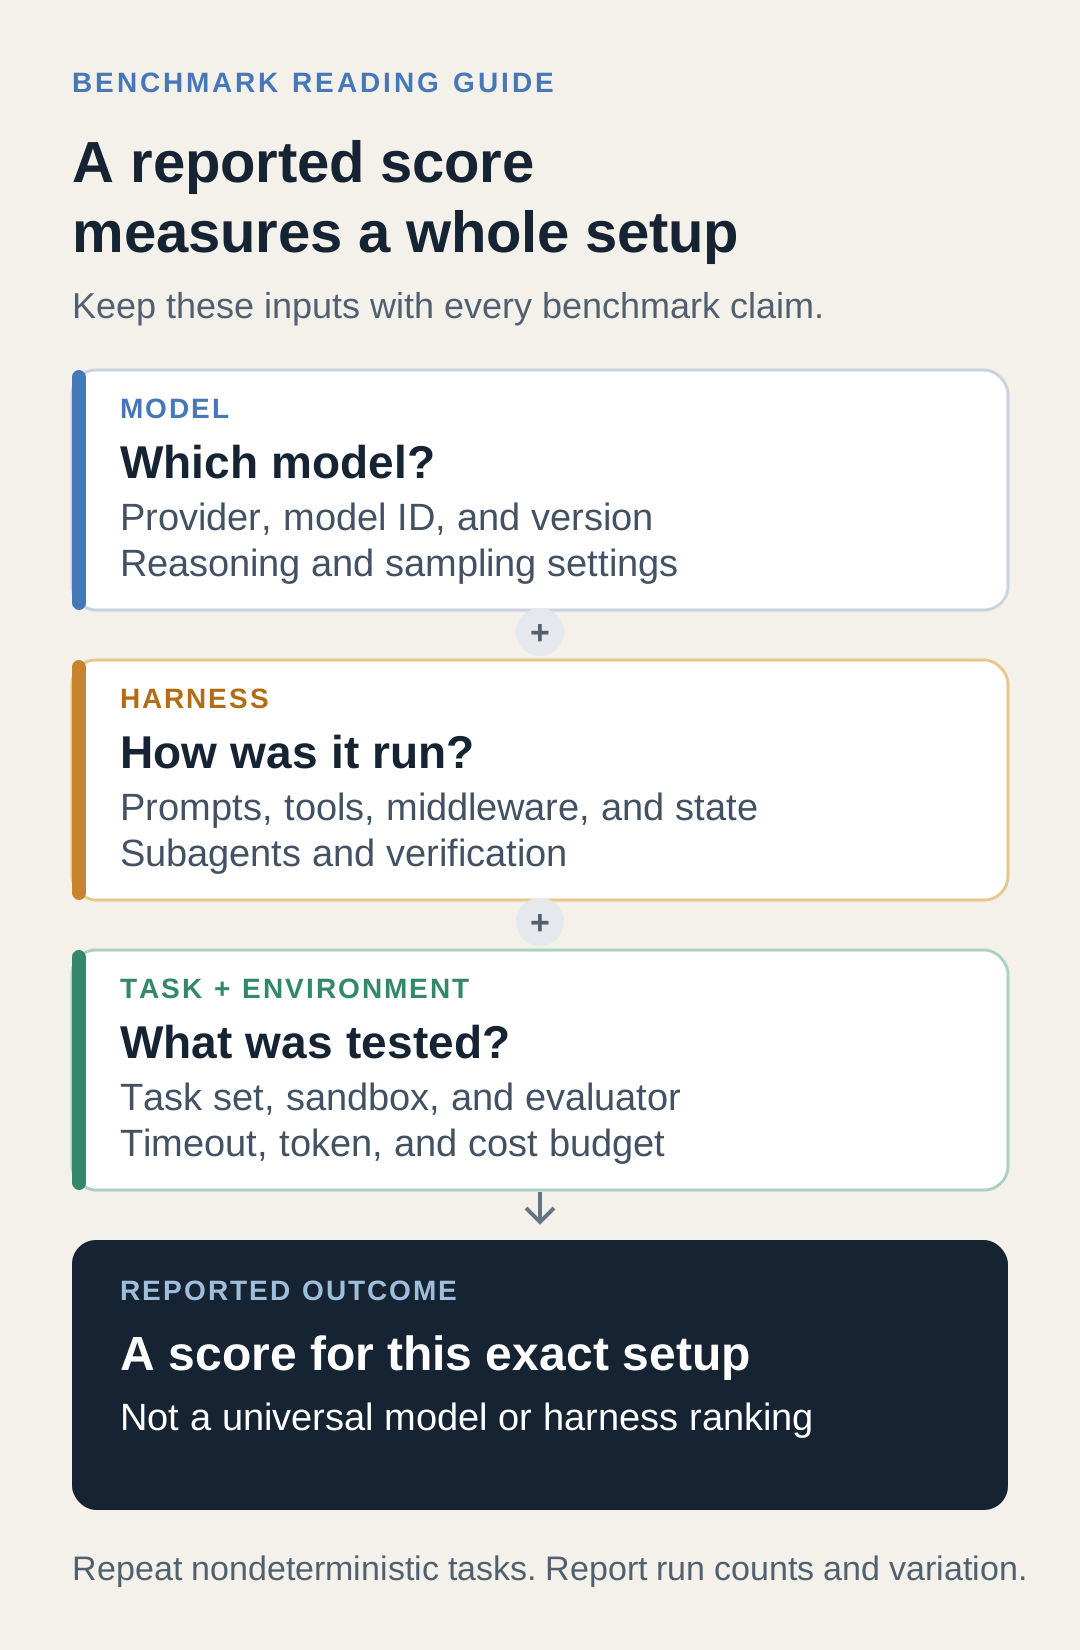
Editable SVG source is available separately.
Define the comparison before reading the result
A coding-agent evaluation has at least three moving parts.
- The model includes the provider, exact model identifier or version, and any model-side reasoning or sampling settings.
- The harness includes the system instructions, tools, middleware or hooks, subagent flow, memory, state handling, and verification loop.
- The task and environment include the dataset, sandbox, available files and tools, evaluator, timeout, and token or cost budget.
| Part of the setup | Record before comparing |
|---|---|
| Model | Provider, exact model or version, reasoning and sampling settings |
| Harness | Prompts, tools, middleware, state, subagents, verification loop |
| Task and environment | Task set, sandbox, evaluator, time and token budgets |
| Report | Score, cost, latency, run count, and variation |
The final score is evidence about that combination. It is not a clean estimate of the model’s isolated ability if the harness, task scope, or environment changes at the same time. A leaderboard rank adds another moving part: it depends on the submissions and results available when the ranking is observed.
A fixed model identifier can still produce a different score
LangChain reports a 52.8% baseline for GPT-5.2-Codex, 63.6% when using high reasoning only, 53.9% when using xhigh only, and 66.5% for an xhigh-high-xhigh reasoning sandwich on Terminal-Bench 2.0. It says it kept the model fixed while changing the harness, and describes the 13.7-point increase from baseline. Its own results show that reasoning-budget settings are part of the tested setup too.
Treat the 13.7-point delta as a vendor-reported sequence, not a transferable or harness-only effect size. The model identifier stayed fixed, but reasoning-budget settings changed; the result should not be attributed to prompts and middleware alone. An embedded leaderboard screenshot displays 66.5 ± 3.1, but the post does not define the ± statistic or give the number of trials behind the before-and-after values. It says trial results did not vary much across reasoning-budget splits, which is not a substitute for a stated trial count or uncertainty method.
The benchmark itself matters too. LangChain describes Terminal-Bench 2.0 as 89 tasks and says it used Harbor to orchestrate runs in sandboxes, verify outputs, and score them. A task suite, sandbox, and scoring script are part of what the result means, not background details that can be dropped from the headline.
Model-specific profiles change more than wording
A later LangChain profile experiment makes the setup dependence more explicit. On a curated, difficult subset of τ²-Bench, the company reports GPT-5.3-Codex moving from 33% with the base Deep Agents harness to 53% with a custom profile. It reports Claude Opus 4.7 moving from 43% to 53% on the same subset.
The profile changes were not identical. LangChain says its Codex changes included replacing the default file-edit tool with apply_patch, renaming the execution tool to shell_command, and adjusting prompt guidance. The Opus changes were mainly prompt-focused. Those are source-reported results for a selected subset, not a full τ²-Bench estimate or an independent replication. The post does not report a trial count or confidence interval for these numbers.
The current Deep Agents documentation describes a profile as an overlay on harness behavior, including prompt text, tool descriptions and inclusion, middleware, and subagent configuration. It distinguishes that from a provider profile, which sets model-construction options. A pinned source snapshot makes the distinction concrete: the OpenAI Codex profile registers specific model keys and adds a prompt suffix plus TodoListMiddleware, while the Opus 4.7 profile adds its own prompt suffix. These files show configuration, not measured performance by themselves.
That difference is useful when reading claims such as “same model, better harness.” Ask which profile changed, whether the model identifier stayed fixed, and which outcomes were measured. A profile name alone does not tell you whether its tools, middleware, or provider-side settings were held constant.
The task environment is part of the measurement
LangChain’s benchmark-methodology article now describes three different Deep Agents suites: Harbor-Index for end-to-end work, a 30-task τ³-bench subset for multi-turn conversation, and a 30-task ContextBench set for retrieval. The article says each Harbor task includes an environment, instruction, and evaluation script. It also recommends running each task multiple times because agent results are nondeterministic, and keeping a fast capability suite beside end-to-end benchmarks.
This is a better mental model than treating “agent benchmark” as one number. A retrieval score, a long coding task score, and a simulated customer-service outcome answer different questions. Even a fixed prompt and model can behave differently when the filesystem, available tools, scoring script, timeout, or task distribution changes.
For a practical comparison, make the control surface explicit before running it:
- Pin the model identifier and model-side settings.
- Freeze the task set, sandbox image, tool availability, evaluator, timeout, and budget.
- Change one harness factor at a time, or label the result as a bundle when several change together.
- Repeat nondeterministic tasks and report the number of runs and variation, not only the best score.
- Track cost, latency, intervention rate, and failure categories beside pass rate.
These are proposed evaluation steps, not experiments performed for this article. A compact two-model by two-harness comparison can also expose interaction: test each model with both harnesses on the same tasks and budgets. That design can reveal whether a profile helps one model more than another; it does not guarantee that the result generalizes beyond the tested tasks.
Production case reports answer a different question
OpenAI’s February 11, 2026 report describes one internal product built over five months with no manually written code, reaching about one million lines and roughly 1,500 pull requests. The company estimates the work took about one-tenth the time it would have taken to write manually. It describes a system of repository knowledge, tooling, tests, review loops, and operational feedback. That is a detailed case report about one team’s process. The estimate is OpenAI’s, not a controlled comparison of a harness against a model upgrade.
Anthropic’s March 2026 article describes a planner, generator, and evaluator for multi-hour application builds. Its author also reports changing the design after Opus 4.6 improved: sprint decomposition was removed, and the evaluator was retained when tasks sat beyond what the model could handle reliably alone. In one retro-game example, Anthropic reports that the solo run took 20 minutes and cost $9, while the full-harness run took six hours and cost $200. The planner expanded the same one-sentence request into a 16-feature specification across ten sprints, far beyond what the solo run attempted. The example shows a large cost and scope difference, not a clean estimate of the harness’s isolated effect.
Together, these reports suggest a useful engineering question: which component is load-bearing for this model and task today? They do not support a timeless ranking of harnesses or a claim that more agents, more middleware, or more verification is always better. The evaluation has to be repeated when the model, workload, or runtime changes.
What changed since February 2026
The original February note used benchmark swings and production stories to argue that harness quality mattered more than raw model strength. The sources published since then make the point more precise. LangChain’s per-model profile results show that prompt and tool configuration can move scores on a selected task subset. Its later benchmark-methodology post explains why repeated runs, environments, and evaluators belong in the measurement. Anthropic’s account shows that some scaffolding became less necessary after a model change, while other checks still helped on harder tasks.
The shift is from a slogan to a testable question. A useful report should name the model, harness revision, task distribution, environment, budget, run count, and evaluator. If one of those is missing, state the boundary instead of filling it with an assumption. If several variables changed, report a bundle result rather than assigning the entire delta to one component.
Related reading covers two different boundaries. Microsoft Agent Framework Harness defaults vary by language shows why a library’s defaults should be checked in the actual runtime. HarnessRouter’s execution contract separates a local cancellation result from proof that a remote worker stopped. Neither is a benchmark comparison, but both illustrate why an agent system’s observable behavior depends on its concrete runtime contract.
Key Takeaways
- A reported agent score belongs to a model, harness, task set, environment, and evaluator together.
- LangChain reports a fixed-model progression from 52.8% to 63.6% to 66.5%; its embedded leaderboard shows 66.5 ± 3.1, but the post does not define that statistic or state trial counts.
- Model-specific profiles can alter prompts, tools, and middleware; configuration evidence is not itself performance evidence.
- Production case reports can reveal useful architecture and tradeoffs, but they do not isolate a universal harness effect.
- Repeat the comparison on the tasks and budgets that matter, and report variation as well as the score.
New Questions
Which harness component remains load-bearing after a model upgrade, and what repeated, task-matched evidence would justify keeping it?
References
First-party evaluations and methodology
- LangChain: Improving Deep Agents with harness engineering - GPT-5.2-Codex and Terminal-Bench 2.0 results.
- LangChain: Tuning Deep Agents to Work Well with Different Models - profile results on a τ²-Bench subset.
- LangChain: How We Benchmark Deep Agents - benchmark suites, task structure, and repeated-run guidance.
- Deep Agents harness profiles documentation - current profile and provider-profile behavior, observed 2026-10-14.
Pinned implementation and case reports
- OpenAI Codex harness profile at pinned commit 2c42ddea9090e63a8ba745fb8eaf78144804d267.
- Anthropic Opus 4.7 harness profile at the same pinned commit.
- OpenAI: Harness engineering - internal product case report, published 2026-02-11.
- Anthropic: Harness design for long-running apps - reported multi-agent architecture and task-specific examples, published 2026-03-24.
Editorial method: claims in this article point to primary documentation, pinned source code, or dated reports, with AI-assisted research under the site’s evidence-gated policy. How this site verifies claims and discloses AI assistance · Report a correction.
Editorial method: claims in this article point to primary documentation, pinned source code, runnable checks, or dated measurements, with AI-assisted research under the site's evidence-gated policy. How this site verifies claims and discloses AI assistance · Report a correction.
Working on something like this?
I take a small number of paid, scoped reviews: AI agent/RAG architecture diagnosis, Unity CI & build-automation audits, and multimodal QA design review. Each one ends in a written findings document.
Work with me