AI, Agents
Engineering Discipline's handoff contradicts its gate
A commit-pinned Source Audit of Engineering Discipline’s worker–validator handoff, the inline-execution contradiction, and what its published benchmark can and cannot establish.
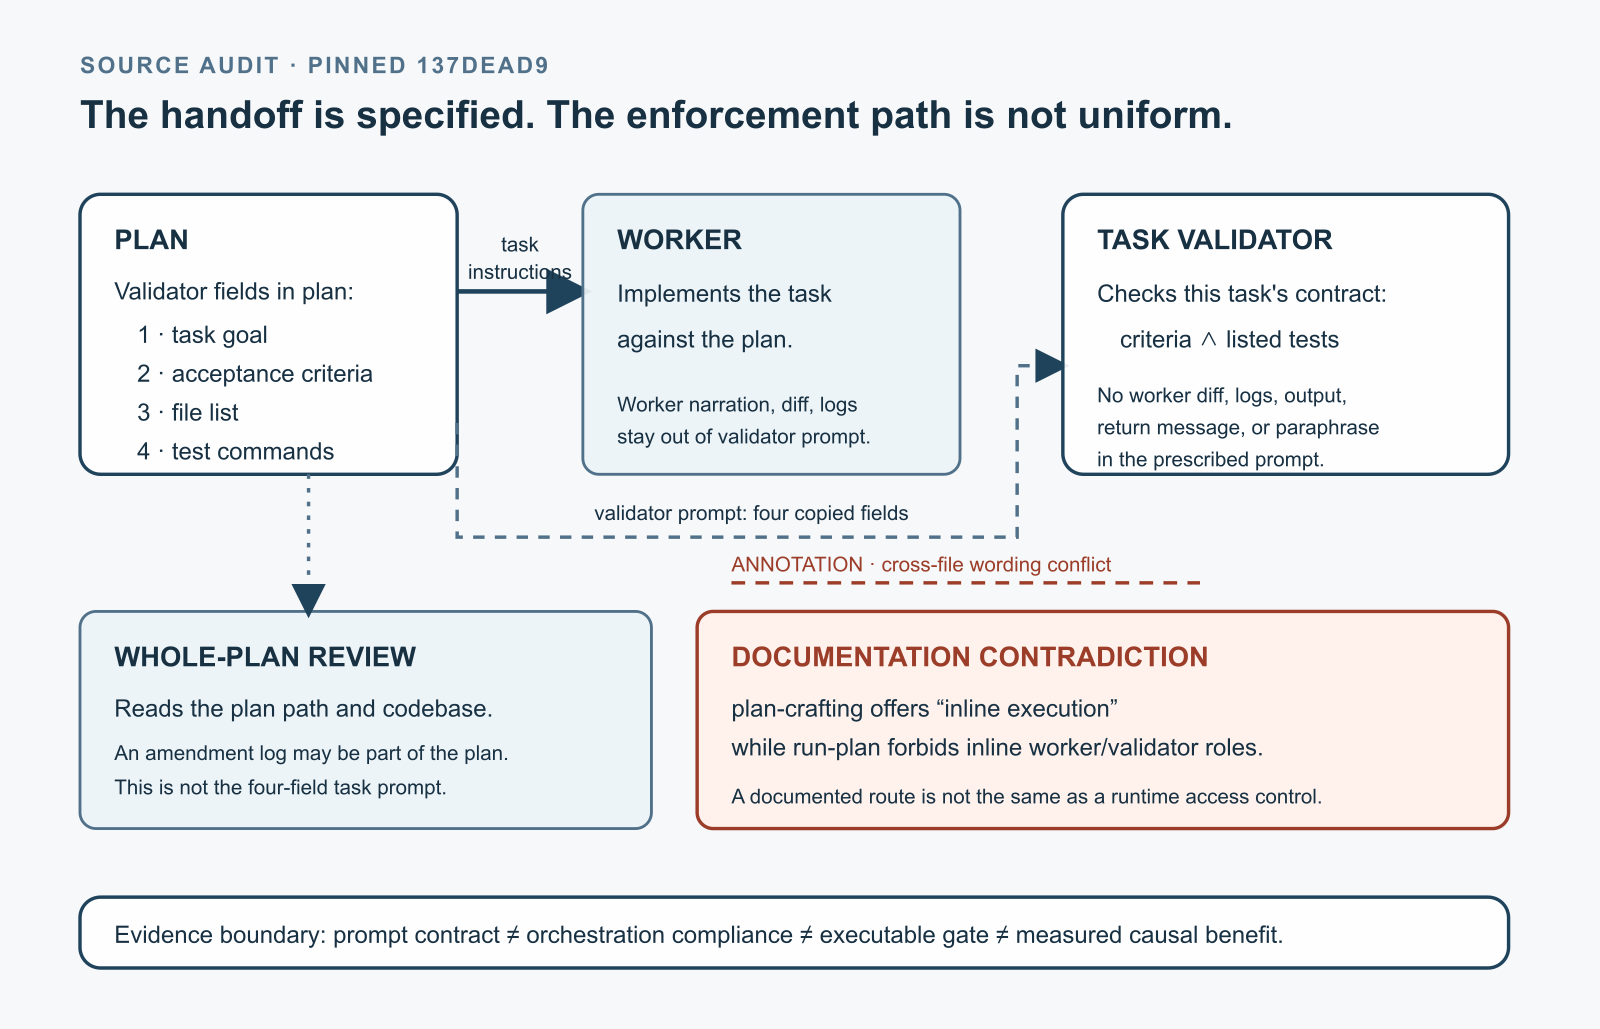
Does this harness enforce its validator boundary?
The useful question is not whether a coding-agent harness sounds disciplined. It is whether the boundaries in its contracts survive contact with the interfaces that are supposed to enforce them.
I audited tmdgusya/engineering-discipline at commit 137dead9137f39aa54b9ed87803a7f26324eedaf, the current default-branch revision returned by the official API during this audit. The commit metadata dates that revision 2026-07-03, and I read the pinned tree on 2026-10-15. The repository describes a workflow in which a worker implements a task and a separate validator checks it without receiving the worker’s narration. That is a precise and worthwhile design question.
[INFERENCE] The inspected repository does not itself establish a runtime information barrier. Its tree supplies Markdown contracts and helpers, but no worker–validator dispatcher or access-control implementation is identified in the pinned inventory. That is not proof that an external host cannot provide one. The narrower finding is that the source specifies a boundary without demonstrating its enforcement.
The source audit also found a cross-file contradiction: plan-crafting offers an inline-execution route while run-plan forbids inline worker and validator roles. The separately pinned benchmark record reports one author-run example, not a controlled comparison of models or validator arrangements.
Open the original SVG diagram.
The strongest boundary is a four-field handoff
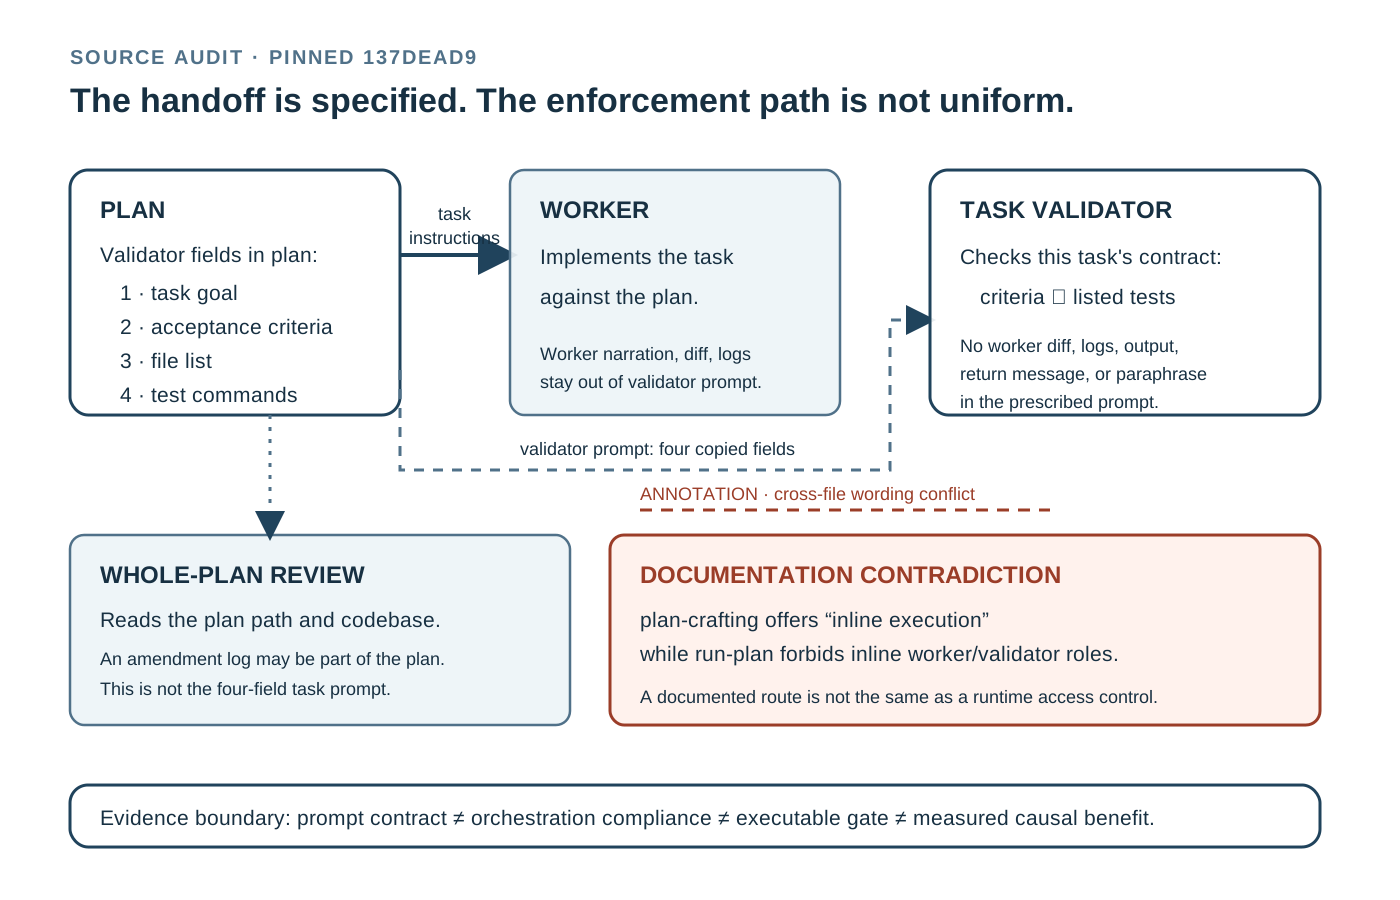
The most concrete part of the design is in skills/run-plan/SKILL.md at the pinned commit. Its hard gate says the worker and validator must be separate subagents and that the main agent must not perform either role inline. The worker receives task instructions from the plan; separately, the fixed validator prompt is built by copying exactly four fields:
- the task goal;
- the acceptance criteria;
- the affected file list; and
- the listed test commands.
The same template prohibits worker diff, logs, output, return message, implementation approach, and main-agent paraphrase from that validator prompt. That is more specific than the usual advice to “have another agent review the code.” It gives an operator something inspectable: compare the validator prompt with the plan and ask whether those four fields were copied as required. The SVG makes this distinction explicit: the plan-to-worker route is separate from the dashed four-field route that enters TASK VALIDATOR.
The contract also defines the scope of the verdict. The validator returns the logical AND of the acceptance criteria and listed tests for that task. It does not run the full test suite; cross-task regression is reserved for a later end-to-end gate. A task-level pass therefore cannot establish that the plan was complete, that the acceptance criteria captured the important behavior, or that integration is correct.
The source explains that the main agent may unconsciously frame the validator’s work around what the worker did. [INFERENCE] Withholding worker narration may reduce one channel of anchoring, but that is a hypothesis here—not a measured reduction in bias, a reliability result, or a guarantee that execution-derived information cannot reach the validator through another channel.
A plan reviewer is not the task validator
The repository has another boundary that is easy to collapse into the first one. skills/review-work/SKILL.md accepts a plan file path as its only input and reviews the plan against the codebase. If run-plan appends a Plan Amendment Log, the reviewer judges the amended plan because that log is part of the plan.
That is a whole-work review path, not the four-field task-validator prompt. The two roles ask different questions:
- Task validation: Did this task meet the copied goal, criteria, files, and commands?
- Whole-plan review: Does the plan, including any amendment log, match the resulting codebase?
This distinction matters because “information isolated” is not one universal property here. The task validator is instructed not to receive worker narration. The whole-plan reviewer receives a plan path and may read amendments created during execution. A reviewer can be independent of the worker’s prose while still judging a specification that changed during the run.
That is not automatically wrong. Mutable plans can be useful when reality invalidates an assumption. But the mutation should be visible, and the reader should not mistake the two review surfaces for an immutable, uniformly enforced isolation mechanism.
The planning handoff contradicts the execution gate
The cross-file problem is more direct. skills/plan-crafting/SKILL.md presents an execution handoff with an “Inline execution” option: execute tasks in the current session through run-plan, with checkpoints. The pinned run-plan contract says the main agent must not perform worker or validator roles inline and that each role must be dispatched as an independent subagent.
Both statements can be read charitably. “Inline execution” might mean that the current session orchestrates the run while still dispatching the roles. But the wording does not say that. A reader following the handoff literally can choose a route that the hard gate forbids. That is a documentation/interface contradiction, not proof that every host runs inline or that a particular benchmark violated the gate.
This is the boundary I would fix before debating model quality. A harness cannot be evaluated by its strongest paragraph alone; its routing surfaces must agree. The minimum repair is to make the handoff name the required worker-validator dispatch explicitly, then add a check that fails when the main agent is asked to implement or validate inline. A prompt saying “do not do X” is a convention unless the surrounding runtime makes the prohibited path unavailable or observable as a violation.
Recovery is specified, not exercised
skills/long-run/SKILL.md extends the same idea to multi-day work. It prescribes state updates before and after every milestone, resuming from the first unchecked task, and retaining attempt counters instead of resetting them after a crash. Parallel milestones are directed to isolated worktrees.
Those are useful recovery requirements. They are not a crash test. The audit did not install the plugin, dispatch a worker, interrupt a milestone, inspect a merge, or verify that state writes are atomic and idempotent. The file also contains a checkpoint-order ambiguity: one step says to mark a milestone completed and write its checkpoint after review, while a following step places integration verification before checkpoint writing. That is a static source finding. It does not establish that state was lost or that a real recovery replayed work.
The right adoption question is therefore operational: which state transition is the source of truth, and what command or fixture proves that an interrupted run resumes without silently redoing completed work? Until that scenario is exercised, “fail-safe recovery” is a prescribed behavior, not an observed property.
The published benchmark answers a narrower question
The source ecosystem contains a separately pinned realworld-benchmark report and a pinned transcript. The report’s commit is dated 2026-04-04. It attributes a single-shot run to a worker-validator execution path and publishes an author-reported result of 13 Hurl test files, 149 requests, 100% pass, and 7 minutes 32 seconds wall time. A separate displayed duration is 1213 ms. Those figures have different scopes, and this audit did not reproduce either result.
The transcript visibly records one displayed model, exploration agents, inline route-file writing, compilation, server startup, and a full Hurl test suite. It does not visibly record a separate implementation-validator dispatch or verdict in the published 546-line record. That absence is not proof that an unseen validator never ran, and it does not prove the benchmark used the July repository revision audited here.
What can this example establish? It shows that the author published a concrete run record and associated measurements. What can it not establish? [INFERENCE] It does not isolate a no-harness baseline, compare a worker-validator run with an inline run, compare models, establish client parity, or measure a causal benefit from information separation. The source-appropriate conclusion is not “the harness beats the model.” It is that the benchmark leaves the causal question open.
For a useful comparison, hold the task corpus, model, client, tool permissions, timeout, test suite, and scoring rules constant. Change one boundary at a time: inline implementation, separated task validator, and whole-plan review. Record failures and recoveries as well as passes. Without that design, a successful single run remains an example, not an ablation.
What is actually executable in the repository?
The complete pinned tree has no dedicated tests/ directory, but that does not mean it contains no executable material. It includes scripts/verify-theme.sh, a shell verification script for the Chalkboard theme migration, and skills/systematic-debugging/find-polluter.sh, a diagnostic helper. The theme script checks textual HTML/CSS conditions, theme tokens, font usage, and reduced-motion text. It does not check worker-validator independence, checkpoint ordering, or model performance. The audit read it but did not run it.
The pinned Pages workflow is also configuration, not a correctness gate. deploy.yml checks out the repository, configures Pages, uploads the repository as an artifact, and deploys it. It has no run step invoking the theme script and no validator-isolation check. External services or maintainer processes may exist outside that file; this audit did not inspect them.
That inventory suggests a simple vocabulary for harness reviews:
- Executable gate: a command or runtime check that can fail on a concrete condition.
- Orchestration contract: a documented sequence that a client is expected to follow.
- Prompt convention: a rule about what an agent should or should not receive.
The four-field validator template is a strong prompt convention. The worker/validator dispatch requirement is an orchestration contract. The theme script is an executable gate, but for another concern. Calling all three “enforcement” hides the engineering work still required to connect them.
What changed since the April 2026 note?
The original April note carried a borrowed “I built engineering-discipline” framing and treated harness-over-model superiority, savings, and reliability as if they were established outcomes. This rebuild removes that autobiography and those unsupported claims. It replaces them with a source-pinned cross-file audit of the four-field handoff, whole-plan review boundary, inline-execution contradiction, checkpoint ordering, and benchmark/transcript scope.
The separately pinned benchmark record was committed on 2026-04-04, two days after the preserved original article date. The engineering-discipline revision inspected here was the current default-branch commit dated 2026-07-03, and the source audit was read on 2026-10-15. These are separate dated records: the benchmark report does not pin which engineering-discipline revision its session loaded, so this chronology does not imply that the April benchmark used the July revision. Nothing in this rewrite demonstrates a historical runtime change, a reliability improvement, a cost reduction, or a model-superiority result.
The practical update is a change in what a reader can responsibly decide. The source supports inspecting prompt boundaries and contradictory handoffs; it does not support adopting a guarantee until dispatch, access, recovery, and controlled comparison are exercised.
Key Takeaways
| Finding | What it supports | What remains unproven |
|---|---|---|
run-plan specifies four copied validator fields and excludes worker narration from that prompt. | A concrete prompt contract that can be inspected against a plan. | That another channel cannot expose execution artifacts, or that the contract improves outcomes. |
| The repository inventory exposes contracts and helpers, not a supplied worker–validator access-control dispatcher. | [INFERENCE] Treat runtime enforcement as an external integration question. | Host-level compliance, client parity, and actual dispatch. |
plan-crafting offers inline execution while run-plan forbids inline worker and validator roles. | A documentation/interface contradiction worth repairing. | That a particular host or benchmark actually violated the gate. |
| The 2026-04-04 benchmark reports one author-run result with separate timing scopes. | A record to reproduce and compare. | Causal benefit, cross-model superiority, savings, reliability, or validator-separation effect. |
New Questions
- Which component makes inline worker and validator roles impossible, or at least records a violation?
- Can worker narration, diffs, logs, or return messages reach the validator through the client or filesystem despite the prompt template?
- What is the immutable or amended specification when a plan changes during execution?
- Which fixture proves crash recovery without silently redoing completed work, and are state writes atomic and idempotent?
- Can the benchmark be rerun with the harness revision, model, client, permissions, corpus, timeout, tests, and scoring rules pinned separately?
- Which comparison isolates the effect of inline execution, task validation, and whole-plan review one boundary at a time?
For the measurement design behind those questions, read the existing harness engineering agents audit, which identifies the variables a controlled comparison must hold constant. The adjacent agent-team coordination note is useful as a contrast about task ownership and locks, but its restored performance language is not evidence for this audit. The model context is separately discussed in GLM-4.7 coding-agent model; nothing in this source review establishes cross-model superiority.
References
Repository and pinned contracts (Read 2026-10-15)
engineering-disciplinecommit 137dead9 — current default-branch revision returned during the audit, dated 2026-07-03.run-plan/SKILL.md— worker-validator gate and four-field prompt.plan-crafting/SKILL.md— binary criteria and inline handoff.review-work/SKILL.md— whole-plan review boundary.long-run/SKILL.md— prescribed checkpoints and recovery.verify-theme.sh,find-polluter.sh, anddeploy.yml— executable/configuration surfaces inspected but not executed.
Benchmark record (Read 2026-10-15; repository commit dated 2026-04-04)
realworld-benchmarkREADME — author-published example and reported measurements, not reproduced here.realworld-benchmarktranscript — published execution record, not independently authenticated telemetry.
Related reading (Read 2026-10-15)
- Harness engineering agents — controlled-comparison variables for agent harness measurements.
- Agent-team coordination note — adjacent task-ownership and lock questions, not evidence for this audit.
- GLM-4.7 coding-agent model — model context without a cross-model claim here.
The original post date remains 2026-04-02 10:00:00 +0900. This rebuild is a later Source Audit of the pinned materials, not a claim of first-hand product use, benchmark reproduction, reliability improvement, cost reduction, traffic, revenue, or AdSense outcome.
Editorial method: claims in this article point to primary documentation, pinned source code, runnable checks, or dated measurements, with AI-assisted research under the site's evidence-gated policy. How this site verifies claims and discloses AI assistance · Report a correction.
Working on something like this?
I take a small number of paid, scoped reviews: AI agent/RAG architecture diagnosis, Unity CI & build-automation audits, and multimodal QA design review. Each one ends in a written findings document.
Work with me