AI
Qwen3.6-Plus Preserves Only Reasoning the Client Replays
Qwen3.6-Plus separates thinking from history replay. A pinned Qwen Code audit shows why preserve_thinking, idle cleanup and a 1M context window are different contracts.
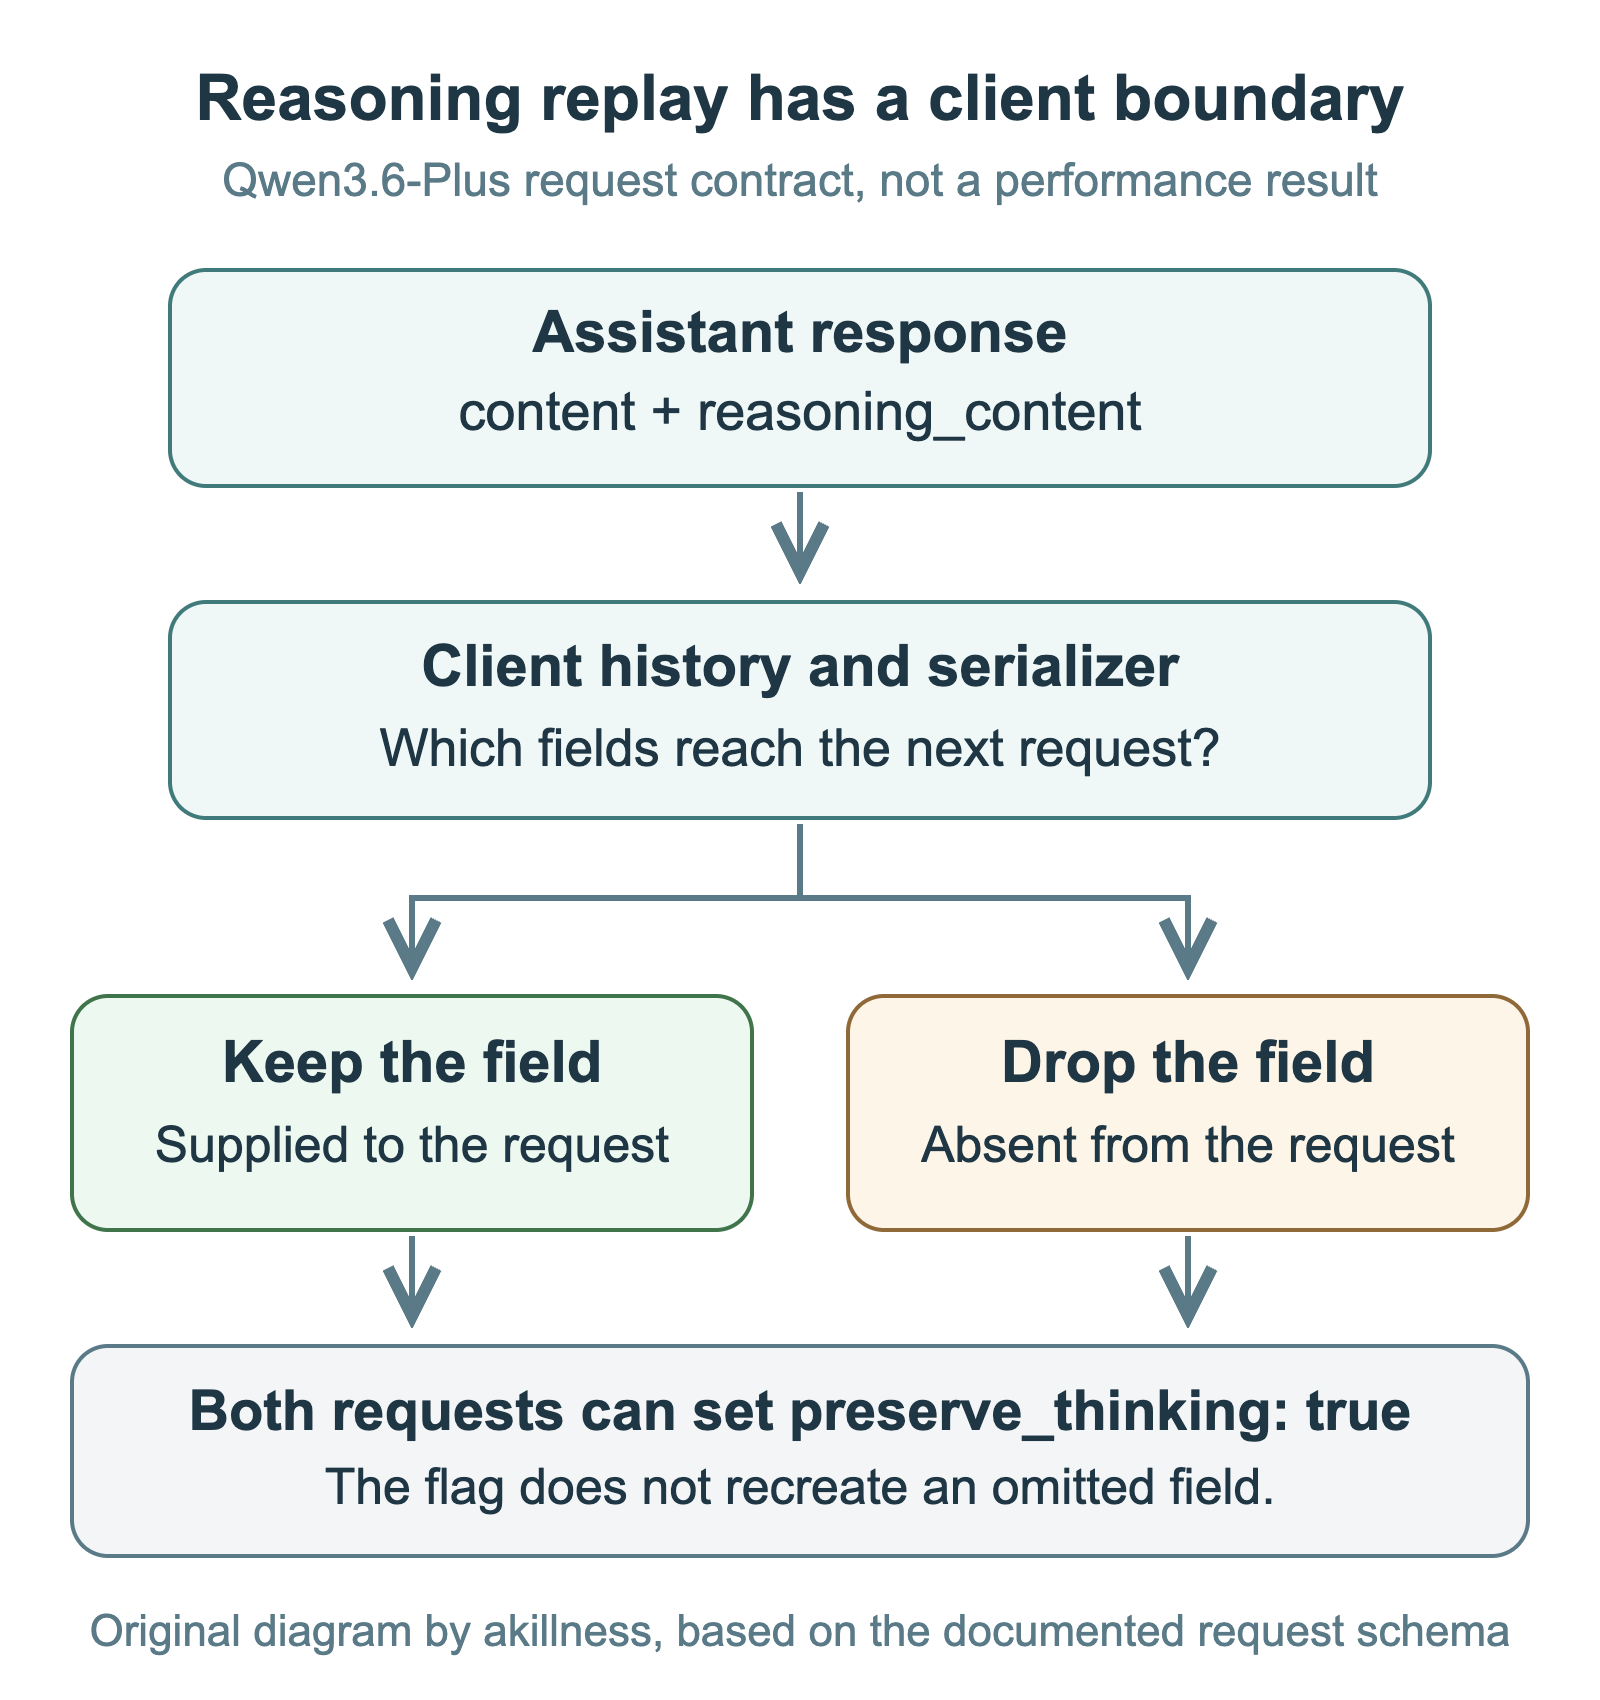
Why can a thinking-enabled agent still lose its reasoning history?
The first version of this April note treated a large context window and a reasoning-preservation flag as signs of a more capable agent. Those are useful features, but they leave a practical question unanswered: what does the client actually send on the next turn?
Qwen3.6-Plus exposes separate controls for generating reasoning and reading previous reasoning. Neither is a substitute for a history store. If an application reconstructs every assistant message as only role and content, it drops the separate reasoning_content field before the model receives the request. Setting preserve_thinking: true afterward cannot supply a field that is absent.
That is the implementation boundary worth checking before blaming a model for forgetting a plan. It is also why the old example was insufficient: it issued one completion and printed the answer. There was no second request demonstrating what survived a round trip.
This rebuild combines current API documentation with one historical Qwen Code revision. I inspected the sources and ran a synthetic request-construction check, not a Qwen inference call. The findings below do not establish coding accuracy, cache savings, latency or production reliability.
Thinking generation and thinking replay have different defaults
Alibaba Cloud’s Deep Thinking guide, read on October 14, classifies Qwen3.6-Plus as a hybrid-thinking model with thinking enabled by default. Qwen’s launch announcement separately says preserve_thinking is disabled by default. An agent can therefore generate reasoning without opting into reading reasoning from earlier assistant messages.
The API guide describes the replay contract explicitly: in a multi-turn conversation, preserve_thinking controls whether the model reads historical assistant reasoning_content. The client must provide that field on the historical assistant messages. “Preserve” here should not be interpreted as an automatic server-side session database.
| Boundary | What the inspected material establishes | What it does not establish |
|---|---|---|
| Thinking generation | Qwen3.6-Plus can run with thinking enabled; the guide documents its default | That prior reasoning is present in a later request |
| Thinking replay | Historical assistant reasoning_content is supplied by the client and read under preserve_thinking | That a serializer may omit the field without consequence |
| Context capacity | The model page lists a 1,000,000-token context window | That every earlier fact will be retrieved accurately |
| Function calling | The application receives a tool instruction, executes it and returns the result | That the model itself owns shell, account or deployment permissions |
The last row matters just as much as the history field. Function Calling documentation supports the Qwen3.6-Plus series, but the application’s execution step remains a separate responsibility. A model returning a tool call is not permission to run it, and a long reasoning trace is not evidence that the resulting action succeeded.
Editable SVG source of the original diagram.
The 1M window is not a one-million-token input allowance
The launch describes a default 1M context window. The current model-information page, updated September 28 and read October 14, gives a more useful planning boundary: 1,000,000 tokens of context, 991,808 maximum input tokens, and 983,616 maximum input tokens in thinking mode. These are documented limits, not measurements from a local workload.
For a coding agent, that distinction changes how to prepare a request. Repository files are only part of the input. Instructions, user turns, previous assistant messages, tool definitions and tool results also occupy the request. Replayed reasoning is another field the application must account for. Do not equate a marketing context-window number with a file-ingestion budget.
There is a second, independent uncertainty: capacity is not retrieval quality. A window specification does not show that the agent can reliably find the relevant build error among unrelated logs, or preserve a project constraint through repeated compaction. Those require workload-specific evaluation.
I removed the earlier article’s launch-score comparison rather than use it as evidence of those properties. Vendor benchmark results can motivate a test, but they cannot answer whether this particular history serializer, tool loop and repository task work correctly together. This article reports no replacement model score.
What changed since the April 2026 launch note?
There are now three timelines to keep separate: the hosted model, open-model releases and the coding client.
The hosted model has a snapshot identifier. At the October 14 read, the model page describes qwen3.6-plus as functionally equivalent to qwen3.6-plus-2026-04-02. For a reproduction that must hold the April model snapshot constant, use the snapshot identifier rather than assume a moving alias will always mean the same thing. The documentation’s read date remains part of that statement. This does not establish availability in every region or account.
The open-model repository moved beyond Qwen3.6. The former Qwen3.6 repository URL resolves to Qwen3.8 at the read time. Its README at commit 2ea10dc7 lists Qwen3.6-35B-A3B on April 16, Qwen3.6-27B on April 22, and Qwen3.8 open-model releases in August. These are distinct model releases, not proof that an open checkpoint is the hosted Qwen3.6-Plus service. Do not transfer a hosted result or parameter assumption merely because names share a prefix.
Qwen Code made retention an explicit client policy. PR 2897, merged into commit 3c23952e on April 8, replaced unconditional thought stripping at the user-query/cron entry point with idle-triggered cleanup. In the inspected client branch, a gap exceeding the configured threshold sets a sticky cleanup latch. The settings schema defaults that threshold to five minutes.
After the latch is set, stripThoughtsFromHistoryKeepRecent(1) removes older thought parts. The selection method counts model entries containing thought parts, not every model entry. It retains the most recent thought-containing entry at that cleanup step. Later entries without thoughts do not displace it from the selection.
That is not “all reasoning is kept forever.” The latch stays on until chat reset; other history-management paths, including compaction, remain outside this narrow branch finding. The code comments explain a prompt-cache-prefix motivation, but I did not measure cache hits or reasoning coherence. This is an April 8 implementation audit, not a claim about the October client’s current retention policy.
A request-construction check comes before a model benchmark
A small local fixture makes the serializer boundary visible without spending an API call. On October 14, I ran node replay-fixture.mjs against a synthetic assistant object. Its marker string was test data, not model reasoning. The fixture constructed two JSON requests with the same preserve_thinking: true flag: one dropped reasoning_content, and the other copied it.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
import assert from 'node:assert/strict';

const prior = {
  role: 'assistant',
  content: 'A synthetic answer.',
  reasoning_content: 'FIXTURE_ONLY_NOT_MODEL_REASONING'
};
const omitted = { role: prior.role, content: prior.content };
const replayed = { ...prior };
const request = (assistant) => ({
  model: 'qwen3.6-plus-2026-04-02',
  preserve_thinking: true,
  messages: [assistant, { role: 'user', content: 'Continue.' }]
});

assert.equal(request(omitted).preserve_thinking, true);
assert.equal(Object.hasOwn(request(omitted).messages[0],
  'reasoning_content'), false);
assert.equal(request(replayed).messages[0].reasoning_content,
  prior.reasoning_content);
All three assertions passed in the recorded fixture. The serialized request without the field still had the flag enabled. That demonstrates an object-construction mistake is possible; it does not show that either request was accepted by a provider, or that replay improves answers. The excerpt above is the same check in abbreviated form; it is not a full API integration example.
For a real client, make this a round-trip test: ingest an actual response, persist it, reload it and inspect the resulting request in a controlled test environment. Verify the fields your provider documents, including tool-call identifiers when tools are involved. Do not put unrestricted reasoning or secrets in routine production logs just to debug retention.
Then evaluate the model on the task that matters. For an illustrative game-build assistant, the acceptance criterion might be preserving a user-approved build target, linking a proposed fix to a real compiler error, and refusing deployment without approval. Those are suggested test cases, not workloads executed for this article.
The next useful comparison is HarnessRouter’s execution contract, which separates local cancellation state from remote execution receipts. Microsoft Agent Framework’s language-specific defaults offers a related check on how much behavior a factory call actually composes. Neither a request flag nor an agent wrapper should stand in for inspecting the boundary it promises to control.
Key Takeaways
enable_thinkingandpreserve_thinkingare separate controls. Cross-turn replay requires the client to supply historical assistantreasoning_content.- A 1M context window is a documented capacity limit, not proof of retrieval accuracy or an equal-sized input allowance.
- The April 8 Qwen Code retention branch uses idle cleanup and keeps the latest thought-containing entry at that step. It is not permanent history, and it is not an audit of the current client.
- The local fixture checked request construction only. Model quality, provider acceptance and production performance remain unmeasured here.
New Questions
- Which fields survive the application’s persistence and history-compaction paths before a second request?
- What retention policy does the exact client revision deployed in your stack apply after an idle gap or chat reset?
- Does reasoning replay improve your task’s completion rate enough to justify its token and data-retention cost?
References
Hosted-model announcement and API contracts
Read on 2026-10-14. These are vendor documentation and capability statements, not independent runtime measurements.
- Qwen3.6-Plus launch announcement: default context-window claim and
preserve_thinkingdefault. - Alibaba Cloud Qwen3.6-Plus model information: page updated 2026-09-28, context/input limits and
qwen3.6-plus-2026-04-02snapshot relationship. - Deep Thinking guide: thinking defaults and historical assistant
reasoning_contentreplay. - Function Calling guide: supported model series and the application-owned execution loop.
Source-pinned client and model-series survey
Read on 2026-10-14. Code findings are static and limited to the cited revision.
- Qwen Code PR 2897, merged 2026-04-08; client, history-selection method, and settings schema at
3c23952ef7bdae2dac1fe404b95e88c529bc82da. - Qwen3.8 README at
2ea10dc725823bf7c3e21ce8557cbe15245132ae: dated open-model releases and the current repository’s scope.
Editorial method: claims in this article point to primary documentation, pinned source code, runnable checks, or dated measurements, with AI-assisted research under the site's evidence-gated policy. How this site verifies claims and discloses AI assistance · Report a correction.
Working on something like this?
I take a small number of paid, scoped reviews: AI agent/RAG architecture diagnosis, Unity CI & build-automation audits, and multimodal QA design review. Each one ends in a written findings document.
Work with me