AI
Claw Dev sets its session token after starting the proxy
Claw Dev starts or reuses its proxy before assigning the client token. A pinned audit traces authentication, buffered streams, and retired GitHub Models.
What does Claw Dev preserve when the backend changes?
The April note about Claw Dev got one important thing right: a bundled terminal client can be pointed at more than one model backend. It also made the familiar leap from a provider menu to a portability story.
A pinned Source Audit changes the size of that conclusion: I re-read the launcher, compatibility proxy, provider catalog, package metadata, and current GitHub service documentation at the dates listed in References.
At commit 16e7958fe761ab2e12c9775a0b5921b8a2bedb28, Claw Dev has one Anthropic configuration branch and seven compatibility-provider branches around the same bundled client. That is a real design boundary. It is not evidence that eight backends behave interchangeably, or that the workflow-preservation benefit has been measured.
The more useful finding is lower-level: the launcher starts or accepts the proxy before it assigns the fresh client session token, while the proxy reads its expected token during module initialization. Around that ordering, the project also reconstructs streaming, estimates token usage locally, compacts requests with provider-dependent heuristics, and can return a model label that is not an upstream execution receipt. The interface looks familiar because the boundary is deliberately shaped like Anthropic’s API. The contracts underneath it remain different.
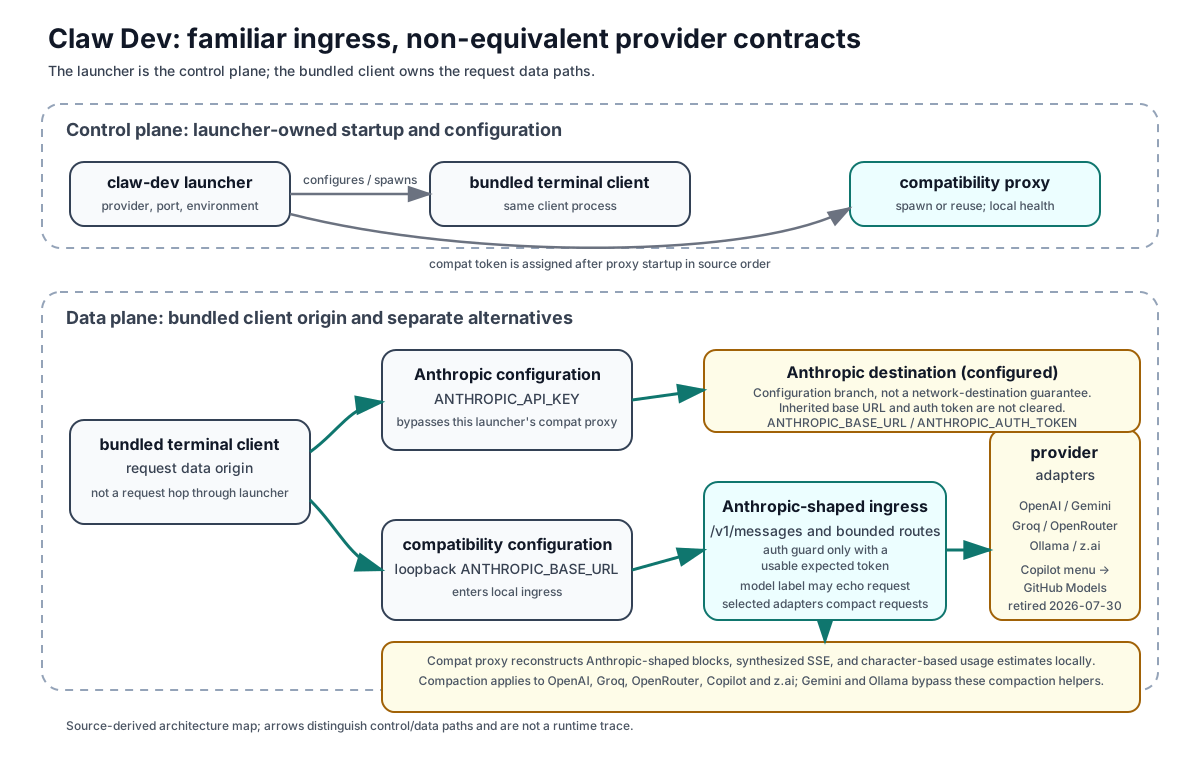
Open the original SVG diagram.
What the old note already got right—and what it could not show
The restored article already distinguishes direct Anthropic mode from proxy-backed modes and argues for a stable terminal workflow. That is not a new discovery in this rebuild. The repository README says the same thing in broad terms, and the old note explains the direct/proxy split under “What Claw Dev actually is” and “How the architecture works.”
What the old note did not provide was pinned control-flow evidence for the boundaries that matter when an agent session becomes a long sequence of tool-rich requests. It did not trace when the local session token exists relative to the proxy process, or separate local health from upstream readiness. It treated an Anthropic-shaped interface as a broad interoperability signal without showing the lossy and reconstructed parts of that interface.
That distinction matters for adoption. A familiar route name can be useful compatibility engineering without being a complete Anthropic API implementation. A model picker can make switching convenient without proving that a provider accepts the selected identifier. A healthy loopback process can be ready to answer /health while its upstream account, model, or endpoint remains untested.
The repository tip returned by the inspected fork was still the April 1 commit, whose message is Fix Copilot tool schema compatibility. The dated change that is material to this rebuild is elsewhere: GitHub officially retired GitHub Models, including its inference API, on July 30, 2026. The branch labelled Copilot in this source targets that GitHub Models service, not a GitHub Copilot service API. The menu label therefore cannot be carried forward as current Copilot integration.
The finding is in startup order, not menu size
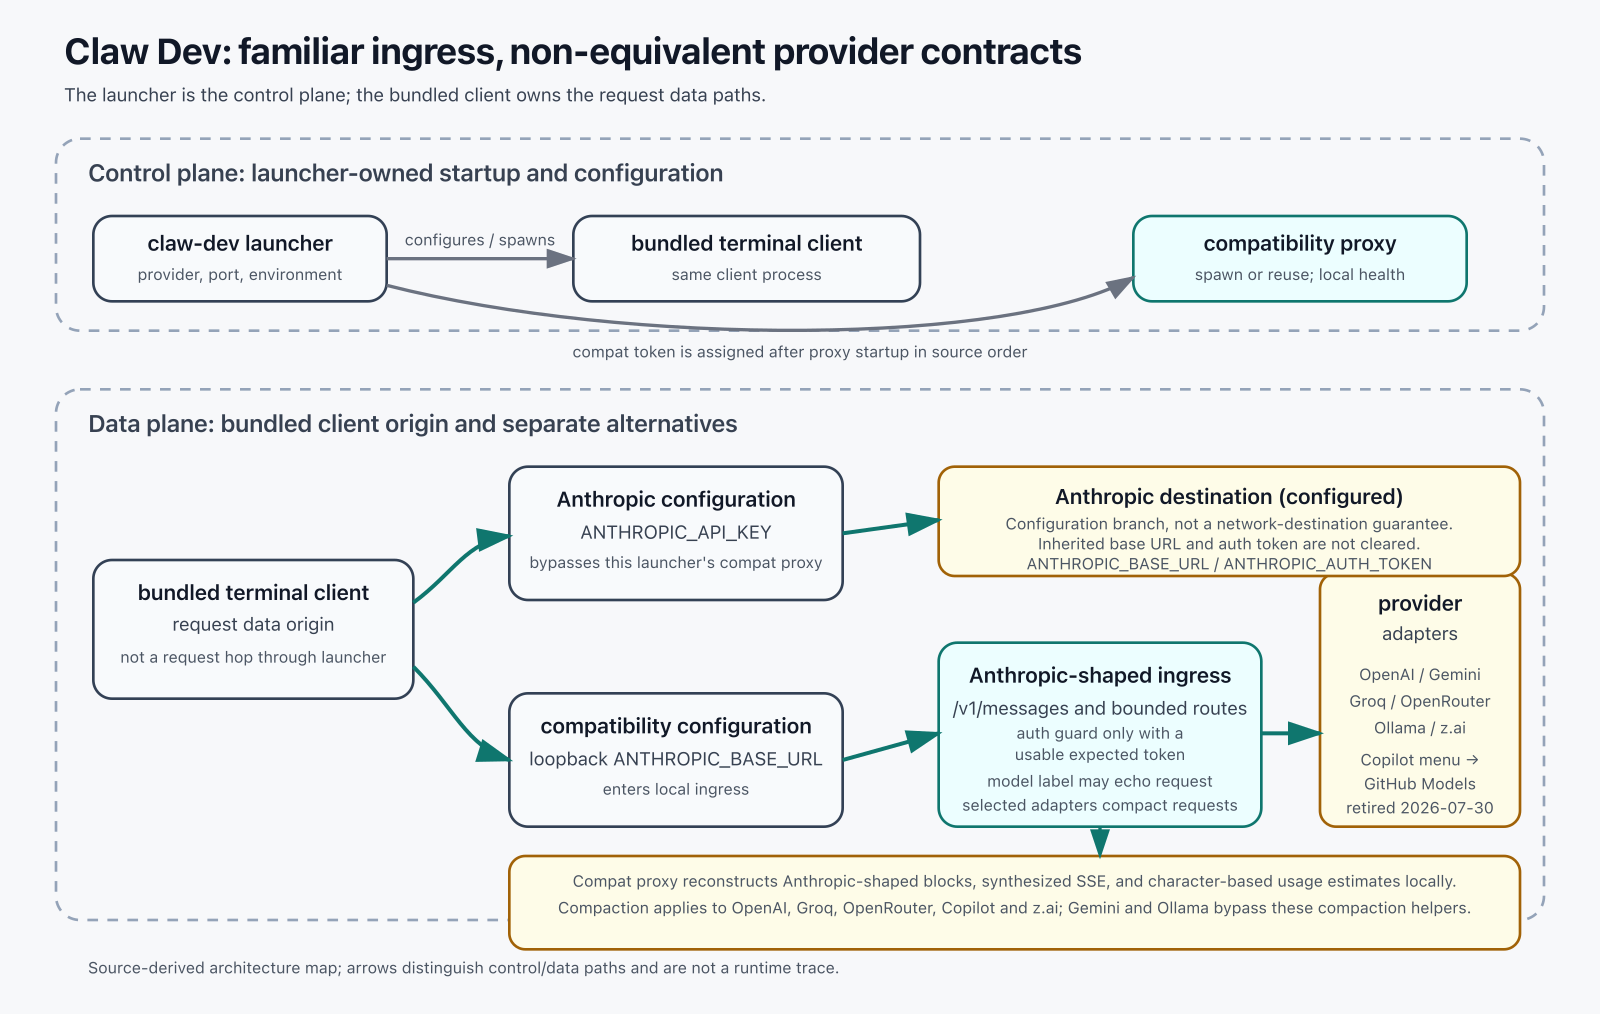
The launcher has two high-level paths. In Anthropic mode, configureAnthropic prepares ANTHROPIC_API_KEY and launches the bundled client directly. In every other menu branch—OpenAI, Gemini, Groq, OpenRouter, Copilot, z.ai, and Ollama—the launcher configures a provider, calls ensureCompatProxy, points the client at a loopback ANTHROPIC_BASE_URL, assigns ANTHROPIC_AUTH_TOKEN, removes ANTHROPIC_API_KEY, primes model choices, and launches the same bundled client. The Anthropic branch does not clear inherited ANTHROPIC_BASE_URL or ANTHROPIC_AUTH_TOKEN, so this is a configuration distinction rather than an unconditional network-destination guarantee.
The exact sequence is the important part. In main() the source performs:
1
2
3
4
await ensureCompatProxy(provider, env);
env.ANTHROPIC_BASE_URL = `http://127.0.0.1:${env.ANTHROPIC_COMPAT_PORT}`;
env.ANTHROPIC_AUTH_TOKEN = `claw-dev-proxy-${randomUUID()}`;
delete env.ANTHROPIC_API_KEY;
ensureCompatProxy passes its environment to the spawned proxy:compat process before returning. The proxy module then reads process.env.ANTHROPIC_AUTH_TOKEN into LOCAL_PROXY_AUTH_TOKEN while it initializes. The newly generated token is assigned in the parent launcher after that startup path.
[INFERENCE] A newly spawned proxy reads its startup token state, not the UUID assigned later for the client: without a usable expected token its guard returns immediately; with a different expected token, the client’s later token can be rejected. An accepted existing proxy retains its own initialized token state. No process, authentication failure, exploitability, or affected-user count was demonstrated for this audit.
The launcher does perform a health check, but the check is narrower than its name might suggest. isHealthyProxy() requests the local /health URL and checks that the response contains the configured provider and model strings. The proxy’s health response is built from PROVIDER and ACTIVE_MODEL; it does not call the upstream service. The launcher retries this local identity check up to 50 times with a 250 ms delay between attempts. That is process/startup coordination, not upstream readiness, account authorization, or model availability.
Ollama makes the same boundary visible in a different way. Its adapter defaults to http://127.0.0.1:11434, but OLLAMA_BASE_URL is configurable and can point at a remote server. The launcher prints a reminder to make sure Ollama is running and that the model is pulled; it does not verify either condition before starting the bundled client. “Local-only” and “zero cloud dependency” are therefore not unconditional properties of the implementation.
The proxy implements a bounded local surface
The compatibility proxy is not a drop-in implementation of every Anthropic endpoint. Its request handler explicitly covers:
GET /healthandGET /GET /v1/modelsGET /v1/models/:idPOST /v1/messages/count_tokensPOST /v1/messages
GET /health and GET / return before local authentication. For other requests, an absent configured local token bypasses the guard; when a token is configured, either a matching Bearer token or a matching x-api-key is sufficient. If neither matches, the handler returns HTTP 401 authentication_error. After that check succeeds, unsupported routes return HTTP 404 not_found_error.
There is a separate startup boundary for provider credentials. assertProviderConfiguration() runs before createServer(). Missing cloud credentials cause a CompatProxyError carrying statusCode: 400 and errorType: "authentication_error" before the HTTP server exists. That is exception metadata, not an observed startup HTTP response. The launcher may prompt for a credential or fail before the proxy module is spawned.
This is why “Anthropic-compatible” should be read as a local contract with a bounded surface, not as a guarantee of complete request-field or response-field semantics. A downstream client can see familiar paths and still encounter different authentication timing, unsupported routes, or locally reconstructed fields.
Familiar request shapes are translated, compacted, and rebuilt
The provider menu hides several request paths. OpenAI API-key mode constructs a Chat Completions request. OpenAI OAuth mode uses the ChatGPT Codex Responses endpoint and parses its SSE response. Gemini calls GoogleGenAI.models.generateContent with Gemini contents and function declarations. Groq, OpenRouter, Copilot, and z.ai use OpenAI-style chat-completions helpers with provider-specific URLs or headers. Ollama calls a configurable server’s /api/chat endpoint. These are branches behind one ingress, not one upstream protocol.
The shared OpenAI-compatible helper also compacts requests before sending them. Its local budgets are provider-dependent: 6,000 for Copilot, 12,000 for OpenAI, 18,000 for OpenRouter, and 20,000 for other providers. When a serialized request is too large, the code can slice message history and reduce the tool list. Copilot can keep only the latest four messages and replace tool parameters with an open object shape in minimal mode. The implementation’s commit history even records a specific Copilot schema-normalization fix that recursively handles object properties, array items, and anyOf, oneOf, and allOf variants.
Those thresholds are local heuristics, not provider context limits or account quotas. The source supports the narrower statement that the proxy may change what it sends. It does not support a claim about how much quality, latency, or reliability that change causes on a real task. The practical check is straightforward: if tool-heavy history matters, inspect the transformed request or run an authorized task against the selected provider. This audit did neither.
The stream boundary is similarly easy to misread. The /v1/messages handler awaits handleMessages(body) first. If stream is true, sendMessageStream then emits an Anthropic-shaped SSE sequence from the completed local message. Text is sent as a text_delta containing the assembled block text, and tool input is sent as a serialized input_json_delta. OpenAI OAuth mode likewise awaits the provider response text before parsing it. The source therefore shows synthesized client-facing SSE, not a measured time-to-first-token path or transparent provider streaming.
Usage fields are local estimates too. estimateInputTokens serializes messages, adds the normalized system prompt, divides character length by four, and clamps to at least one. estimateOutputTokens applies the same style of estimate to returned content. Top-level tool definitions are not included in the input estimator. The endpoint named count_tokens calls this helper. These values are not provider billing records, tokenizer measurements, or reliable context-budget guarantees.
A model label is not an execution receipt
The model picker combines an active environment model, comma-separated custom models, and static defaults. The helper does not query provider availability. Request resolution then checks catalog membership, attempts Claude-style slot mapping for opus, haiku, sonnet, or claude- names, permits custom IDs for several providers, and otherwise falls back to ACTIVE_MODEL. Copilot’s unknown non-slot IDs fall back to its active model; it is inaccurate both to say that every custom ID passes through unchanged and to say that Copilot rejects every arbitrary ID.
There is another subtle boundary in handleMessages:
1
2
const providerModel = resolveRequestModel(body);
const responseModel = body.model?.trim() || providerModel;
Provider functions receive providerModel, but the returned Anthropic-shaped message uses responseModel. That means the local response can echo the requested model name after slot mapping or fallback. [INFERENCE] A caller cannot use that response field alone as proof of which upstream model was selected. No misrouted live response was observed.
The adoption rule is simple: treat a picker entry and response label as inputs and annotations, not as an upstream execution receipt. Confirm the effective provider-side model through a provider-owned trace or an authorized test that records the request path. Neither was available to this audit.
What changed since April: GitHub Models retired
The implementation’s runCopilot branch sends a bearer token to https://models.github.ai/inference/chat/completions with the GitHub API version header. The pinned README describes that credential as a GitHub Models-compatible bearer token. That is what the code shows; it is not a GitHub Copilot subscription integration.
GitHub’s official changelog states that GitHub Models was retired on July 30, 2026, including the playground, catalog, inference API, and BYOK for existing customers. GitHub’s current documentation separately says GitHub Models was unrelated to GitHub Copilot services. This article therefore labels the branch precisely: Copilot menu label → retired GitHub Models inference service. It does not claim a current HTTP status from the hard-coded endpoint, and it does not imply that a Copilot subscription restores the path.
This is the clearest what-changed-since-April correction. The source fork still exposes the menu and adapter, but the named upstream service has a dated retirement notice. A provider list copied from the old note is stale even before a developer asks whether tool calls work.
An adoption checklist that tests the real boundaries
For an engineer evaluating one provider, the source audit suggests checks rather than promises:
- Trace startup order. Confirm which process receives
ANTHROPIC_AUTH_TOKEN, when the proxy snapshots it, and whether the client token matches the proxy’s expected value. The source ordering is documented; this lane did not execute it. - Separate local health from upstream readiness. A matching provider/model string on
/healthproves local identity only. Test credentials, model availability, and the actual upstream request separately. - Capture the effective model. Compare the request identifier after catalog and slot resolution with the provider-side trace. Do not rely on the local response
modelfield. - Measure transformed history and tools. If the session is large, inspect whether compaction removed messages or tool schemas before judging agent behavior.
- Measure stream semantics independently. A client-facing SSE sequence can be reconstructed after a completed provider call. Record first-token and completion timing if streaming matters.
- Keep accounting separate. Compare local estimates with provider-owned usage data before using them for budgets or billing.
- Check current service status. For the menu branch named Copilot, start with the official GitHub retirement notice; do not assume a subscription or token type provides a replacement.
These are proposed acceptance checks, not completed experiments. No provider inference request, authentication attempt, model availability probe, tool-execution loop, build, install, or automated test was run for this rebuild. Latency, cost, quota, rate-limit behavior, model quality, workflow-switching effort, and reliability remain unmeasured.
What the source establishes—and what it leaves unmeasured
The pinned implementation at commit 16e7958fe761ab2e12c9775a0b5921b8a2bedb28 supports the bounded claims below. [INFERENCE] marks a cross-file inference; unmeasured items remain test questions.
| Surface inspected | What the pinned source establishes | What remains unmeasured |
|---|---|---|
| Startup ordering and local health (E3, E5, E6) | The launcher awaits ensureCompatProxy, then assigns the loopback URL and fresh client token; local /health reports configured provider/model identity without an upstream call. [INFERENCE] A newly spawned proxy can read earlier expected-token state, while a reused proxy retains initialized state. | No process startup, authentication failure, exploitability, or upstream-readiness result was demonstrated. |
| Bounded routing and authentication (E4, E7, E8) | /health and / precede auth; absent configured token bypasses the guard; either matching Bearer or x-api-key suffices; neither match returns 401 authentication_error; unsupported routes return 404 not_found_error only after that check. Missing provider credentials fail before the server exists. | No live request-response behavior or complete Anthropic API semantics were exercised. |
| Provider-dependent compaction (E22) | The shared OpenAI-compatible helpers use local budgets of 6,000 for Copilot, 12,000 for OpenAI, 18,000 for OpenRouter, and 20,000 for other covered adapters; OpenAI, Groq, OpenRouter, Copilot and z.ai may trim requests, while Gemini and Ollama bypass these helpers. | These are not provider limits or quotas; task quality, latency, and reliability effects remain unmeasured. |
| Stream reconstruction (E23) | /v1/messages awaits the completed local result before emitting Anthropic-shaped SSE; the OpenAI OAuth path likewise awaits response text before parsing it. | No time-to-first-token, latency, or transparent incremental-streaming measurement was made. |
| Local usage estimates (E24) | Input estimates serialize messages and normalized system text, divide character length by four, round up, and clamp to one; top-level tools are omitted. | The values are not provider billing records, tokenizer measurements, or reliable context-budget guarantees. |
What this means for the terminal workflow
Claw Dev’s useful abstraction is narrower and more honest than “one agent, eight interchangeable backends.” It is a launcher around a bundled client plus a bounded translation layer. That can still be valuable if the engineering problem is reducing configuration churn while keeping the client surface familiar. [INFERENCE] Whether it actually reduces a team’s workflow-switching effort depends on the provider, request shape, credential state, and the compaction/streaming semantics above; the source does not demonstrate that outcome.
The bundled client metadata identifies @anthropic-ai/claude-code version 2.1.87, with a package README license pointer. The entire embedded CLI, its integrity, current upstream parity, permission behavior, telemetry, and redistribution authorization were not audited here. The repository declares Node.js 22 or newer and exposes proxy:compat and start scripts, but metadata is not a build or runtime result.
The original article’s workflow-stability thesis is therefore a useful question, not a conclusion. The source-backed conclusion is more specific: when a terminal client speaks through a familiar Anthropic-shaped boundary, inspect the initialization order, local health semantics, request transformations, model resolution, output reconstruction, usage estimates, and current provider status before treating the interface as portable.
For the next model-focused reading, see the GLM-4.7 scorecard audit, which asks why model comparisons also need task-specific evaluation protocols rather than labels or reported scores alone. For a related control-plane audit, read the CodeBurn guard hard-cap audit.
Key Takeaways
- The launcher starts or accepts the compatibility proxy before assigning the fresh client token; the source establishes ordering, not a demonstrated runtime failure.
- The bundled client has separate configuration alternatives: Anthropic mode bypasses this launcher’s compatibility proxy, while compatibility mode enters local ingress and provider adapters. The Anthropic branch still inherits any pre-existing
ANTHROPIC_BASE_URLorANTHROPIC_AUTH_TOKENvalues. - The proxy’s familiar surface is bounded and reconstructive: conditional local authentication, provider-dependent compaction, synthesized streaming, and character-based usage estimates are local behaviors rather than provider receipts.
- The menu label
Copilotpoints to GitHub Models inference in the inspected code, and GitHub retired that service on July 30, 2026. No current Copilot integration is established here.
New Questions
- In a newly spawned process, what startup environment should provide a usable expected token, and how should a reused proxy’s initialized token be coordinated with a later client token?
- Which provider-owned trace can confirm the effective model after catalog lookup, slot mapping, or fallback instead of relying on the local response label?
- How much tool history and schema survives each provider’s compaction path on a real task, and what does that change for agent behavior? This remains an unmeasured test question.
References
Pinned implementation and metadata (read 2026-10-15)
- Queried fork-tip API (read 2026-10-15).
- Claw Dev repository at commit
16e7958fe761ab2e12c9775a0b5921b8a2bedb28(read 2026-10-15). - Pinned README (read 2026-10-15).
- Pinned launcher (read 2026-10-15).
- Pinned compatibility proxy (read 2026-10-15).
- Pinned provider catalog (read 2026-10-15).
- Pinned root package metadata (read 2026-10-15).
- Pinned embedded client package metadata (read 2026-10-15).
Current official service status (read 2026-10-15)
- GitHub Changelog: GitHub Models is now retired (read 2026-10-15).
- GitHub Models documentation (read 2026-10-15).
Editorial method: claims in this article point to primary documentation, pinned source code, runnable checks, or dated measurements, with AI-assisted research under the site's evidence-gated policy. How this site verifies claims and discloses AI assistance · Report a correction.
Working on something like this?
I take a small number of paid, scoped reviews: AI agent/RAG architecture diagnosis, Unity CI & build-automation audits, and multimodal QA design review. Each one ends in a written findings document.
Work with me