AI
AutoBE Release Diff: 133 of 134 Compiler Files Match
Source-pinned audit of AutoBE releases, write-before-complete guards, and realization-test cleanup boundaries—not a reliability benchmark.
What changed in this AutoBE Source Audit?
The archived post asked readers to choose between two broad ideas: AutoBE’s verification discipline and Claude Code’s flexibility. That framing is memorable, but it quietly asks a source comparison to answer a measurement question. A package release, a validator branch, and a test harness can show how a system is built. They do not, on their own, show which system produces more reliable backends.
I revisited the question with a narrower rule: keep only what can be tied to a current primary artifact, a pinned source coordinate, or a deterministic comparison. The result is less dramatic and more useful. AutoBE’s current artifacts expose meaningful ordering and execution boundaries. The release comparison also reveals a surprisingly small byte-level delta between compiler 0.30.5 and 0.31.1. Neither observation is a benchmark, a pass rate, or a winner declaration.
That distinction matters whenever an agent framework’s architecture is presented as evidence of production outcomes.
What the current release artifacts actually establish
The npm registry identifies @autobe/compiler 0.31.1 as the current release examined here. Its package metadata points to the wrtnlabs/autobe repository and declares AGPL-3.0. The registry time map places 0.30.5 at 2026-03-31T15:37:21.278Z and 0.31.1 at 2026-04-10T07:52:25.891Z (UTC), so the comparison crosses the archived post’s April 7 date.
Those are release-identity facts. They are not evidence that the implementation became more reliable between the two versions. To separate release identity from implementation change, I compared the exact registry tarballs with a deterministic standard-library tarfile/hashlib pass:
| Package | Members | Matching hashes | Changed members |
|---|---|---|---|
@autobe/compiler@0.30.5 | 134 | 133 | package/package.json |
@autobe/compiler@0.31.1 | 134 | 133 | package/package.json |
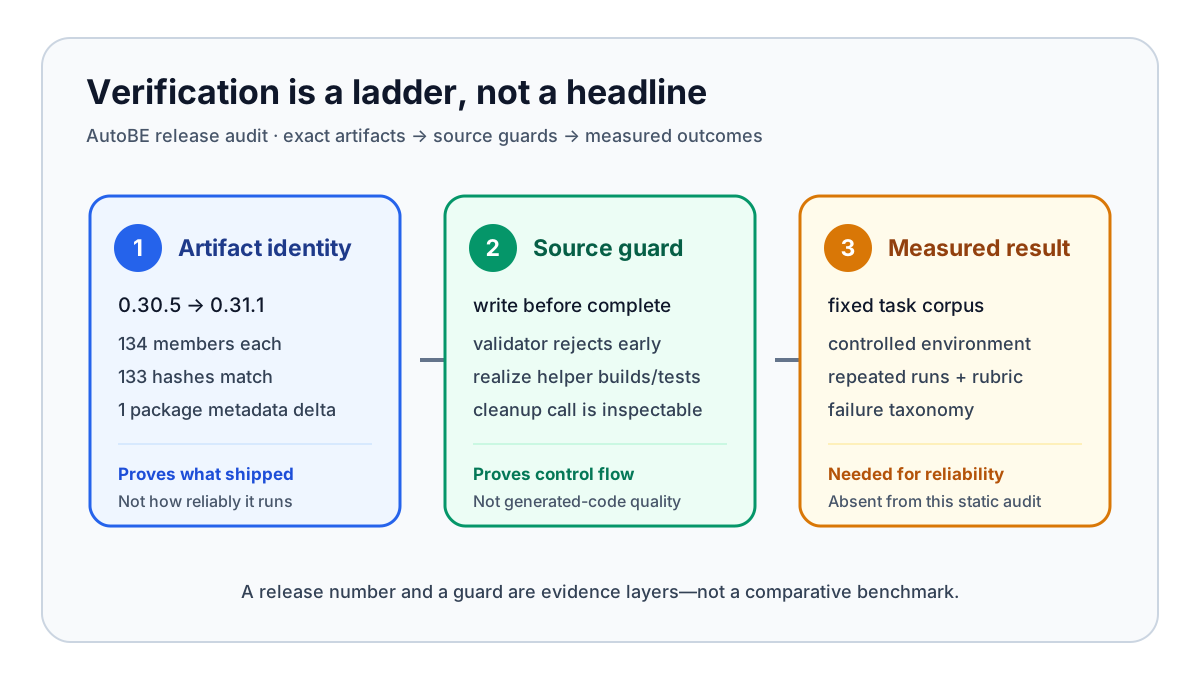
The tarball SHA-256 values were ce8fd853fba435ac1a4c9236af2df6fa39e6ef96a97cd82db4a4d4c4a7393364 for 0.30.5 and 6e9fd6b728a618007c3990f75a6c93512118d731381782b52e900b5d019e8a3c for 0.31.1. Inside the only changed member, the package version and five dependency ranges changed. The source files in the compared package members were byte-identical. The five declared dependency ranges changed as follows: embed-eslint ^2.0.1 → ^3.1.0; embed-typescript ^2.0.1 → ^3.1.0; @autobe/filesystem ^0.30.5 → ^0.31.1; @autobe/utils ^0.30.5 → ^0.31.1; and @autobe/interface ^0.30.5 → ^0.31.1. This is a declared-package comparison only: no resolved or transitive dependency comparison was performed.
This is a useful release-engineering result precisely because it is modest: the published compiler artifact changed in metadata and dependency declarations, not in the 133 other retained members. It does not prove that a package install resolves the same graph, that transitive dependencies behave the same way, or that either release is reliable. Declared licensing also does not grant permission to reuse the archived DEV cover image; that image remains excluded from this draft.
Where does AutoBE put a verification boundary?
The current agent source contains a concrete ordering guard in validatePreliminary.js. When a caller asks the complete-case path to finish before submitting a write, the validator returns this description:
No write has been submitted yet. Please call
process({ request: { type: "write", ... } })with your content first, then call “complete” once you are satisfied with the result.
That is stronger than a README promise because it is an observable branch in a version-pinned implementation. It proves that this validator path enforces a write-before-complete order. It does not prove that the submitted content is correct, that generated code compiles, or that a downstream service is production-ready.
The distinction can be made explicit:
- Ordering proof: a complete request without a prior write is rejected.
- Compilation proof: generated code may be sent through a build or test command.
- Behavior proof: a passing test would establish behavior only for its fixture and environment.
- Production reliability: requires a defined workload, independent repetitions, failure taxonomy, and comparable controls.
The source record does not justify a comparative production-reliability conclusion: neither an ordering guard nor compiler/test architecture, on its own, establishes which system is more reliable than Claude Code.
What does the realization helper do—and what does its code leave unresolved?
The compiler’s testRealizeProject helper makes its intended lifecycle readable. It constructs a temporary-workspace name, saves supplied files, runs pnpm install, pnpm run build:prisma, and pnpm run build:test, then connects a tgrid WorkerConnector to bin/test/servant.js and invokes the test service. A finally block calls fs.promises.rm with recursive and force options.
That sequence explains how an integration-style check could be wired. It is not evidence that a generated project passed. The implementation also illustrates why code-level inspection must remain exact. mkdtemp(cwd) returns a suffixed temporary path, but the returned value is discarded; subsequent setup, worker connection, and cleanup continue to use the unsuffixed cwd. The worker connection is also performed before the try/finally that closes the worker. Those are source-visible lifecycle boundaries, not a tested claim that cleanup is exhaustive or that every failure mode is handled safely.
This is the original finding I would preserve from the audit: AutoBE exposes a write-before-complete guard and a realization-test lifecycle, while its current compiler release diff is almost entirely package metadata. Together, those facts support a static audit of where verification is placed. They do not support a comparative reliability score.
A practical evidence ladder for agent-framework reviews
When reviewing an agentic coding system, I now separate three questions that are often collapsed into one sentence:
| Question | Evidence that can answer it | Evidence that cannot answer it alone |
|---|---|---|
| What shipped? | Registry metadata, version map, exact tarball hashes | A marketing headline or a package name |
| What is guarded? | Pinned source branches, error messages, call placement | A diagram that omits control flow |
| Did it work reliably? | Reproducible runs with a fixed task set, environment, repetitions, and scoring | A guard, a release number, or a single successful demo |
This ladder also gives a better review workflow. First pin the artifact. Then inspect the implementation path that claims to validate work. Only after that should a team design a measurement harness. The harness needs a task corpus, model and dependency versions, execution protocol, success rubric, and failure categories. Without those controls, “verification” remains an architectural property, not an outcome measurement.
For a related treatment of those controls, see the harness-engineering measurement audit. For a complementary discussion of specified validator handoffs versus enforcement, see engineering discipline in AI coding agents.
What I would change in the old conclusion
I would not repeat “verification beats flexibility,” and I would not preserve the old 100%-reliability implication. The source record does not contain the controlled comparison required for either statement. A more defensible conclusion is narrower:
AutoBE’s source exposes explicit checks around when work may be considered complete, and its realization helper shows how generated projects are prepared for build-and-test execution. A byte-level comparison of compiler 0.30.5 and 0.31.1 finds 133 identical regular members out of 134, with the only changed member being package metadata. These facts describe release identity and verification boundaries; they do not measure backend reliability or establish an AutoBE-versus-Claude Code winner.
That sentence is less likely to be quoted out of context because its limits are part of the claim. It also gives an engineer a next action: define the missing harness rather than infer an outcome from an implementation sketch.
Key Takeaways
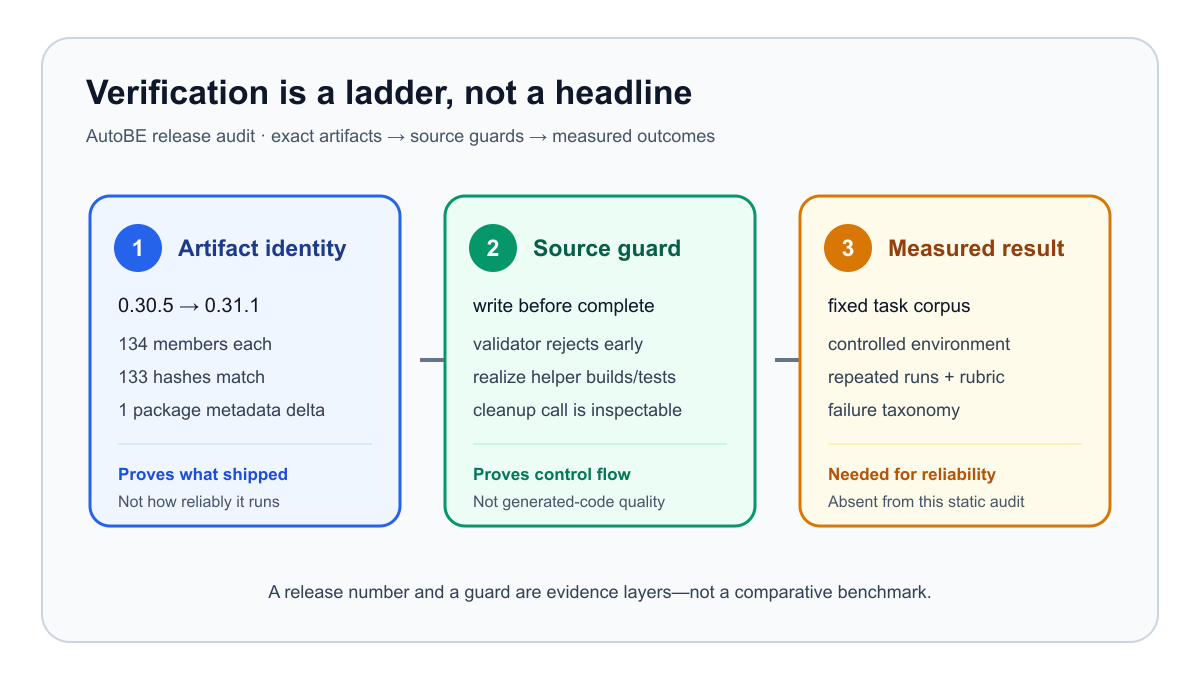
- The current compiler package comparison is a release-artifact observation: 133 of 134 regular members match between 0.30.5 and 0.31.1, with
package/package.jsonas the changed member. - The preliminary validator exposes a write-before-complete ordering guard, while the realization helper exposes build, test, worker, and cleanup boundaries.
- Neither source-traced guard nor the byte-level release result measures comparative reliability, correctness across workloads, or a winner against Claude Code.
New Questions
- Does the same generated project pass a fixed task corpus across both compiler releases when dependency resolution and environment are pinned?
- Which failure categories should an independent harness score: ordering violations, compilation failures, behavior-test failures, dependency drift, and cleanup failures?
- Can the realization helper’s temporary-directory and worker-lifetime boundaries be exercised under controlled failure injection without conflating static code shape with runtime behavior?
References
Registry and release artifacts
- npm registry metadata for
@autobe/compiler, retrieved 2026-10-15 08:47:37 UTC. The comparison used the 0.30.5 and 0.31.1 tarballs listed by the registry. - Exact compared tarball:
@autobe/compiler@0.30.5, and exact compared tarball:@autobe/compiler@0.31.1, retrieved 2026-10-15 08:47:37 UTC.
Pinned implementation
@autobe/compiler@0.31.1realization helper, source coordinate lines 22–78, retrieved 2026-10-15 08:47:37 UTC.@autobe/agent@0.31.1preliminary validator, source coordinate lines 39–153, retrieved 2026-10-15 08:47:37 UTC.
Legacy context
- Archived comparison, inspected 2026-10-15 08:39:00 UTC. Its comparative and percentage framing is retained here only as a suppression record; it is not used as evidence for a reliability claim.
The release comparison was performed over package members with Python’s standard-library archive and hashing modules. No package was installed or executed for this audit, so no runtime pass rate, production result, traffic outcome, or revenue outcome is claimed.
Editorial method: claims in this article point to primary documentation, pinned source code, runnable checks, or dated measurements, with AI-assisted research under the site's evidence-gated policy. How this site verifies claims and discloses AI assistance · Report a correction.
Working on something like this?
I take a small number of paid, scoped reviews: AI agent/RAG architecture diagnosis, Unity CI & build-automation audits, and multimodal QA design review. Each one ends in a written findings document.
Work with me