Scaling Monosemanticity: Mechanistic Interpretability via Sparse Autoencoders
A foundational source audit of Anthropic’s landmark research on Sparse Autoencoders, dictionary learning, and causal feature steering in frontier transformer models.
LATEST INVESTIGATIONS
A foundational source audit of Anthropic’s landmark research on Sparse Autoencoders, dictionary learning, and causal feature steering in frontier transformer models.
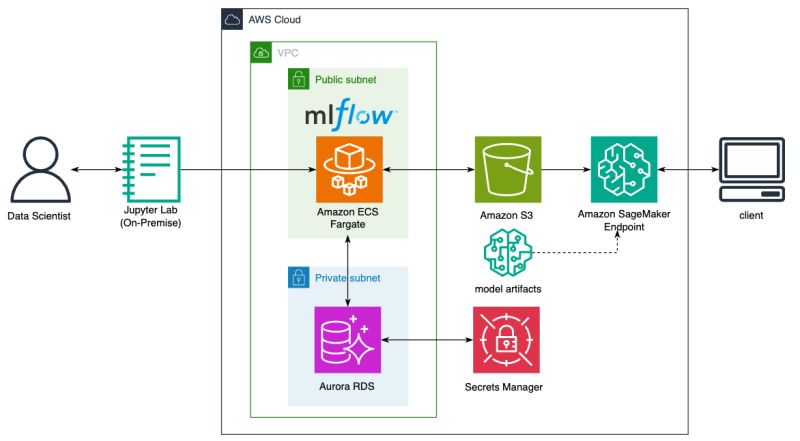
A source audit evaluating hybrid MLOps architectures, combining on-premises GPU training clusters with AWS MLflow tracking and SageMaker managed inference endpoints.

A source audit analyzing LLM inference bottlenecks, contrasting compute-bound prefill and memory-bound decode, continuous batching, and speculative decoding.
A technical source audit analyzing post-training compute scaling, state-space architectures, mixture-of-agents, and quantization frontiers across modern LLMs.

A source audit analyzing multi-agent systems, comparing CrewAI role orchestration with AgentGym environments, trajectory cloning, and SLA circuit breakers.

A source audit analyzing Meta’s Chameleon foundation model, evaluating discrete image tokenization, QK-normalization, and native mixed-modal pretraining.

A source audit analyzing Uni-MoE’s unified multimodal architecture, sparse mixture-of-experts routing, and three-stage cross-modality alignment pipelines.
A source audit analyzing Mistral-finetune, evaluating PyTorch FSDP integration, LoRA target projections, instruction formatting, and multi-GPU memory scaling.

A source audit evaluating software technical interviews, contrasting algorithmic LeetCode drills with system design, deep codebase navigation, and AI harness testing.

A source audit analyzing autonomous self-evolution in LLMs, evaluating self-instruct, iterative DPO, self-rewarding verification, and model collapse boundaries.
Search article titles, categories, and tags. Full text is searched when needed.
Type to search articles.