AI
NeRF vs Gaussian Splatting Requires More Than an FPS Test
A source audit of radiance, compositing, licenses, and Unity rendering shows why choosing Gaussian Splatting does not make a captured scene a game asset.
Does choosing Gaussian Splatting make a captured scene ready for a game?
The short comparison in this May 2024 note gave NeRF the quality column and Gaussian Splatting the production column. Re-reading the primary papers and the implementation changes that decision. Both methods represent view-dependent appearance. Both accumulate contributions along a viewing path. Neither the name of the representation nor an attractive frame rate establishes that a reconstructed scene can participate in a game’s lighting, transparency, or collision systems.
The sharper distinction is between the cost of querying a learned field and the cost of projecting, ordering, and blending explicit primitives. A separate distinction concerns what a particular renderer implements. A third concerns the rights attached to the training code and the captured material. These questions meet at deployment, but they require different evidence.
This Source Audit inspects the original NeRF and 3D Gaussian Splatting papers, commit-pinned source and licenses, the later gsplat implementation, and a community Unity renderer. The only executed experiment is a small CPU arithmetic check of compositing weights. No reconstruction was trained, no GPU rendering benchmark was run, and no Unity scene was tested for this rebuild. Engine findings below describe the inspected renderer, rather than every possible Gaussian Splatting integration.
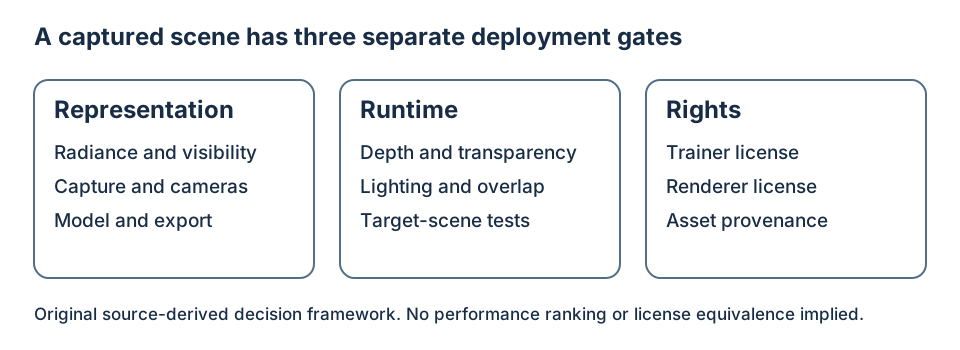
Original diagram derived from the inspected sources; the three gates are this article’s decision framework, not a measured benchmark.
Both representations carry view-dependent radiance
In the original NeRF paper, a neural network receives a spatial position and a viewing direction. It predicts volume density and emitted color. Density depends on position; the color branch also receives direction. A camera image is obtained by sampling along rays and integrating those predictions. Calling the network’s output simply “RGBA per point” loses an important dependency: opacity is derived from density and the distance represented by a sample.
The original 3D Gaussian Splatting method instead optimizes an explicit collection of anisotropic Gaussians. Each has a position, covariance-related parameters, opacity, and appearance coefficients. Its real-scene workflow initializes the representation from sparse points and camera information recovered through structure from motion. This is not a universal requirement: the pinned synthetic Blender loader can initialize random points. Training changes the collection through optimization and density control; it is not just the original sparse point cloud displayed more quickly. Both original papers address static-scene novel-view synthesis.
Nor is its color necessarily constant. At the audited official commit 54c035f, gaussian_renderer/__init__.py evaluates spherical harmonics using a normalized direction between the camera and Gaussian positions when the Python evaluation path is selected. That is a concrete source-level reason to reject “NeRF has view dependence, splats do not” as a decision rule. The appearance representation differs, while both originals account for changing viewing direction.
The phrase “Gaussian Splatting has no neural network” is useful only when scoped to the original method’s directly optimized Gaussian parameters. It does not forbid another system from predicting Gaussian attributes or adding a learned appearance component. The safe comparison is between these inspected implementations, rather than a claim about every method that later adopted either label.
| Decision | Original NeRF | Original 3D Gaussian Splatting | What to establish before choosing |
|---|---|---|---|
| Stored representation | Network parameters describing a radiance field | Explicit Gaussian parameters and appearance coefficients | Which representation and export format the target runtime accepts |
| Image formation | Ray sampling and density-based accumulation | Projection, ordering, and alpha blending of Gaussian contributions | The actual renderer and its camera/visibility assumptions |
| View-dependent appearance | Direction-conditioned color prediction | Spherical-harmonic appearance | Behavior along the camera paths the application will use |
| Scene preparation | Images with known camera information | Camera information and sparse reconstruction in the original workflow | Whether capture and calibration are sufficiently reliable |
| Engine integration | Requires a suitable field renderer or another derived representation | Requires a splat renderer with explicit integration behavior | Depth, transparency, lighting, and interaction requirements |
This table is an analytical comparison of the original designs. It is not a ranking of visual quality, training time, or commercial readiness. A quality ranking needs a specified dataset, camera split, implementation, and metric; an engine decision also needs requirements that those metrics may never measure.
Density and opacity meet in the compositing weights
The original 3DGS paper explicitly relates its image formation to volume rendering while distinguishing the rendering algorithms. That connection makes the familiar “continuous versus discrete” comparison less decisive than it first appears. The representation changes how contributions are obtained; it does not remove the need to account for visibility and transmittance.
For a NeRF sample with density sigma over a ray interval delta, its alpha contribution is 1 - exp(-sigma * delta). Each sample’s color is then weighted by that alpha and by the transmittance left after the samples before it. Gaussian rasterization likewise blends contributions using alpha and the preceding transmittance, although projection, Gaussian footprint, opacity, and ordering determine its contributions differently.
An arithmetic example exposes why “RGBA at a point” is too loose. Set sigma to ln(2) and delta to 1. The resulting alpha is 0.5. With a red contribution followed by a blue contribution, each with that alpha, the weights are 0.5 and 0.25, leaving 0.25 transmittance for the background. Reversing their order would change which color receives the larger weight.
1
2
3
4
5
6
7
8
9
10
11
import math

alpha = 1 - math.exp(-math.log(2) * 1.0)
transmittance = 1.0
rgb = [0.0, 0.0, 0.0]
for color in [(1.0, 0.0, 0.0), (0.0, 0.0, 1.0)]:
    weight = transmittance * alpha
    rgb = [out + weight * channel for out, channel in zip(rgb, color)]
    transmittance *= 1 - alpha
print(rgb, transmittance)
# [0.5, 0.0, 0.25] 0.25
The displayed snippet was executed with python3 - (code supplied on standard input) on 2026-10-14 and printed [0.5, 0.0, 0.25] 0.25. A separate run also checked assertions for alpha, weights, RGB, and residual transmittance. This verifies the numerical illustration only. It neither reproduces a NeRF renderer nor models the projected footprint and ordering of a real splat scene. Its practical lesson is narrower: densities, alphas, and final pixel contributions are different quantities, and contribution order matters.
What changed since the May 2024 comparison?
The ecosystem now offers additional implementation choices beyond the two original repositories. At gsplat commit 512d366, the rendering implementation documents features including antialias compensation associated with Mip-Splatting and camera distortion and rolling-shutter support referencing 3DGUT. Its top-level license and rendering source identify Apache-2.0 licensing. These are findings about that pinned library, rather than proof that a Unity importer or another training frontend exposes the same capabilities.
That distinction changes a production evaluation. A feature in a CUDA backend, a setting available through a trainer, an attribute preserved in an exported file, and a feature implemented by an engine renderer are separate links in a pipeline. Evidence for one link cannot stand in for the others. For example, documentation of camera handling in a backend does not establish that an existing engine asset will render with equivalent camera behavior.
The audited community Unity project at 2c6fed3 makes another part of the problem visible. Its render-pipeline integration document says the renderer tests splats against the opaque scene’s depth buffer but does not write splat depth. It describes poor interaction with ordinary transparency, no interaction with Unity lights, shadows, probes, or lightmaps, and only approximate ordering between separate overlapping splat objects.
These are documented limitations of that implementation. They should not be generalized into a theorem that splats can never support other rendering features. They do, however, defeat the old note’s broad recommendation of Gaussian Splatting for “production”: this particular runtime has integration boundaries that a captured-scene preview can conceal.
For a game, the consequence is a set of concrete tests. Move an opaque object through the captured scene. Place transparent geometry in front of and behind it. Change lighting if the design expects relighting. Overlap two imported splat assets. Record what is expected before running the tests. Collision requires its own representation and validation; this rendering audit did not establish a collision pipeline. None of those proposed scene checks was executed here.
The related LangSplat source audit follows a different extension: associating language features with splats. It demonstrates why downstream functionality and performance claims need their own evidence. The NPGA paper article provides a separate Gaussian-based avatar context; its application should likewise be evaluated on its own assumptions, rather than inheriting the static-scene comparison above.
A permissive viewer does not settle the capture pipeline’s rights
The license comparison is particularly easy to get wrong because “Gaussian Splatting” describes a method, rather than one software package. The original bmild/nerf implementation has an MIT license at the inspected commit 14c5556. The original graphdeco-inria/gaussian-splatting repository has a different license: its research-user grant concerns non-commercial research and evaluation, and its terms restrict other or commercial uses without consent. Calling both “open source, ready to ship” erases that difference.
Later implementations have their own licenses. The inspected gsplat files identify Apache-2.0. The audited community Unity renderer identifies MIT. Neither observation changes the license of the original research implementation. Nor does a renderer’s license establish that a scene file was acquired or created under terms allowing the intended use.
The Unity repository’s README makes this separation explicit: its license does not settle how the input PLY files were obtained. That is unusually useful operational guidance. It directs attention away from the viewer alone and toward the toolchain and material used to create the asset.
This article does not determine the legal status of a particular trained output. The auditable action is to record the training implementation and its terms, the renderer and its terms, and the capture or downloaded asset’s provenance separately. A permissively licensed component is evidence about that component. It is not evidence that the whole pipeline, every dependency, or every asset has the same permission.
| Gate | Evidence to retain | What a passing screenshot cannot establish |
|---|---|---|
| Capture and representation | Source images, camera preparation, model/trainer revision, export format | Reliable behavior outside the inspected camera paths |
| Runtime integration | Renderer revision and scene tests for depth, transparency, lighting, and overlap | Correct engine behavior merely because novel-view synthesis looks convincing |
| Code and asset rights | Relevant license files plus capture/download provenance | Permission for the entire pipeline from the viewer’s license alone |
Choose the evaluation boundary before choosing the representation
For an offline reconstruction experiment, image quality under a specified protocol may be the main question. For a captured environment preview, camera navigation and acceptable visual artifacts may matter more. For an interactive game asset, the runtime’s interaction with the rest of the scene becomes an additional requirement. The method name does not decide which of these products is being built.
My inference from the inspected sources is to separate the evaluation into three gates: reconstruction, runtime integration, and rights. Define a failure condition for each gate before comparing performance. A renderer that passes the reconstruction gate can still fail an interaction requirement. A renderer that meets both technical gates can still leave a license or asset-provenance question unresolved.
Only then compare speed and memory on the intended workload. Record the camera path, output resolution, scene size, hardware, settings, and exact implementation. Include the engine configuration when that is the deployment target. A paper’s timing and a standalone viewer’s frame rate are useful within their respective measurement scopes; neither is a substitute for that application-specific check.
The repaired conclusion is therefore more useful than the old winner table: explicit splats change the computation and available implementation choices, while production readiness remains a property of the complete pipeline and its requirements. That conclusion is a decision framework derived from the source audit, not a claim that either representation always wins.
Key Takeaways
- Original NeRF and 3DGS both model view-dependent radiance. Their stored representations and rendering paths differ; neither label establishes a universal quality ranking.
- NeRF’s density is converted to alpha using the ray interval. The executed CPU example verifies compositing arithmetic, not rendering performance.
- Later backend features must be traced through the trainer, export, and target renderer. A backend capability does not prove an engine integration supports it.
- The audited Unity renderer documents depth, transparency, lighting, and object-ordering boundaries. Test those boundaries against the intended scene.
- Record trainer, renderer, and asset provenance separately. MIT or Apache-2.0 on one component does not settle the rest of the pipeline.
New Questions
- Which depth and transparency artifacts become unacceptable along the intended player camera path?
- Which appearance and camera parameters survive the chosen training-to-engine export?
- Does the application need a separate collision or editable geometry asset alongside the captured appearance?
- Can the complete capture, training, export, and rendering chain be documented with terms appropriate for the intended use?
References
Primary papers — read on 2026-10-14:
- Mildenhall et al., NeRF: Representing Scenes as Neural Radiance Fields for View Synthesis, arXiv v2, sections 3–4; network structure and volume rendering.
- Kerbl et al., 3D Gaussian Splatting for Real-Time Radiance Field Rendering, arXiv v1, sections 2–6; representation, image formation, initialization, and density control.
Pinned implementations and licenses — read on 2026-10-14:
- Original NeRF implementation at
14c55567a6d0fbd75d3fd12b0411f98160ba3237and its MIT license. - Official 3DGS renderer at
54c035f7834b564019656c3e3fcc3646292f727dand the research/evaluation license. - Synthetic-scene loader at the same 3DGS commit, including random-point initialization for the Blender path.
- gsplat rendering implementation at
512d366b67073d77ca099ede742683c165dfc23band Apache-2.0 license.
Engine integration documentation — read on 2026-10-14:
- Community Unity renderer README at
2c6fed37da67a217367261fcfcd3316d34c73e76, including its MIT license and input-asset caveat. - Render-pipeline integration limitations at the same commit.
Editorial method: claims in this article point to primary documentation, pinned source code, runnable checks, or dated measurements, with AI-assisted research under the site's evidence-gated policy. How this site verifies claims and discloses AI assistance · Report a correction.
Working on something like this?
I take a small number of paid, scoped reviews: AI agent/RAG architecture diagnosis, Unity CI & build-automation audits, and multimodal QA design review. Each one ends in a written findings document.
Work with me