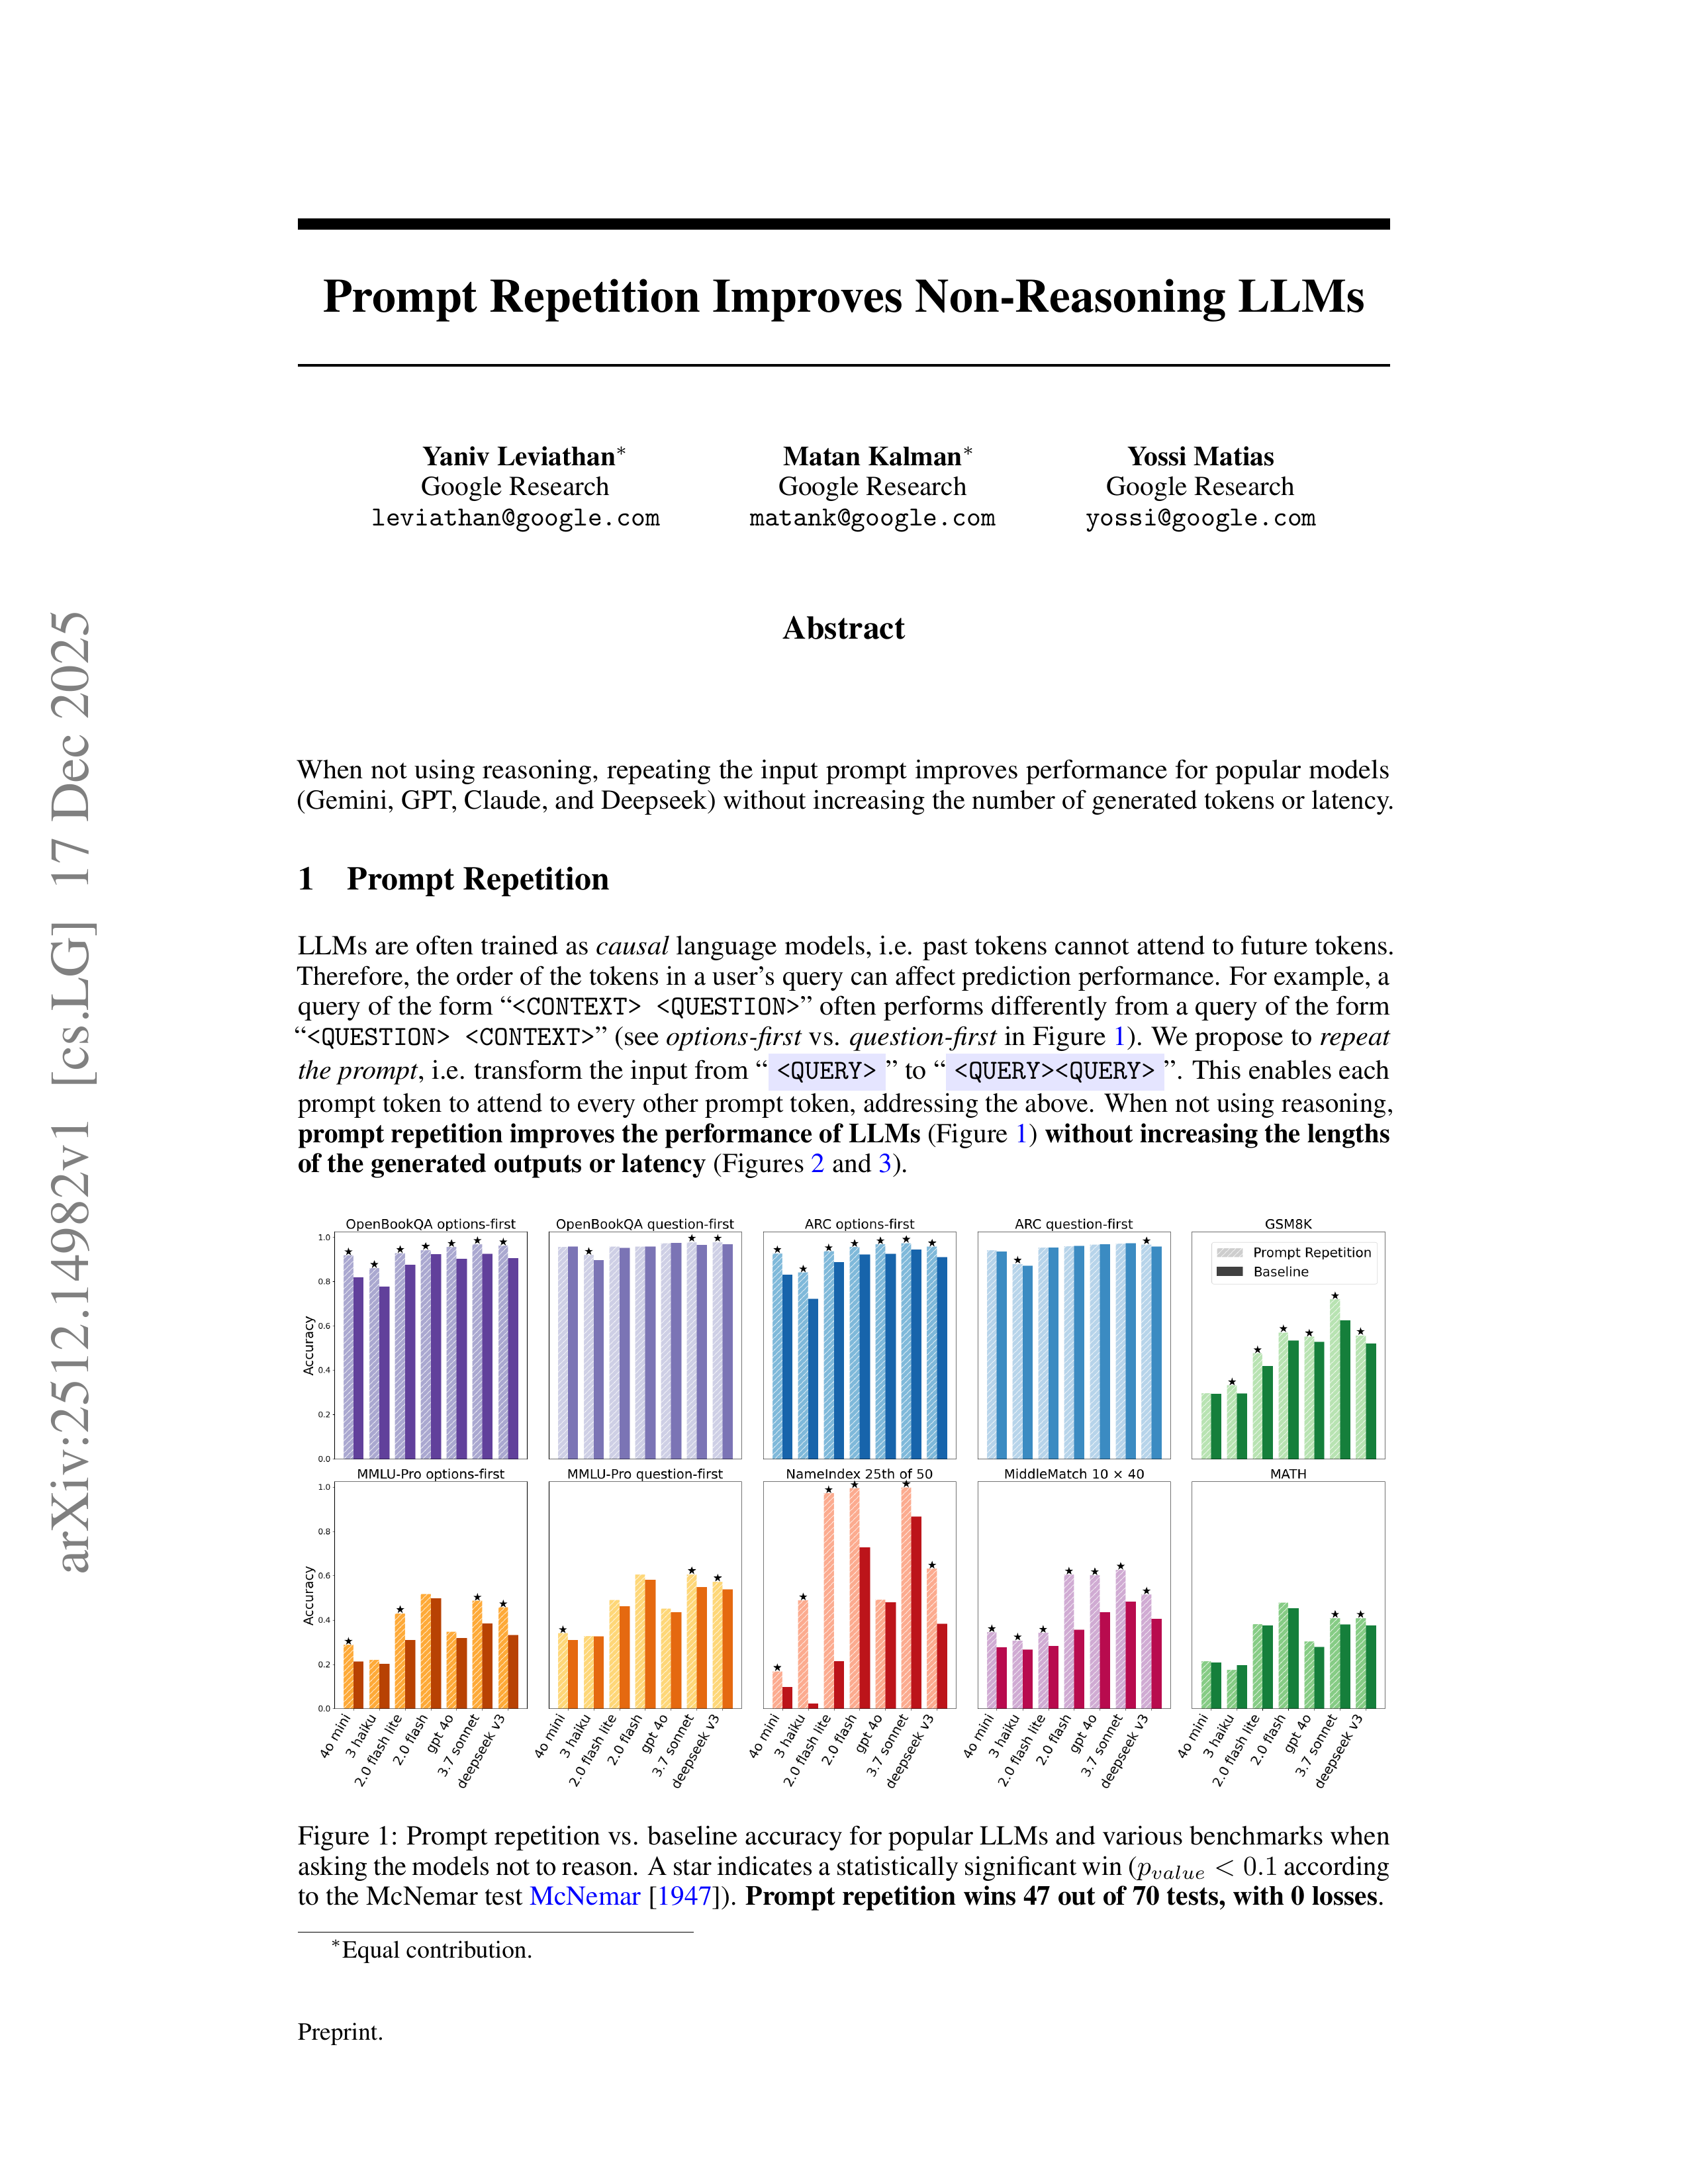
Prompt Repetition: Approximating Bidirectional Attention in Causal LLMs
A source audit of Google Research’s prompt repetition study (arXiv:2512.14982), analyzing how duplicating input tokens fixes causal attention blind spots in non-reasoning LLMs.
LATEST INVESTIGATIONS
A source audit of Google Research’s prompt repetition study (arXiv:2512.14982), analyzing how duplicating input tokens fixes causal attention blind spots in non-reasoning LLMs.
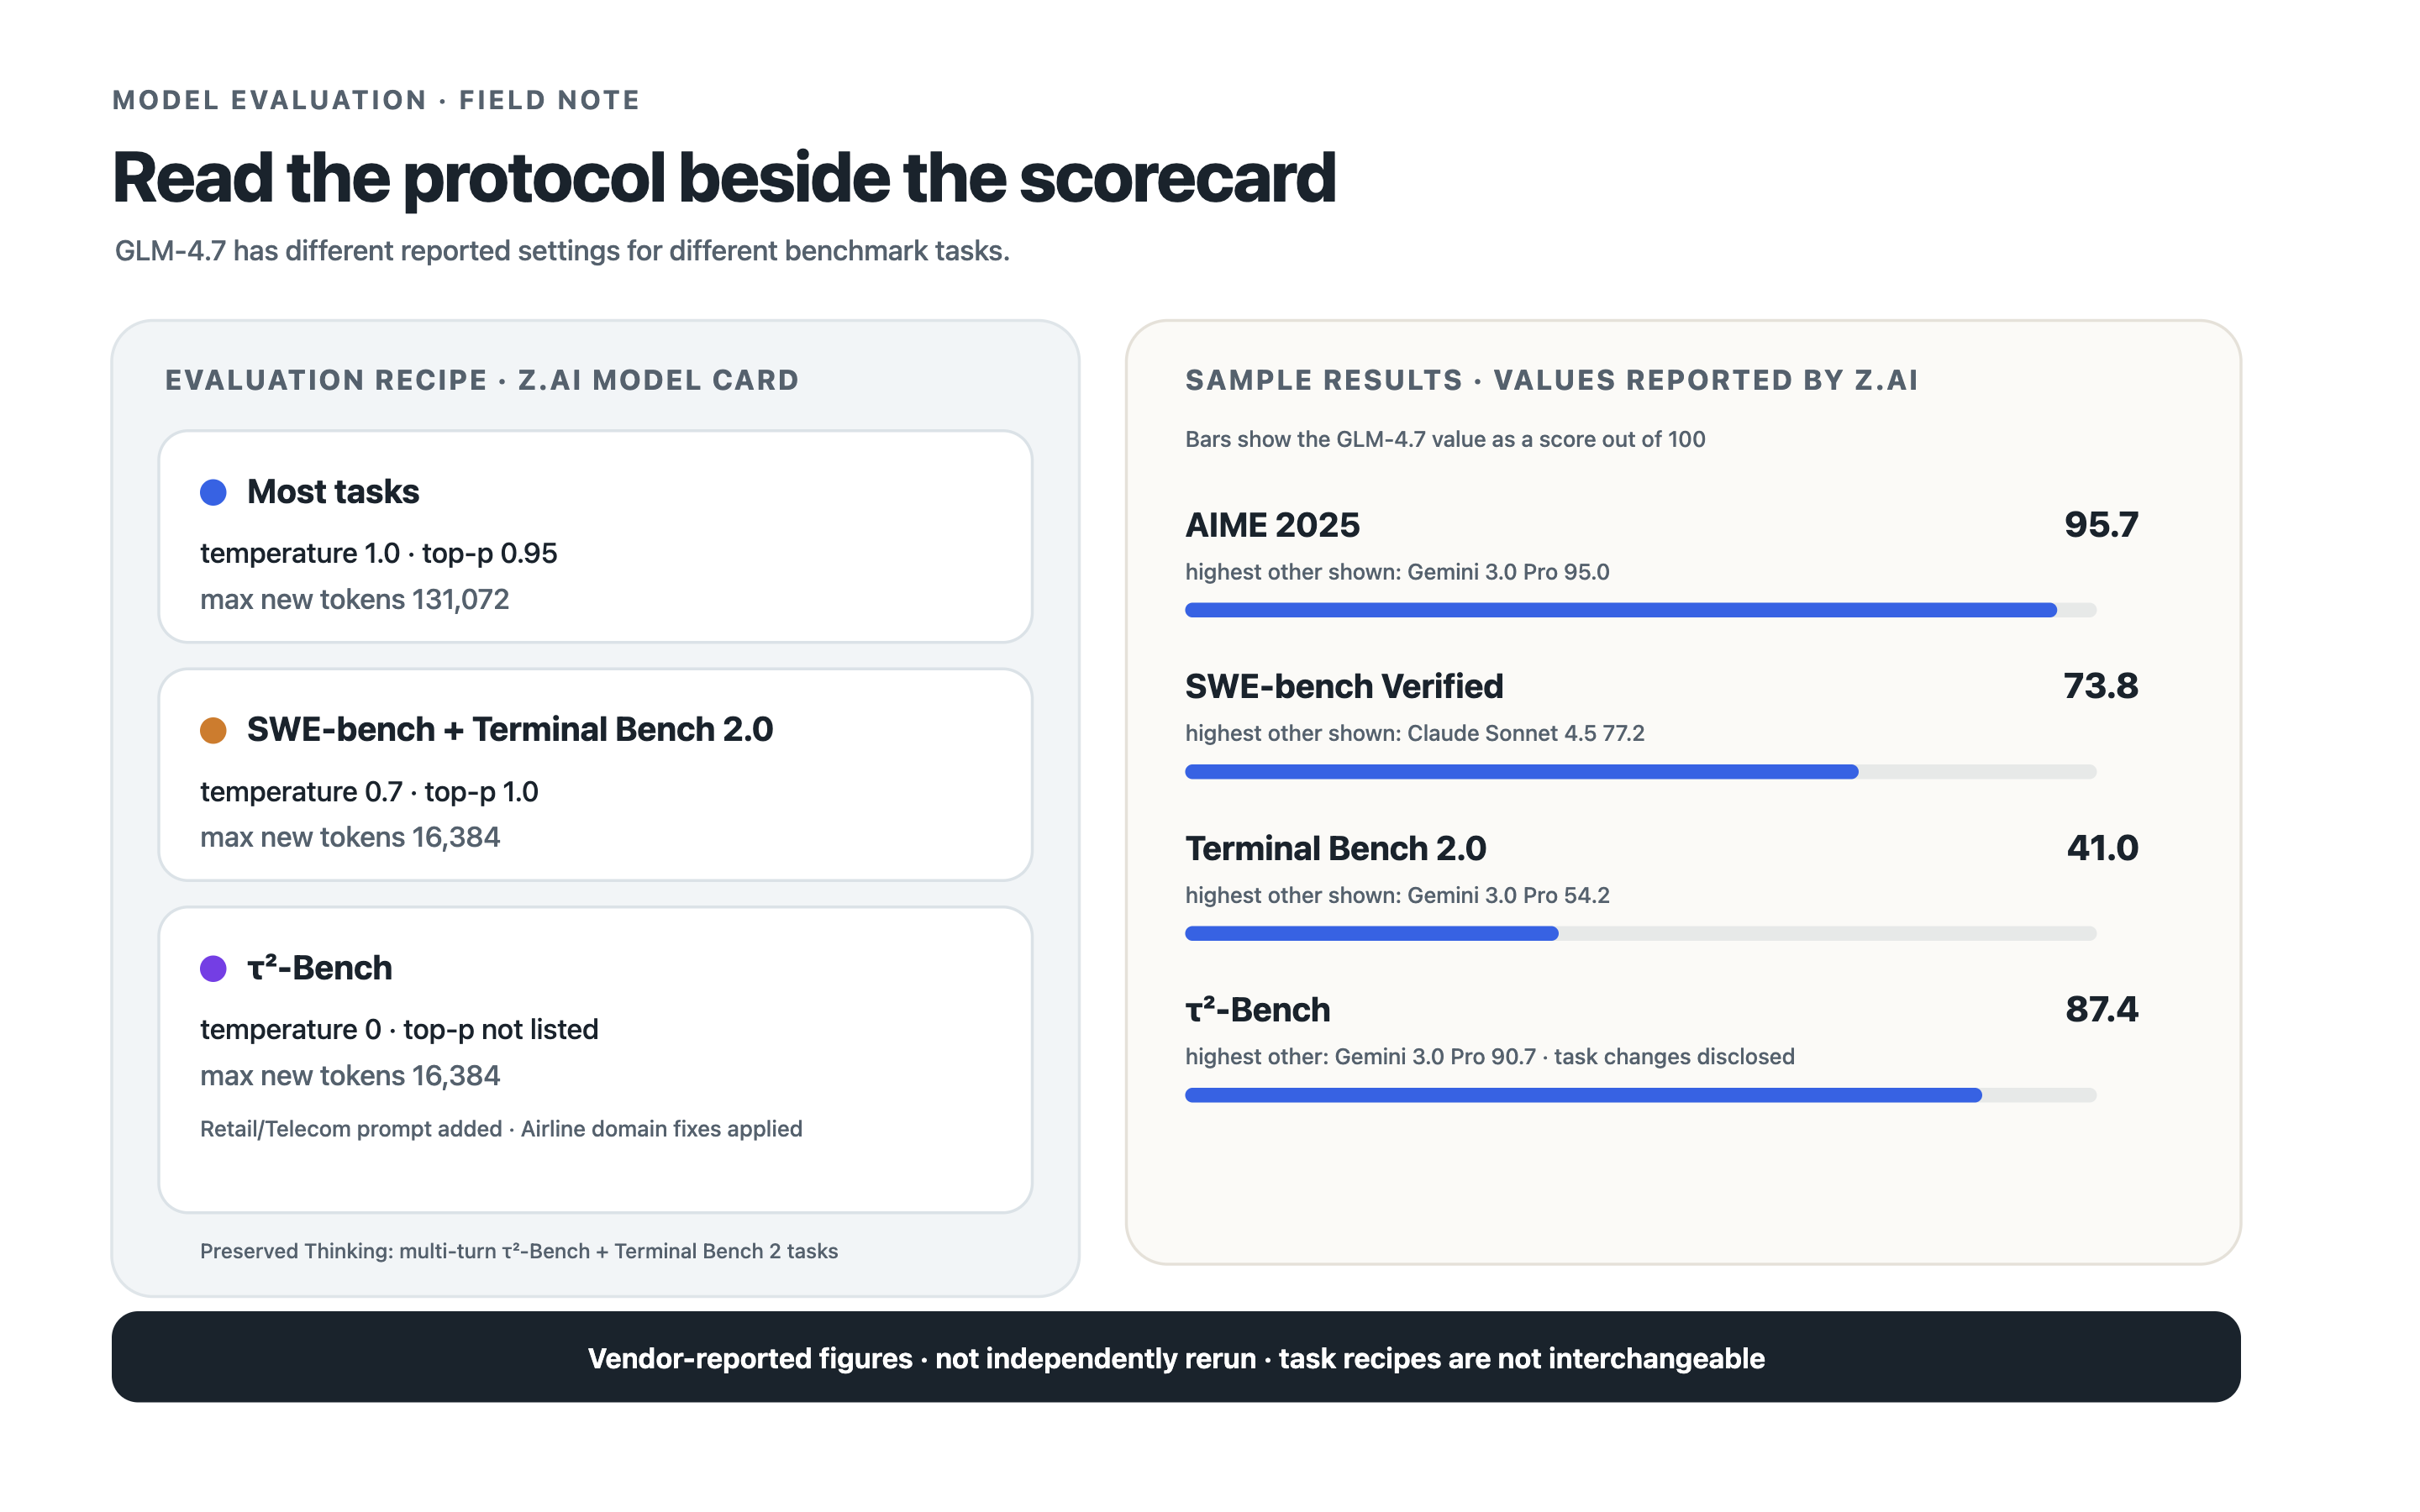
A source-bound reading of GLM-4.7’s reported scores, task-specific decoding settings, τ²-Bench changes, and what the results can establish.
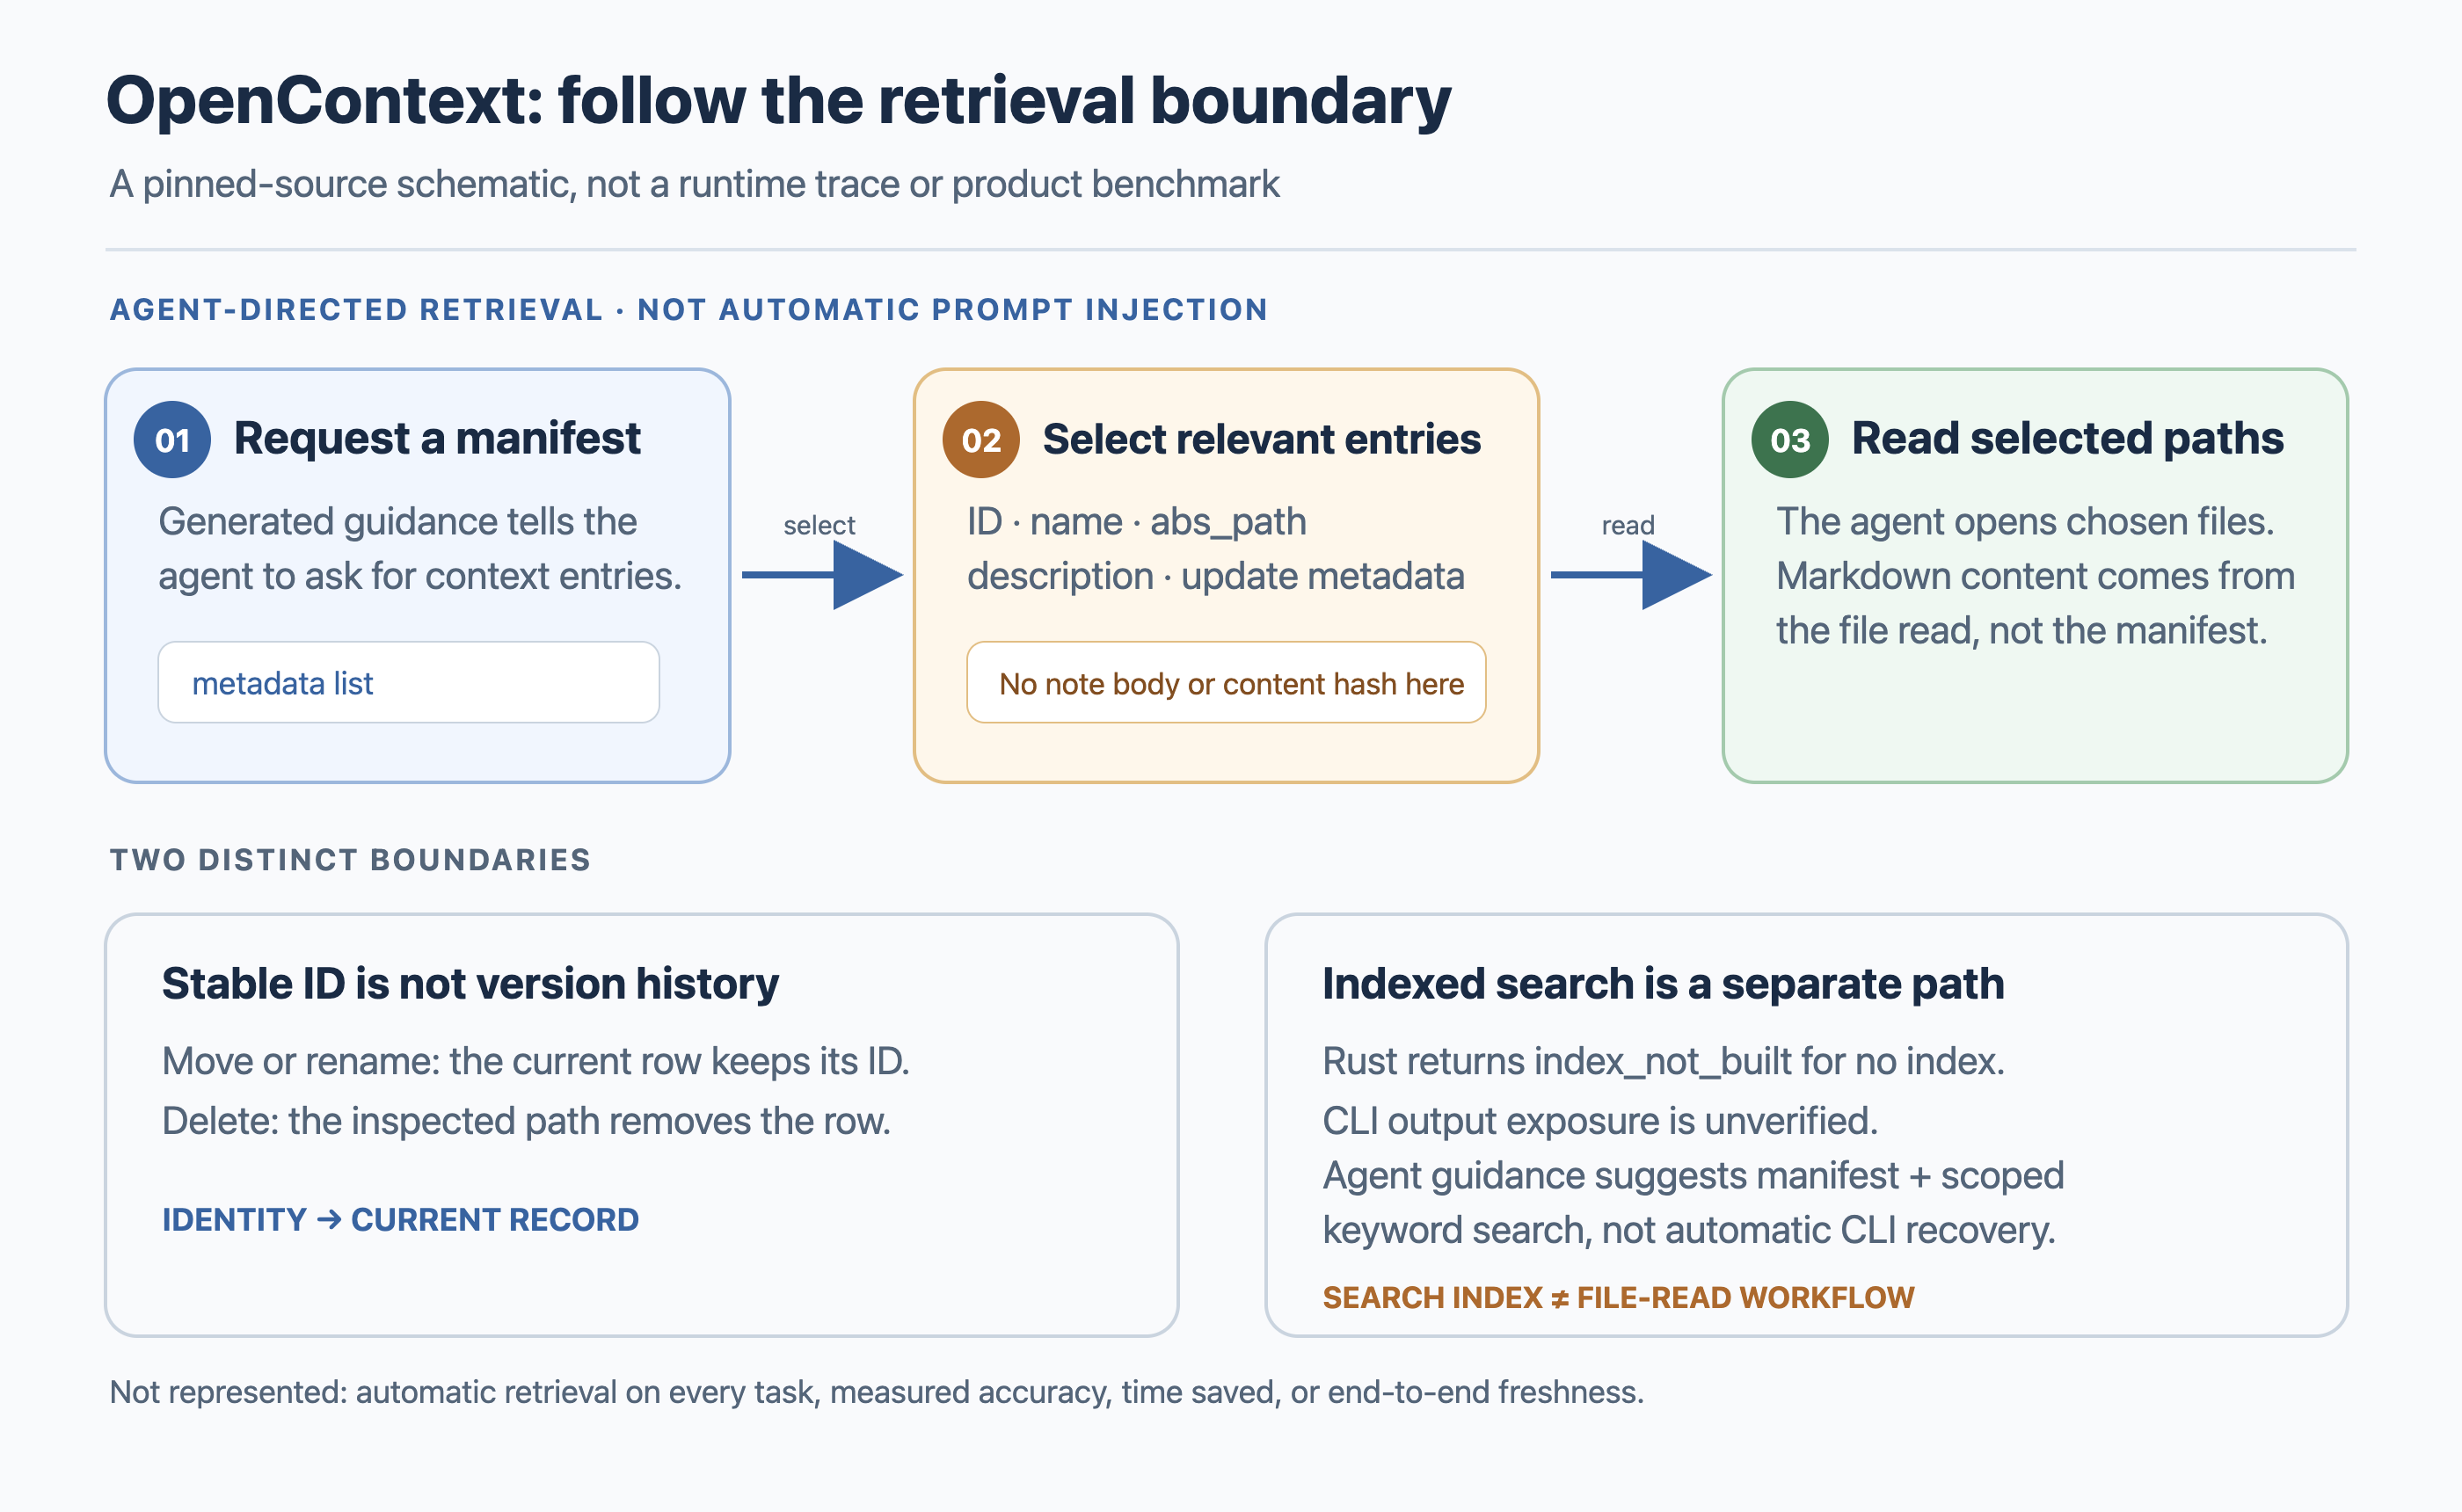
A source audit separates OpenContext’s Markdown store, agent guidance, manifest metadata, stable IDs and indexed search, without claiming automatic memory or benchmark gains.

Deconstruct architectural innovations in frontier open-source models—from global self-attention and YaRN context scaling to dense synthetic data curation.
A source audit of Fareed Khan’s 17 agentic AI architectures in LangGraph, evaluating single-agent loops, multi-agent swarms, memory tiers, and 2026 production tradeoffs.
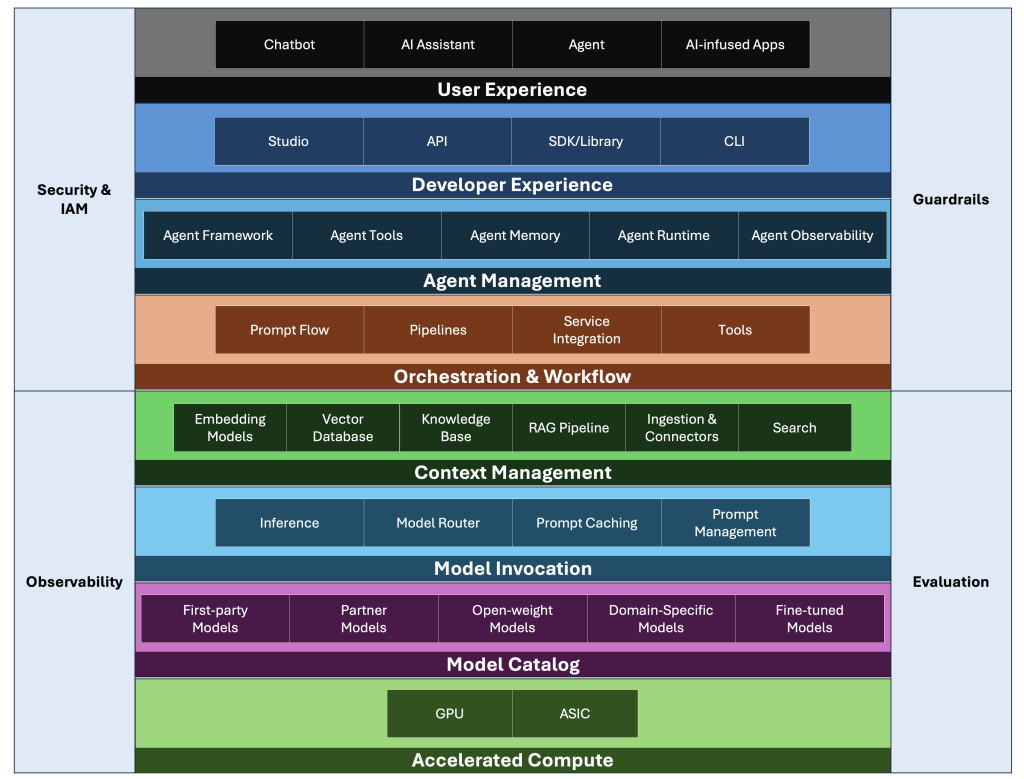
A source audit of production generative AI stacks, analyzing inference gateways, hybrid RAG pipelines, agent orchestration, and end-to-end observability.
A source audit of LangChain’s Deep Agents CLI evaluation on Terminal Bench 2.0 via Harbor, examining sandboxed harness execution and the leap from 42.5% to 66.5%.
Auditing huggingface/text-embeddings-inference: evaluating Rust tokenization, token-based dynamic batching, and FlashAttention kernel acceleration.
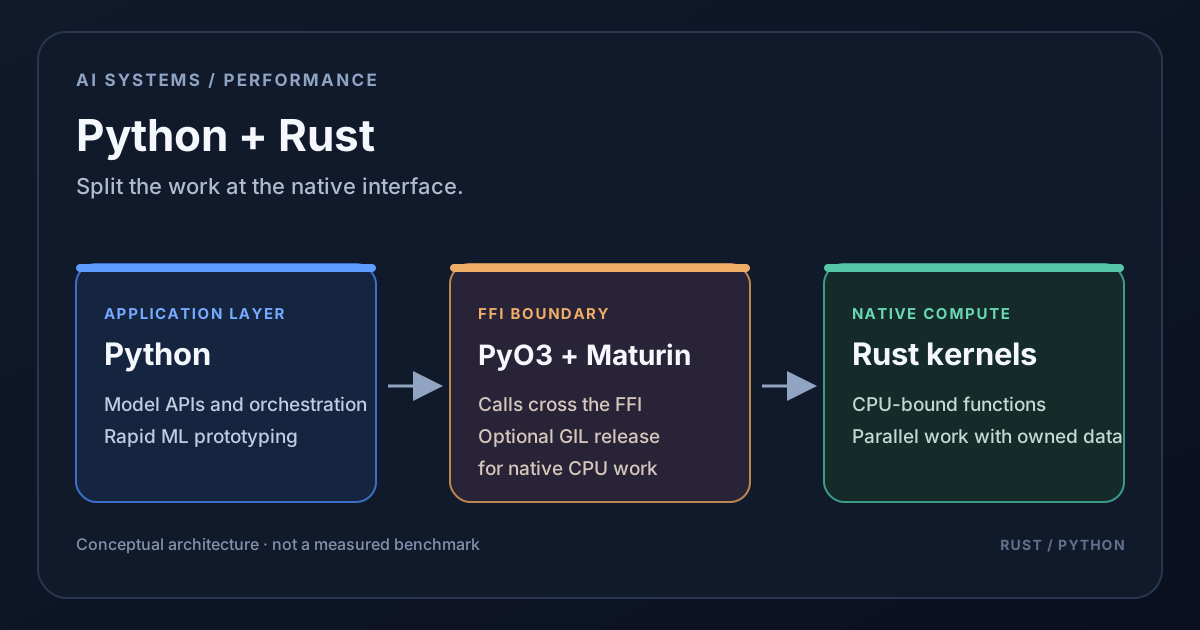
A source audit of Rust and Python integration in AI architectures, analyzing PyO3 FFI boundaries, zero-copy buffer sharing, and concurrent data pipelines.
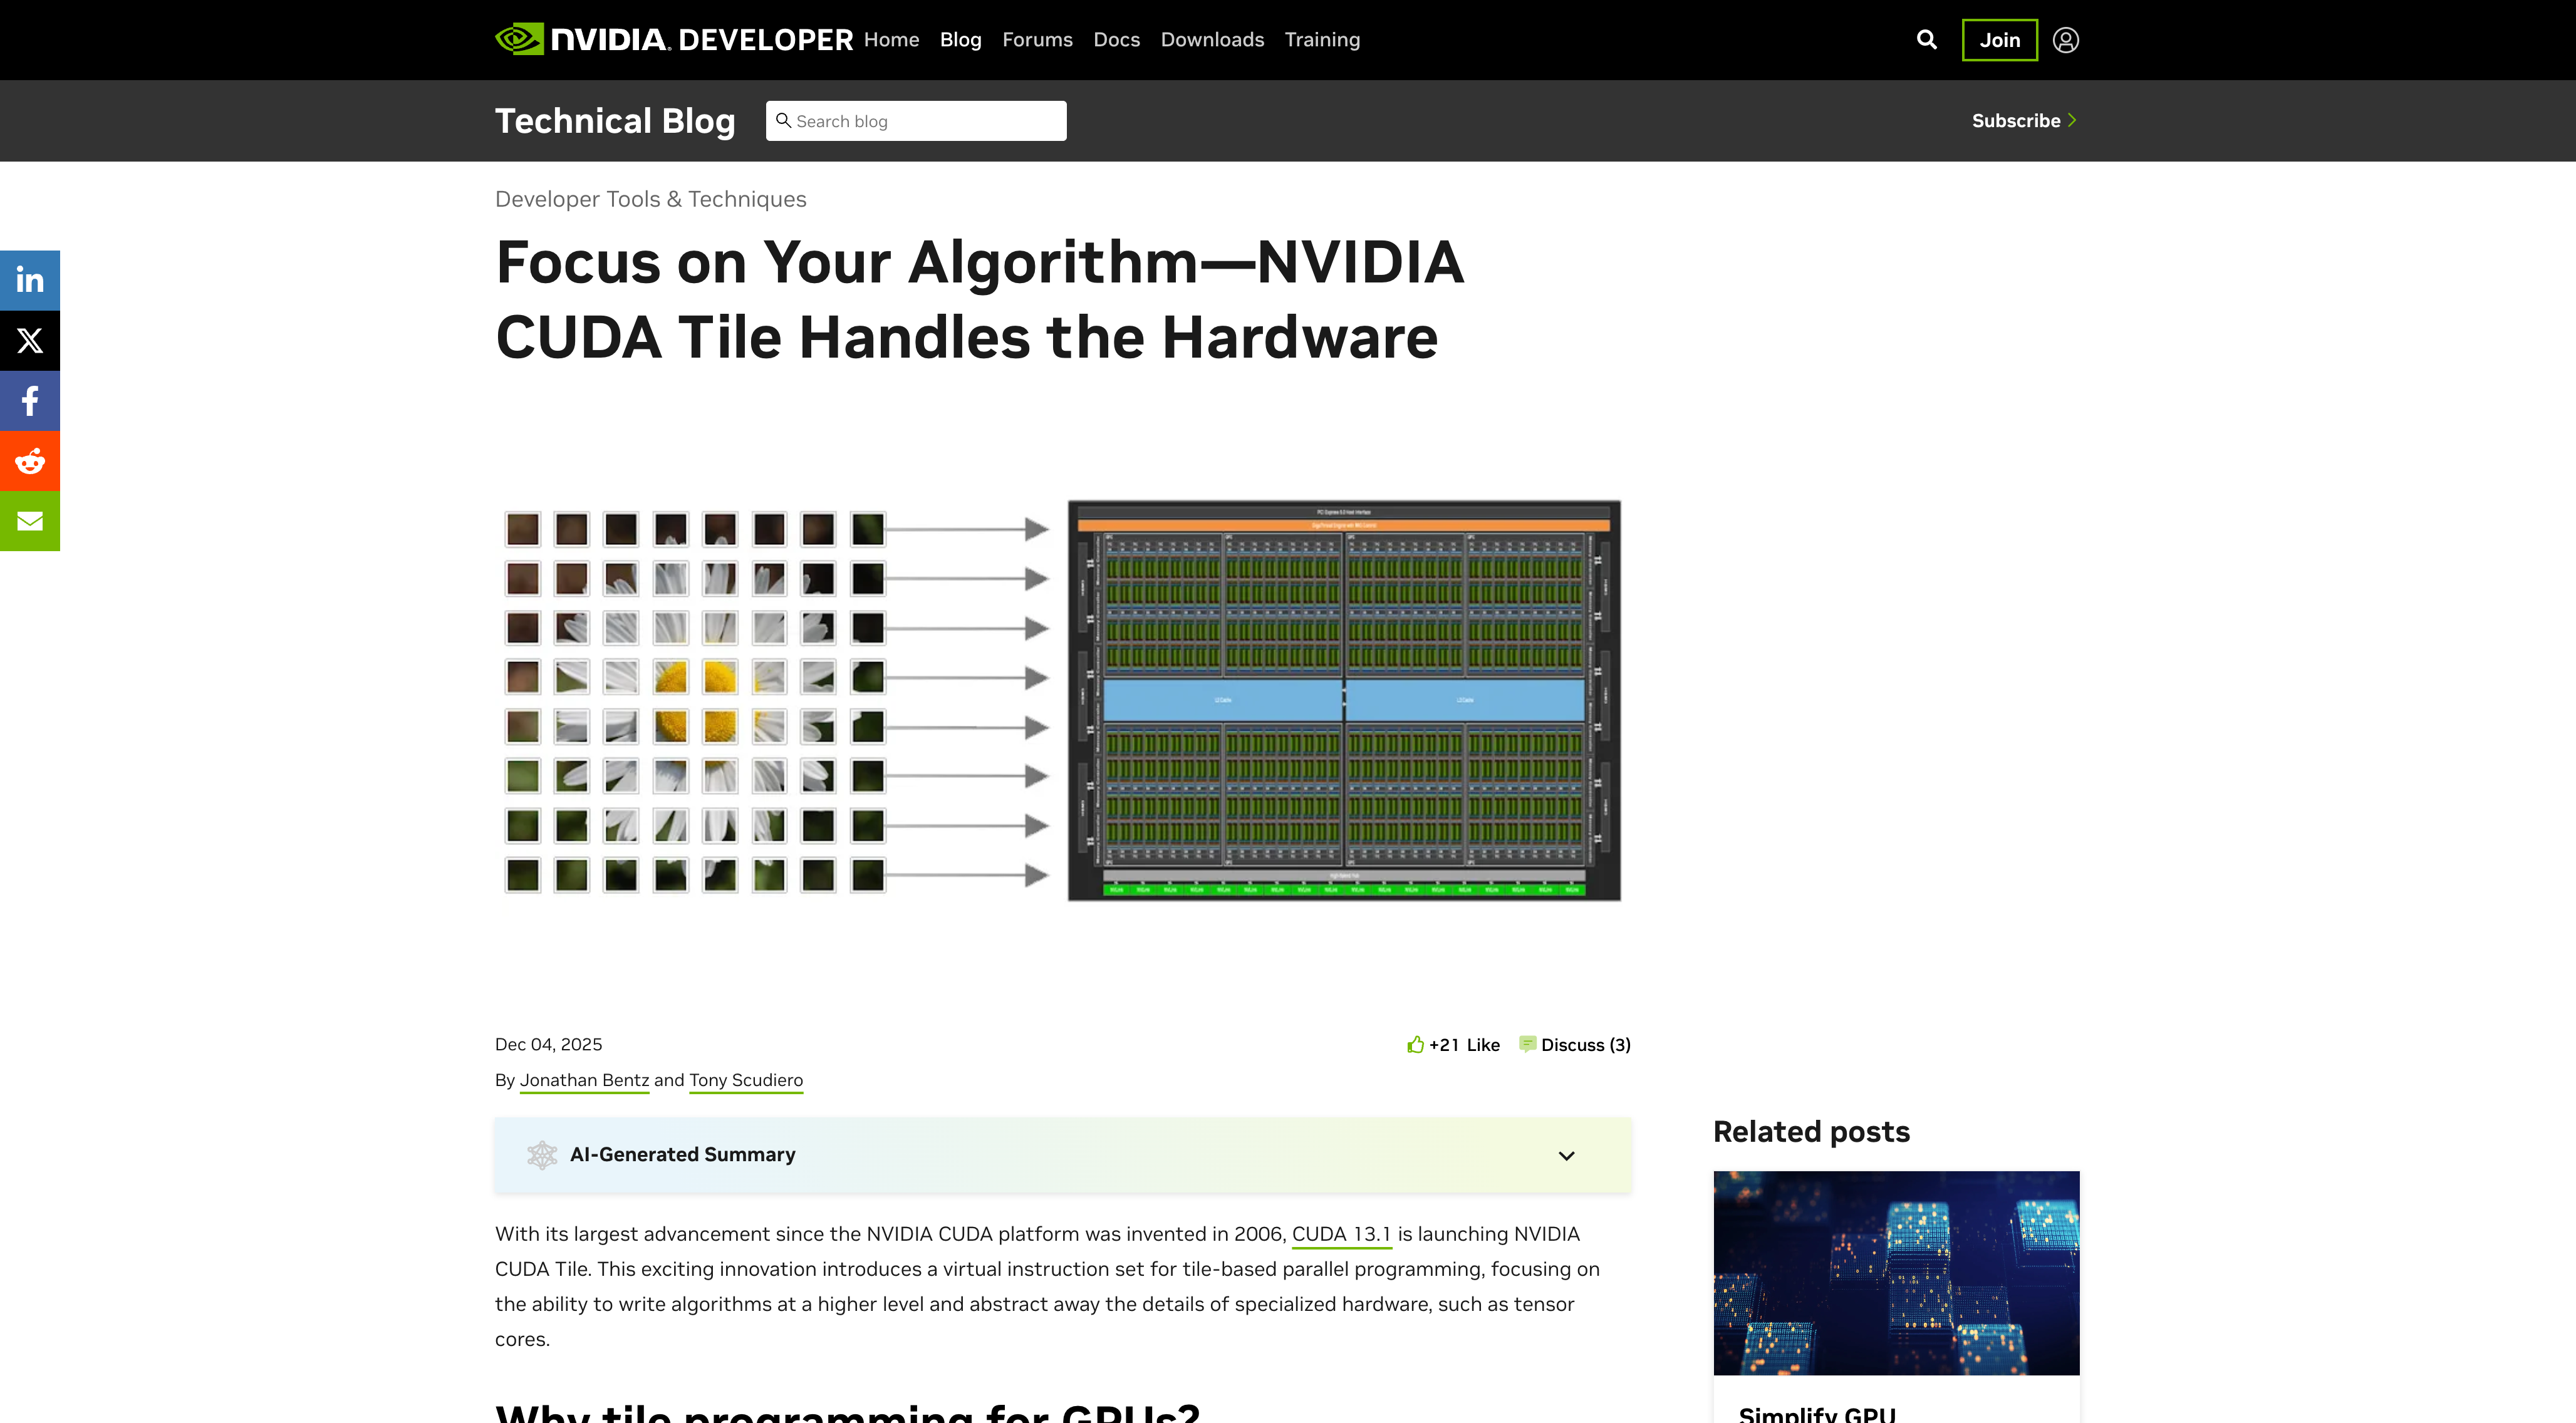
A source audit of NVIDIA CUDA Tile abstractions, evaluating tile-centric memory hierarchies, tensor core automation, and CUTLASS CuTe compilation.
Search article titles, categories, and tags. Full text is searched when needed.
Type to search articles.