LLM Quantization Architectures: GPTQ, AWQ, and GGUF Runtimes
GPTQ, AWQ, QAT, PTQ, GGML, GGUF, and K-quants compared from primary sources: what each method quantizes, what it preserves, and which trade-off to pick.
LATEST INVESTIGATIONS
GPTQ, AWQ, QAT, PTQ, GGML, GGUF, and K-quants compared from primary sources: what each method quantizes, what it preserves, and which trade-off to pick.

A source audit analyzing the LLaMA-Factory post-training framework, inspecting SFT, DPO, GaLore memory efficiency, and distributed orchestration pipelines.
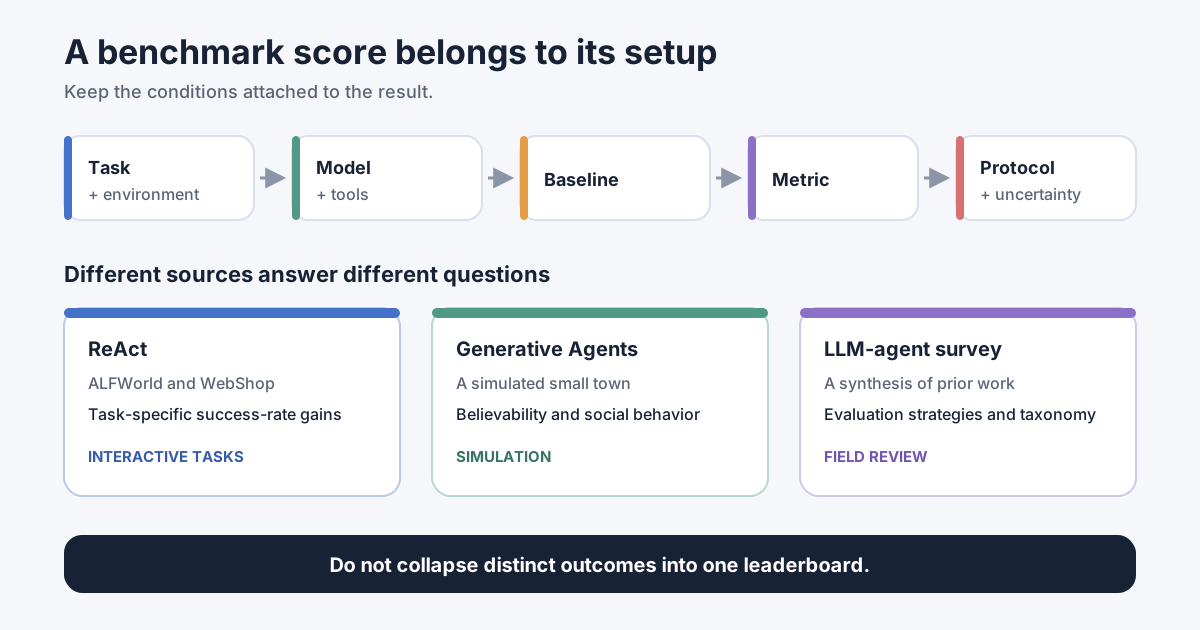
An evidence audit of ReAct, Generative Agents, and a 2025 LLM-agent survey, showing why their task-specific results cannot be combined into one universal success score.
Examine non-linear separability in neural networks—from Minsky’s XOR critique to PyTorch dynamic autograd graphs, weight initialization, and backpropagation.

A source audit analyzing the Hugging Face Open-Source Cookbook, evaluating LLM-as-a-judge, semantic caching, PEFT tuning, and containerized TGI/TEI inference.

A source audit analyzing end-to-end data pipeline architectures, evaluating batch versus streaming ingestion, lakehouse storage layers, and 2026 data stack evolutions.

A source audit analyzing Flutter’s Impeller rendering engine, Dart event loop concurrency, and runtime trade-offs against React Native and native stacks.

A source audit comparing WebGL, WebGPU, and modern neural rendering pipelines, analyzing browser GPU abstraction layers and compute shader evolution.
Search article titles, categories, and tags. Full text is searched when needed.
Type to search articles.